What makes an LLM agent different from a chatbot? Understand tools, feedback, revision and the limits of autonomous workflows.
Figures open at full size. Wide tables scroll sideways.
A chatbot can describe how to resolve a customer’s problem. An agent may look up the account, choose a next step, call a tool and use the result to decide what happens afterward. That change can make the system more useful. It also makes the quality of its feedback, permissions and stopping rules part of the product.
The important architecture question is therefore specific: which part of this workflow benefits from a model choosing its next move? More reasoning steps, more tools and more agents each introduce costs. They need to solve a problem that a simpler workflow cannot already handle well.
Agentic Large Language Models, a survey provides a useful way to separate those choices. Aske Plaat and colleagues organize the field around reasoning, acting and interacting. Their contribution is a map of research and its connections, not a new experiment proving that autonomous agents improve business performance.
The survey’s three categories describe different capabilities:
These capabilities can reinforce each other. Retrieval supplies information for a decision. A tool returns a result that changes the next decision. A second agent can critique an answer. The researchers’ original diagram connects these activities and the data they generate.
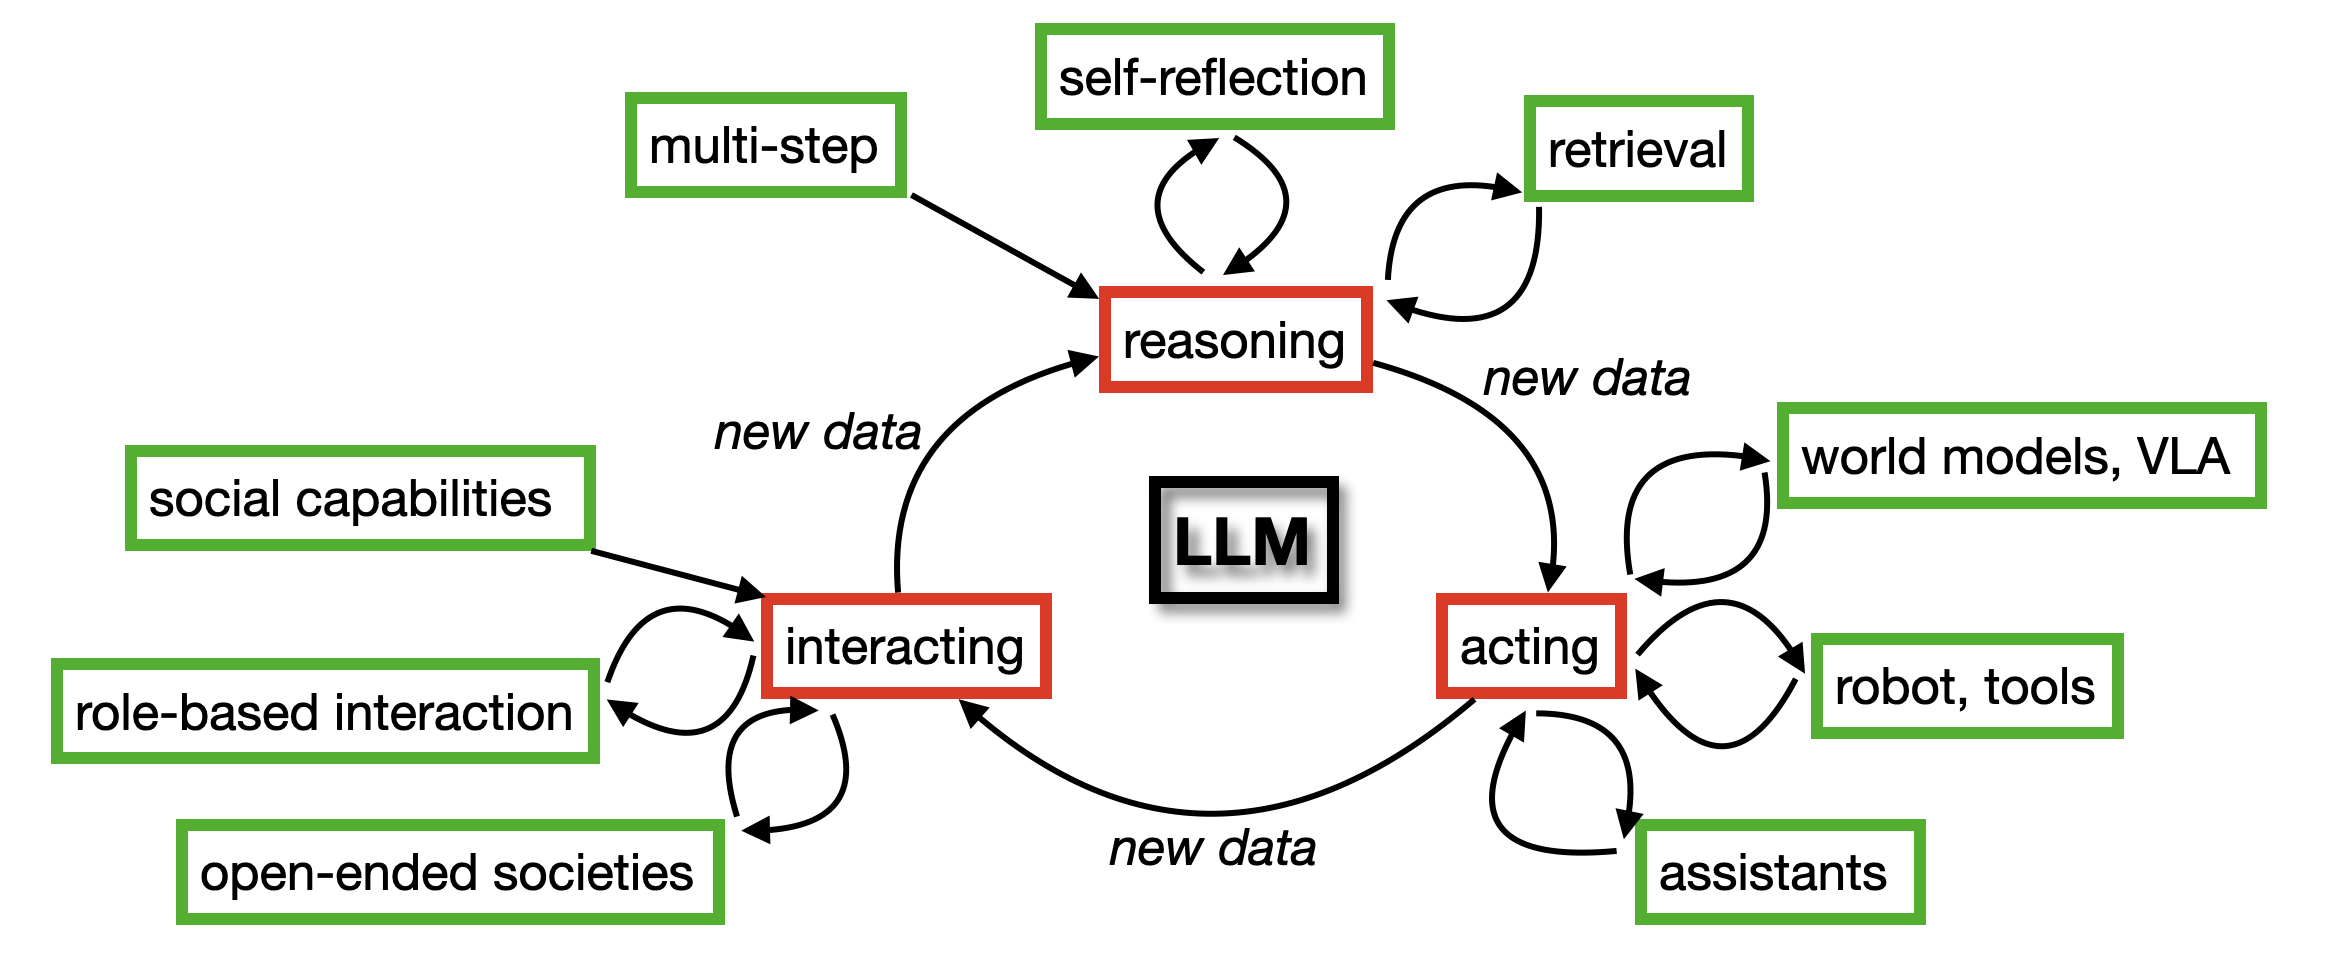
There is a crucial distinction inside this picture. Giving a model another prompt containing its earlier result can change its next answer. It does not update the model’s trained parameters. Turning experience into a lasting change to the model requires a separate training process. The survey identifies that possibility as a research direction and also warns that feeding erroneous outputs back into training can compound errors.
For a product team, that separates two investments: improving the running workflow with useful context, and building a validated data pipeline for subsequent training. Calling both “self-learning” hides the work required for the second.
One concrete method in the survey is Self-Refine. Instead of asking for an answer once, it uses the model in three roles: generate an initial answer, give feedback on it, then revise it using that feedback.
The algorithm reproduced in the survey makes the sequence explicit. The first call receives the task. The feedback call receives the task and current answer. A stopping condition checks whether to finish; otherwise, the refinement call uses the previous answers and feedback to produce another answer. The cycle can repeat.
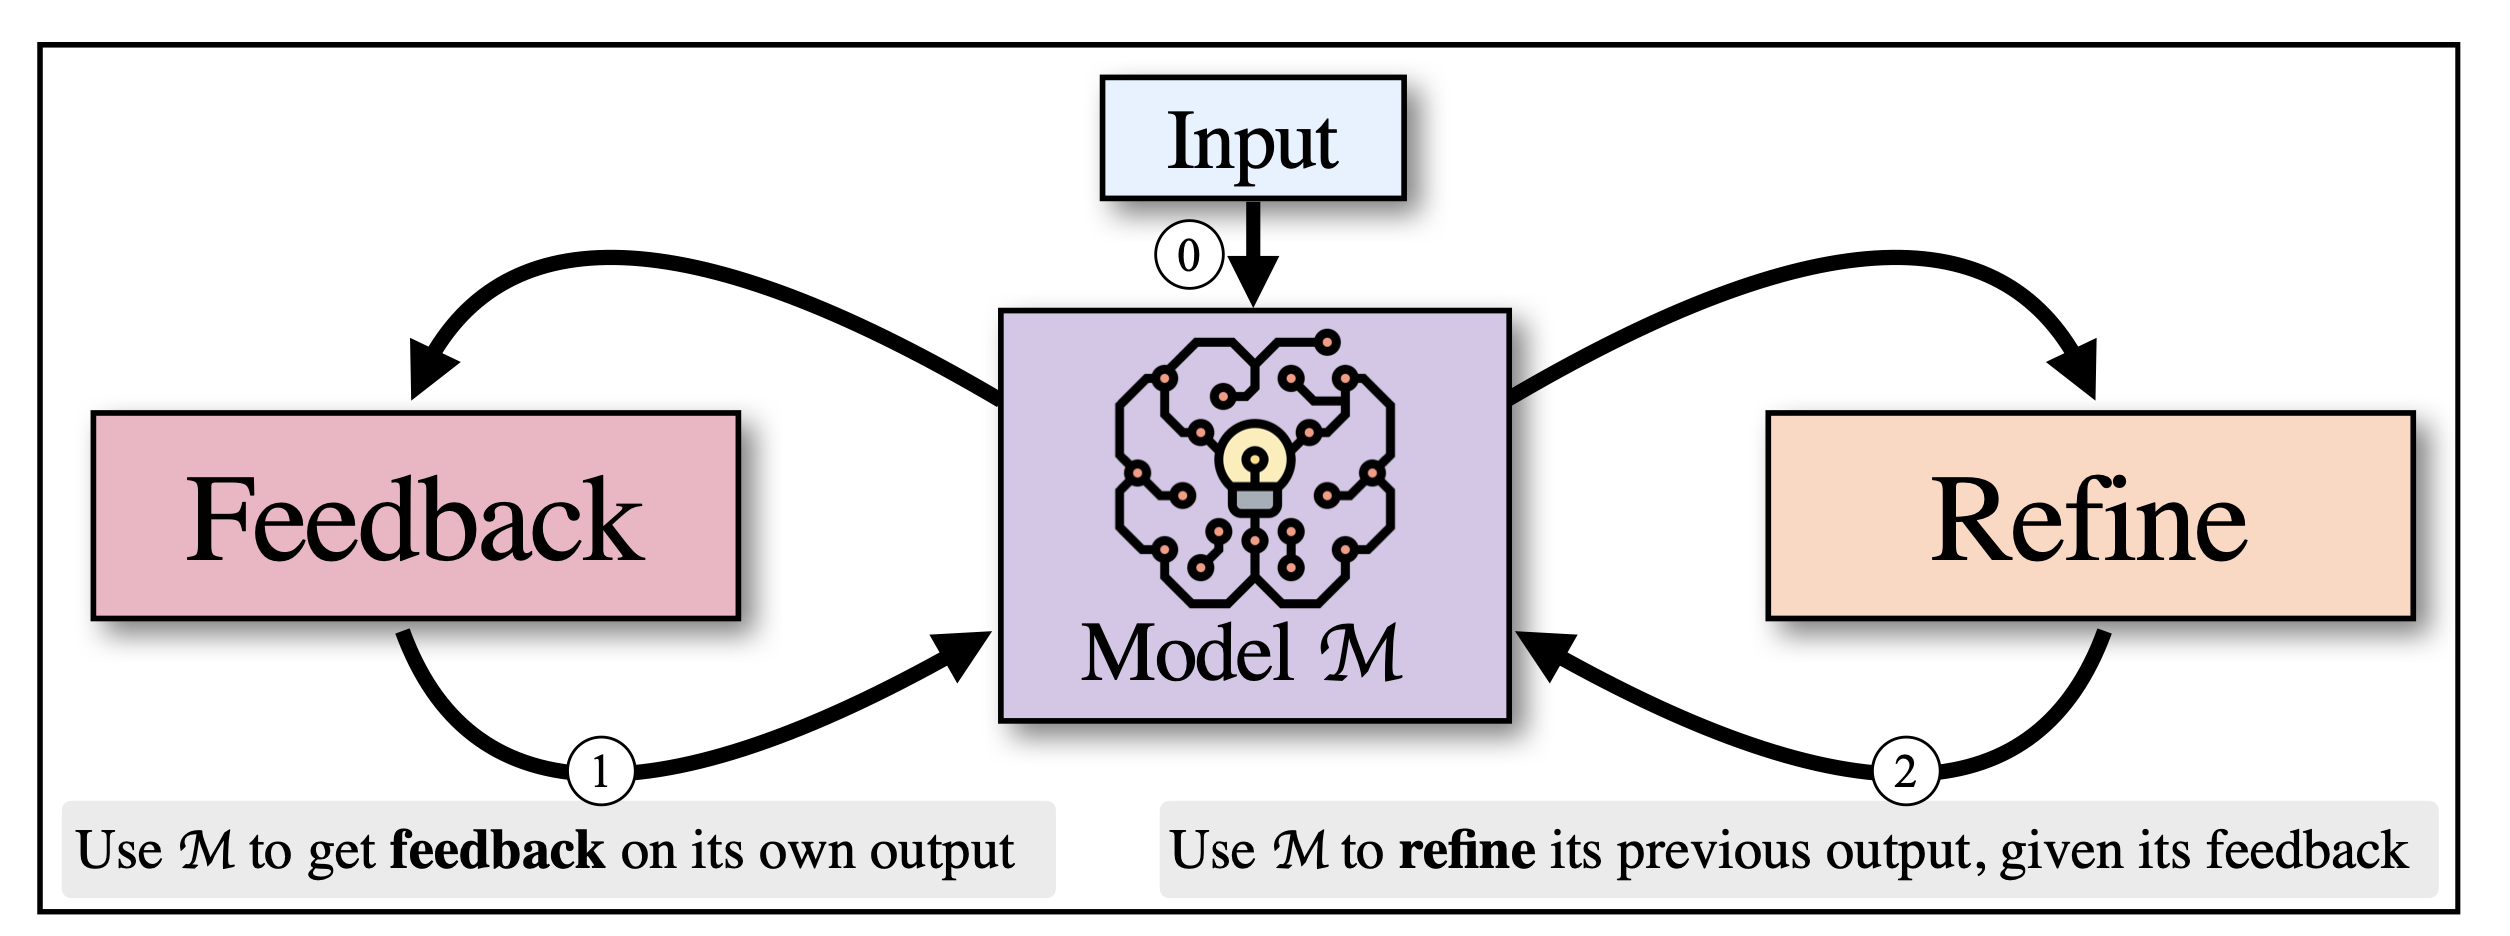
This matters because “try again” and “revise this answer using a specific defect” are different instructions. A feedback step can identify that a response fails a requirement and make that requirement explicit in the next attempt. The survey describes applications including code improvement, dialogue responses and mathematical reasoning. It does not establish that repeated self-critique reliably catches every factual error in an arbitrary business task.
That is the design constraint. If the same model misunderstands the requirement twice, a polished revision may preserve the mistake. For facts or actions you can check, add a check that refers to something outside the generated explanation: a retrieved record, a calculation, a test result or the actual tool response. Also set a limit on attempts. An unresolved case should become visible to the user or operator instead of consuming an indefinite sequence of calls.
The survey’s discussion of SayCan makes a second distinction tangible: a plausible instruction is not necessarily an executable action.
Its original example starts with someone asking for help after spilling a drink. A language model might propose finding a cleaner or using a vacuum. SayCan combines language-based relevance with learned estimates of which robot skills can succeed in its present environment. The illustration shows a plan to find a sponge, pick it up, bring it to the person and put it down.

The surrounding discussion describes evaluation on 101 real-world robotic tasks. That does not establish a success rate for software agents, or guarantee that every action is safe. It shows why information about the environment belongs in action selection.
The software equivalent is straightforward. A refund can be appropriate in principle while being unavailable because the order is outside the permitted window, already refunded or associated with the wrong account. A model’s explanation cannot override those facts. The execution service needs to enforce them using current records and authorization rules.
A related method, Inner Monologue, feeds environmental observations back as language—for example, whether an action succeeded or which objects are present. Its significance is the next decision: the system can respond to what actually happened rather than continue a plan whose assumptions are already wrong.
The survey also covers role-based collaboration. CAMEL assigns complementary roles to model instances that exchange messages toward a task. Other approaches use a creator and critic, or several proposed answers followed by debate. These are different ways to expose alternatives and organize feedback.
The mechanism is understandable: one role produces a candidate, another identifies a problem, and that criticism becomes context for the next step. Separate roles can make responsibilities explicit. They do not automatically create independent evidence. Two instances of the same model can share the same mistaken assumption.
The research picture is also uneven. In the survey’s discussion of Sotopia, GPT-4 struggled with social goals relative to humans. In GovSim, most evaluated models failed to sustain a shared-resource equilibrium. Those findings concern specific simulations, not a verdict on every team of agents. They do show why fluent conversation is insufficient evidence that a group will coordinate successfully. The survey’s interaction section is broader than a claim that adding agents always improves task completion.
For engineering teams, the next question is whether a distinct reviewer catches consequential mistakes better than giving one agent the same information and time. If it does not, the additional orchestration is difficult to justify. Our SagaLLM analysis examines a related problem: keeping shared state consistent when plans change.
A useful first application would be a support assistant that prepares a proposed resolution. This follows from the survey’s mechanisms without requiring an agent to run the entire support function.
Start with a case whose outcome can be checked. The assistant retrieves the relevant account record and policy, identifies missing information, and drafts a response. An external check confirms that cited account facts match the record and that any proposed action meets policy. When a check fails, return the specific failure to the assistant for one bounded revision. Unresolved ambiguity goes to a person.
Keep preparation separate from execution. A proposal to change an account should include the intended change, its evidence and the affected record. Approval and permission checks occur before the write. A fresh read can detect whether the account changed while the proposal was waiting.
This design uses retrieval, feedback and a potential action boundary. It does not need a simulated team of managers, analysts and operators. Add a second agent only if a defined review responsibility proves useful on difficult cases.
Existing application code is a reasonable first implementation. Store the case state, call the model, validate the proposed result and route the case to completion, revision or escalation. Fixed transitions make a small workflow easy to inspect. Your services still enforce permissions, and retries must not repeat an account change.
LangGraph is an option when the workflow needs persistent state and pause/resume behavior. Its official overview describes an orchestration runtime that can combine deterministic steps with model-driven steps. For this example, represent retrieval, drafting, validation and approval as explicit stages. Use a durable checkpointer if a case must survive a restart.
The interrupt documentation supports pausing for external input, but resuming restarts the interrupted node. Keep irreversible side effects outside the portion that may rerun, or make them safe to retry with an operation identifier. The framework manages workflow execution; it does not decide whether a refund is authorized or whether the answer is true.
Before expanding access, compare this workflow with your current support process on the same held-out cases. Have an accountable reviewer assess resolution correctness and whether the proposed action is permitted. Record completion without correction, escalation quality, time, model/tool cost and unauthorized-action attempts separately. Include missing records, conflicting policies, stale state and failed tool calls. A system that improves ordinary drafts but hides failures has not earned broader authority.
The strongest lesson in this survey is architectural. Useful agents connect decisions to information about the world, and make the next decision depend on that information. A longer conversation or a larger collection of roles is not sufficient.
Build the smallest feedback loop that solves a measurable weakness in your current workflow. Expand it when evidence shows that the next capability—another tool, another review stage or greater action authority—improves the outcome enough to justify its cost and failure modes. If a fixed workflow performs as well, keep it.
Agentic Large Language Models, a survey, Aske Plaat, Max van Duijn, Niki van Stein, Mike Preuss, Peter van der Putten and Kees Joost Batenburg. arXiv version 1, submitted 29 March 2025. This article uses that version’s survey and original figures; descriptions of individual methods are attributed through the survey rather than presented as new TechClarity experiments.
Design permissions, checkpoints and recovery before giving an agent more autonomy.
Extend safety testing to the memory, tools and actions surrounding an AI model.
Examine how conversation context becomes the next tool call and its arguments.