How Content ARCs connects AI content provenance, permissions and compensation—and where identification, attribution and governance remain unresolved.
Figures open at full size. Wide tables scroll sideways.
Knowing where a training image came from does not tell an AI developer whether it may be used. A permission record does not establish that the person issuing it controls the relevant rights. And a payment system cannot decide, by itself, how much a creator contributed to a generated result.
Content ARCs separates these problems into Authenticity, Rights and Compensation. The paper by Kar Balan, Andrew Gilbert and John Collomosse proposes a way to connect them using provenance records, content identification, machine-readable licenses and payment mechanisms.
For a team acquiring or distributing AI training content, its value is architectural: it reveals the missing links between systems that each solve only part of the job. It is not an evaluated, ready-to-deploy service that automatically clears every right or calculates a fair royalty.
The framework asks three connected questions about an asset:
A platform can be strong in one area while leaving another unresolved. For example, a signed record can make later changes detectable without proving that its original ownership claim was true. A token can represent access to a dataset without identifying every image inside it. A payment can complete successfully while relying on an inadequate attribution rule.
The authors’ original architecture makes those dependencies visible. Provenance and content identification sit together; licensing depends on identity; value generation follows the resulting rights relationship.
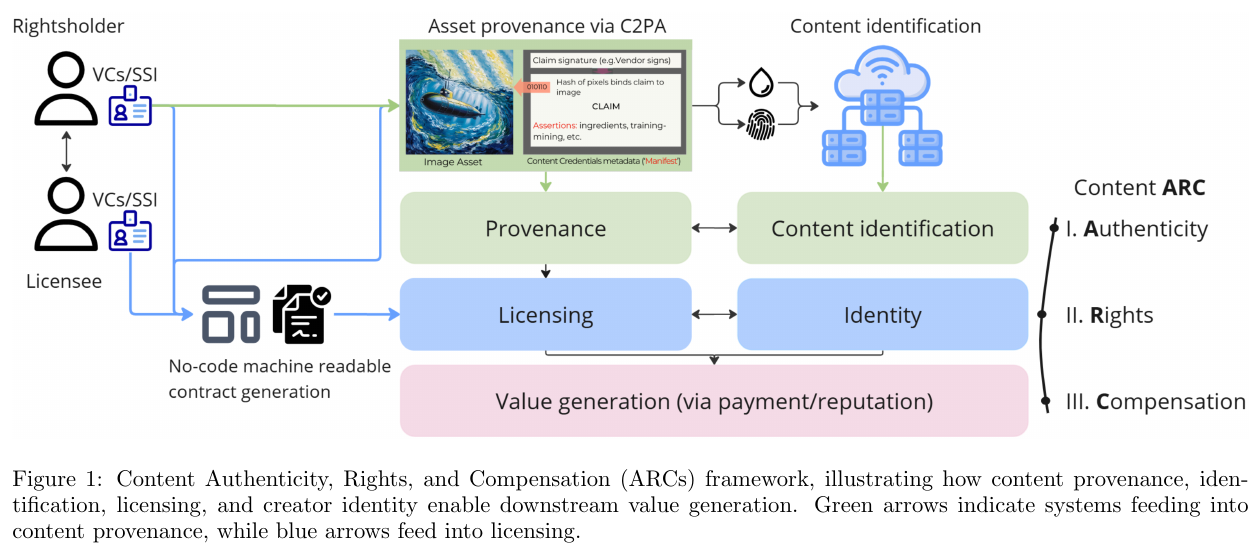
The paper’s starting problem is that content travels. A website can express a policy about its files, but that site-level signal does not necessarily accompany an image copied into another collection. Embedded metadata travels with the file more readily, yet platforms can strip it.
Content identification supplies a possible recovery path. A watermark or fingerprint can help look up a separate registry record associated with the asset. The registry can return provenance and other metadata even when the redistributed file no longer carries it. This is a proposed connection between identification and records—not a guarantee that every edited or recompressed copy will be matched correctly.
Next comes the license. An identified image still needs a record of the permitted use, the parties, applicable conditions and relevant agreement version. The paper proposes open rights-expression standards and a registry of issuance or changes. A ledger can make recorded events tamper-evident, but the system still needs a way to resolve conflicting claims and decide whose assertions to trust.
Finally, a qualifying event can trigger compensation. An agreement might specify a payment when a dataset is licensed or accessed. A more ambitious agreement might distribute revenue from generated outputs among training contributors. The latter adds a difficult question: how should contribution be measured?
These steps explain why “put the rights on a blockchain” is incomplete. A ledger records what was submitted to it. Content matching, identity checks, agreement interpretation, usage reporting and dispute handling still need to work.
This is a framework paper and a comparison of emerging systems. It does not report a controlled experiment showing faster rights clearance, increased creator income or reduced infringement.
Its most useful evidence is the uneven distribution of capabilities across existing approaches. The authors compare systems across content identification, verification, rights representation, identity, attribution and value exchange. The original table below records their assessment at the time of the June 2025 paper; it should not be treated as a current procurement ranking.
| Method | I. Authenticity | II. Rights | III. Compensation | |||
|---|---|---|---|---|---|---|
| Content ID | Verification | Representation | Identity | Attribution | Value Exchange | |
| EKILA (ORA) [29] | C2PA soft binding (fingerprinting and/or watermarking). | Cryptographically signed provenance (C2PA). | NFTs for licenses expressed in natural language. | Ethereum wallet address. | Proportionate attribution via fingerprint for downstream compensation. | Crypto-currency micropayment via SC. |
|
Ocean
Protocol |
Not implemented at the unit (asset) level. | Not implemented. | Data NFTs (ownership) + Datatokens (access rights as ERC-20 sub-licenses). | Ethereum & EVM compatible network wallet address. | Not implemented. | Datatokens (ERC-20) via SC. |
|
Story
Protocol |
Not implemented. Supports watermarked asset specified in metadata. | JSON metadata file and Proof of Creativity (IP provenance graph). | IP asset as NFT (ownership) + License Tokens as NFTs (licensing agreements). | Story wallet address. | Derivative works tracking and fractional royalties distribution through License Tokens. | Royalties distributed via SC in native IP token. |
|
Vana
Protocol |
Not implemented. | Attestations for data quality, but authenticity is not considered. | Tokens represent fractional ownership and governance of DataDAO. | Vana wallet address. | Not implemented. | Distributed via SCs in native VANA token, but only for top 16 DataDAOs. |
| SongBits | Not implemented. | Not implemented. | NFTs represent shares of royalty rights. | SUI wallet address, no additional guarantees for artist identities. | Not implemented. | Distributed via SCs in native SUI token. |
|
JPEG
Trust [19] Draft v2 |
C2PA soft binding (fingerprinting and/or watermarking). | Cryptographically verifiable provenance information through the Trust Profile (JSON-based schema). | Open digital rights language (ORDL) and Trust Manifest checking. Rights registry. | Verifiable Credentials / DIDs (CAWG). | Not implemented. | Not implemented. |
|
Fox
Verify |
Cryptographic hashing and fingerprinting. | Cryptographically signed provenance data (non-standard). | Licenses are implemented as logic within SCs. | Custom identity registry SC links cryptographic key pairs to real-world identities. | Partial implementation via ContentGraph and perceptual hash, but no automated downstream compensation. | License sales via SC in MATIC (Polygon DLT) token, no downstream royalties. |
The paper’s discussion of EKILA and the ORA framework illustrates the distinction between assembling components and resolving the entire problem. In the authors’ account, signed provenance helps describe assets, token-based licenses represent rights, image similarity supports attribution, and smart contracts support micropayments. Yet the license details can remain free text rather than a standardized rights expression, and similarity-based attribution does not establish causal contribution.
That example is valuable because it shows where integration can stop short. A system may recognize content and deliver a payment while still lacking a common, machine-interpretable account of the agreement or a defensible way to allocate value. The paper’s system comparison identifies these gaps rather than demonstrating a universally complete solution.
Suppose a generated image resembles several images in a training collection. Similarity may identify relevant candidates, but it does not establish how much each one caused the output or what each contributor should receive.
The paper distinguishes correlation-based attribution from approaches intended to estimate causal contribution. It discusses watermark-based methods and contribution analysis, while identifying scale as an unresolved obstacle for datasets containing billions of items. It does not demonstrate a broadly scalable, causally justified payout mechanism.
This matters when designing a commercial process. A fixed payment for licensed access and an output-dependent royalty are different products with different measurement requirements. The first can be tied to a recorded contractual event. The second needs an agreed attribution and allocation method, plus a way for contributors to question it.
For a broader look at what an auditable explanation needs to preserve, see our guide to causal reasoning in AI fairness audits.
The technology can execute the selected rule. Whether that rule is acceptable to creators and licensees is a separate design and governance question.
For a publisher, stock-media platform or AI data-acquisition team, the immediate use of Content ARCs is a gap analysis. Trace a sample asset from acquisition to its proposed use, then through any payment obligation. Identify where the record becomes ambiguous or the responsible party changes.
A practical review might ask whether the system can recover the asset’s record after metadata removal; distinguish a modified copy from an unrelated match; show which agreement version applied to a use; and reconcile a payment with the event that triggered it.
Updating a registry entry should not silently rewrite the historical agreement. The application needs to distinguish current offers from previously accepted terms, and future-use restrictions from completed uses. Content ARCs raises the need for this lifecycle; it does not supply a universal answer to the contractual effect of each change.
The paper also questions whether decentralized infrastructure is enough without governance. Someone must operate discovery services, respond to disputed records and handle failures. A platform with clearly assigned responsibilities may be a better initial setting than a cross-industry network whose participants have not agreed on these rules.
Use provenance standards for provenance. The C2PA explainer describes signed content credentials and their validation. A team can use that model to preserve origin and editing assertions and detect changes to the bound record. It should separately assess the issuer and the assertions: a valid signature is not a copyright determination or proof that everything stated is true.
Use a rights-expression model for the permission record. W3C’s ODRL model represents permissions, prohibitions, duties, parties and constraints. It can provide a shared structure for an application’s usage policies. It does not itself run your authorization checks, settle ownership disputes or collect payments. Start with a small vocabulary of uses your application actually supports and make the agreement and its machine-readable representation consistent.
Choose registry and settlement mechanisms around the participants. An existing database and payment service may suffice for a single operator with established agreements. A shared ledger may be relevant where several parties need a common record without relying on one operator. Neither choice eliminates identity, correction or dispute requirements. Avoid adding output-level attribution before you have a reason and a validated method to support it.
A bounded implementation exercise can follow one asset type and one use:
Success means the participating teams can explain what happened to each test asset and why. It does not require claiming that the prototype resolves every form of AI attribution.
Content ARCs is most useful as a test of completeness. Provenance, licensing and compensation should be examined together, but each requires different evidence and different operational controls.
We would use the framework to make a narrow content workflow auditable before committing to an expansive rights marketplace. The authors themselves identify missing field feasibility studies and unresolved interoperability, identity and attribution problems. Demonstrated operation across independent participants, with workable dispute handling and credible compensation rules, would justify a stronger recommendation.
Kar Balan, Andrew Gilbert and John Collomosse, Content ARCs: Decentralized Content Rights in the Age of Generative AI. Version 3, 12 June 2025. Original figure and table are reproduced with attribution under CC BY 4.0; platform descriptions reflect the paper’s historical assessment.
Explore why indirect descriptions can bypass name-based image safeguards.
Evaluate whether a model reveals membership in its training data, regardless of architecture.