CodeScribe combines dependency context, prepared drafts and LLM translation for Fortran migration. Learn from its code failures and verification workflow.
Select a figure to open it at full size.
A scientific codebase is more than its programming language. It contains numerical assumptions, array conventions and dependencies that may have accumulated over decades. Translating the syntax is useful only if the resulting program still computes the intended result.
Akash Dhruv and Anshu Dubey’s CodeScribe research examines how language models can assist that work. Their workflow combines a structural index of the project, a prepared draft, conversion instructions and developer review. The motivating application is MCFM, a Fortran program used for particle-interaction calculations; another application connects a Fortran atmospheric-modeling library to C++ software.
For scientific-computing teams, the practical question is not whether an LLM can emit C++. It is whether preparing better context reduces the work required to obtain a correct, integrated translation.
A file translated in isolation often refers to functions and data structures defined elsewhere. Without that context, a model may invent missing implementations, redeclare functions as variables or produce a demonstration program that does not belong in the project.
CodeScribe first indexes the source tree. YAML records describe files, modules, subroutines and functions; an inverse lookup connects a referenced construct to the file defining it. That information helps the tool prepare a preliminary C++ draft with appropriate declarations and comments about external dependencies.
The model receives the original Fortran, that draft and a conversion template containing rules and examples. It generates both C++ source and the associated Fortran-C interface. The output is then reviewed, compiled and tested, with failures leading to correction or revised instructions.
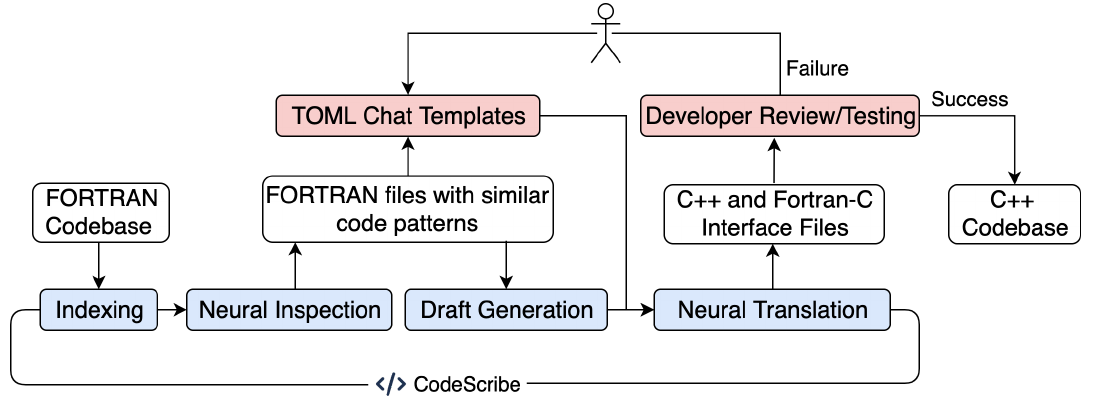
The preparation is consequential. A draft is not just a second attempt at the translation: it supplies project-specific constraints that a general language model would otherwise have to guess. The index also lets a developer inspect unfamiliar source before deciding which conversion rules belong in the template.
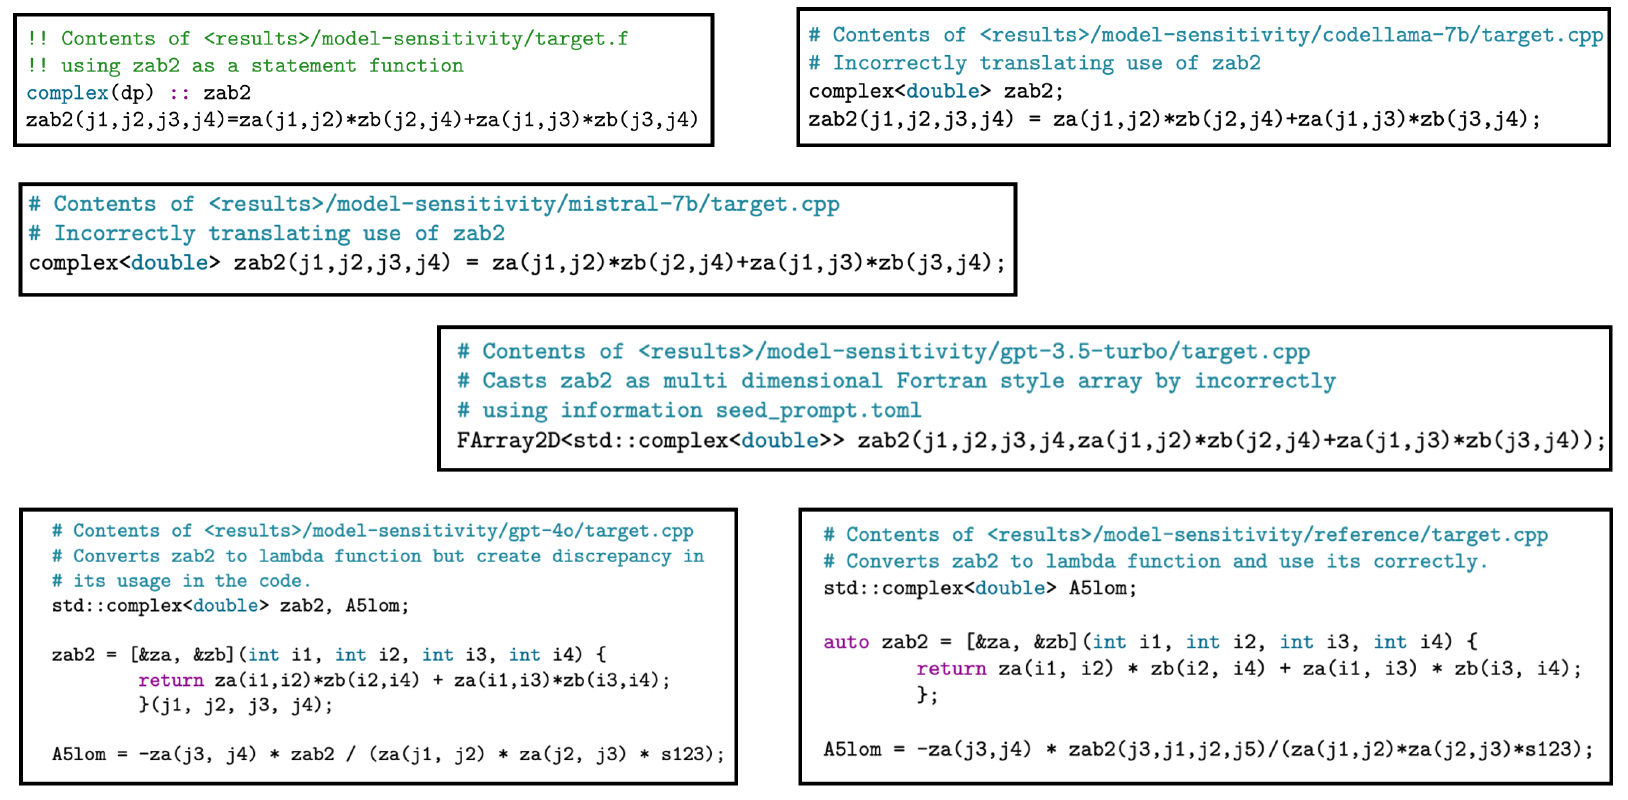
The paper’s worked comparison concerns a Fortran statement function named zab2. Its role is to calculate an expression from arguments. A faithful translation must preserve that callable behavior, not simply preserve the spelling of the identifier.
Several tested models mishandle it. One output leaves an unsuitable declaration; another interprets the construct as a multidimensional array. GPT-4o writes a lambda expression but immediately executes it with j1, j2, j3, j4, storing the resulting number in zab2. Later, it reuses that number. The reference instead keeps zab2 as a callable function and invokes it at the later calculation with j3, j1, j2, j5. The generated version has lost the ability to recalculate the expression for that different set of arguments.
The original excerpt makes the failure concrete. A translation can look structurally sophisticated and still break the relationship between a definition and its use.
The dependency example elsewhere in the paper adds another failure mode. Functions such as lnrat, L0, L1 and Lsm1 are declared in a way that the Fortran toolchain can resolve during linking. In C++, blindly treating those names as ordinary variables leads to problems. The indexed draft tells the model that they are external functions. This improves the generated result, although the authors still observe inconsistent behavior despite explicit context.
The lesson is specific: retrieval should supply the missing semantic relationship, not merely add more source text to the prompt.
Array indexing is another recurring difficulty. Fortran commonly uses one-based indexing, while ordinary C++ arrays begin at zero. Translating a complex access pattern requires more than subtracting one from the most visible index; bounds and indirect references must remain consistent.
The authors use custom FArray container classes to support Fortran-style one-based access from C++. That is a deliberate migration choice: preserve familiar indexing behavior first, rather than combine language translation with a comprehensive redesign of data access.
For a team maintaining numerical software, this suggests separating two projects. Establish a behaviorally equivalent translation, then decide which data structures or algorithms should change. Combining both can make a numerical discrepancy much harder to diagnose.
The authors report that their MCFM conversion initially progressed at roughly two to three files per day and later reached ten to twelve with CodeScribe. That is an observation from their development process, not a controlled estimate of the improvement another team will achieve. The paper describes the MCFM conversion as completed at the time of writing, while the Noah-MP interoperability work remains ongoing.
A model comparison measures developer review and testing time for a single source file. CodeLlama-7B requires 13.8 minutes of review and seven minutes of testing in that example. GPT-3.5 Turbo requires 4.26 and 2.3 minutes respectively; GPT-4o reduces review to 2.5 minutes, with comparable testing time. The original chart illustrates how generation quality affects the work that follows.
The useful result is that fewer and more localized mistakes can reduce integration effort. It is not a current model ranking, a general 80% productivity claim or evidence that months of migration disappear into hours. The experiments use the models and settings of that study, including a 4,096-token output limit.
The paper also does not make model output self-verifying. Developers still supply conversion rules, recognize semantic errors and test the result. A compiler catches some mistakes; it cannot establish that a changed calculation preserves the scientific meaning.
Start with a coherent group of routines whose inputs and outputs can be captured. Save representative outputs from the existing implementation, including boundary cases and behavior near numerical tolerances. Document array layout, precision and external dependencies before translation.
Prepare the dependency index and conversion template for that group. Translate it, compile it with the surrounding system and compare numerical results against the preserved baseline. When results differ, distinguish an interface mistake from a floating-point difference and an actual algorithm change. The acceptance tolerance should come from the scientific computation, not from what makes the generated output pass.
Measure total developer time: preparation, generation, correction, review and testing. Lines emitted per second are a poor proxy for migration progress. A tool that produces more code but makes discrepancies harder to locate may increase the project’s cost.
Also consider whether an interface is sufficient. If the objective is to use a modern C++ library alongside reliable Fortran routines, a narrow interoperability layer may deliver the required integration without translating the full codebase. The paper’s Noah-MP work illustrates that alternative.
This is related to the issue in AI-generated SQL: runnable output and correct meaning are separate gates. Scientific migration adds numerical behavior and cross-language interfaces to that distinction.
The CodeScribe repository is the starting point for the tool. Its current project has evolved beyond the paper’s original CLI, so distinguish reproducing the published experiment from adopting the latest implementation. Pin the version, model configuration and conversion instructions used for a pilot.
The study’s four-stage structure—index, inspect, draft and translate—is useful even with existing tooling. A parser or dependency index can establish where constructs are defined; a controlled template can state conversion rules; the language model can perform the proposed translation. Your existing build and numerical regression suite remain the acceptance system.
For incremental interoperability, use the language’s C-binding facilities and explicitly reviewed matching data structures. Do not assume that similarly named types share the same memory layout or ownership behavior. Test creation, access, updates and cleanup across the boundary.
A minimal pilot should finish with one integrated, reproducibly tested unit and a record of every human correction. Those corrections reveal which rules belong in the next template and which classes of error still require expert judgment. The reference outputs in the paper are valuable examples of that process, rather than evidence that copying a prompt is sufficient.
CodeScribe makes a credible case for improving the context and workflow around code generation. The index, prepared draft and verification loop are at least as important as the chosen model.
We would use it to accelerate bounded migration work with strong numerical tests. We would retain working Fortran where replacement has no clear benefit, and judge the tool by verified integration effort rather than the volume of code it produces. Modernization succeeds when the scientific capability becomes easier to maintain without losing its meaning.
Leveraging Large Language Models for Code Translation and Software Development in Scientific Computing, Akash Dhruv and Anshu Dubey. arXiv version 2, March 17, 2025; prepared for PASC 2025.
See why executable SQL still needs checks against the business question and intended metric.
See why generated motion-control code needs behavioral checks beyond valid syntax.





