Adaptive inference needs tested backends, routing and coordinated scaling. Learn from controlled accelerator shortages and build a useful failover test.
Select a figure to open it at full size.
The cheapest accelerator for an inference workload is not always available when demand arrives. A platform that routes everything to that device can save money in a steady test and still leave requests waiting during a capacity shortage. Buying a second kind of accelerator does not solve the problem unless the software knows when and how to use it.
Yahav Biran and Imry Kissos, researchers at Amazon, examine that coordination problem using Stable Diffusion 2.1. Their proposed system combines independently prepared model deployments, measured throughput limits, traffic routing and Kubernetes scaling. The central idea is to prefer economical capacity while retaining a tested path to alternatives.
The paper treats a deployment as a combination of model, hardware and execution framework. The same model can have different throughput and latency on the same device when its runtime changes. Conversely, a model prepared for one accelerator is not automatically executable on another.
This distinction gives the architecture its practical shape. Each supported combination has its own model-serving application and hardware requirements. A load balancer sends requests to those applications. Scaling software can then add application replicas and provision the appropriate machines underneath them.
Before routing production traffic, the authors load-test each combination to find how much work it can accept while maintaining their latency target. That measured operating point becomes a scaling input. An accelerator with a lower hourly price might still be expensive per completed request if it serves too little useful work; a faster device can also be a poor choice if it spends most of its time idle.
The study evaluates NVIDIA A10G and L4 hardware alongside AWS Inferentia and Trainium. Its experimental setup is a specific model-serving system on AWS. It does not demonstrate that arbitrary models can move unchanged across every cloud, CPU or accelerator.
The first control decides where requests go. The cost-oriented policy favors deployment options according to their measured economics. The capacity-oriented policy spreads work across available options when the preferred capacity cannot satisfy demand.
The second control decides how many model-serving replicas to run. KEDA supplies metrics to Kubernetes’ pod autoscaling machinery. More requests should lead to more ready model servers, with targets chosen from the load tests rather than a generic utilization percentage.
The third control decides which machines to provision. Karpenter manages node capacity subject to the configured hardware choices and constraints. It supplies somewhere for the additional pods to run. It does not translate the model into another accelerator’s runtime, and provisioning a machine does not mean its model is already loaded and ready.
These controls operate on different timescales. A routing change can send traffic elsewhere quickly; downloading, loading or compiling a model takes longer. A working fallback therefore requires a ready destination and enough capacity, not merely a configuration entry naming another instance family.
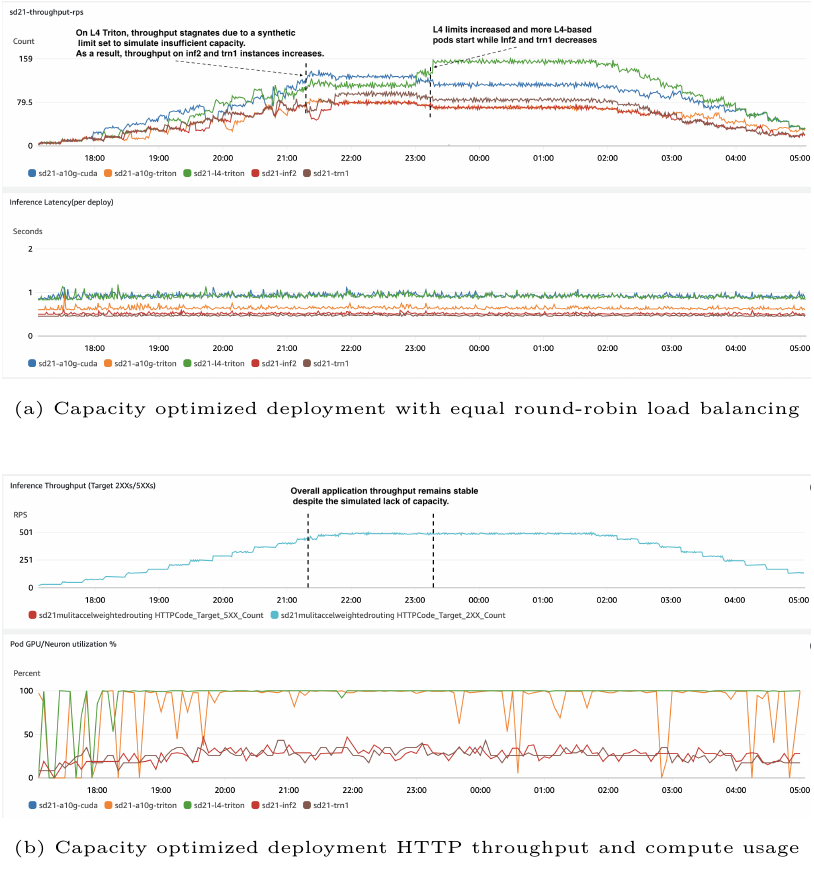
In one experiment, the authors artificially limit L4 capacity while demand rises. Its throughput flattens, and other deployments take more load. When the limit is lifted, additional L4-backed pods can be deployed. The original graphs show both the changing contribution of each deployment and the overall throughput profile.
A second experiment joins the policies into a feedback loop. On the chart’s November 14 interval, simulated insufficient Inf2 capacity triggers a switch away from the cost-oriented allocation. Other configurations carry more of the workload. On November 15, the controller detects restored Inf2 capacity and returns to the cost-oriented setting.
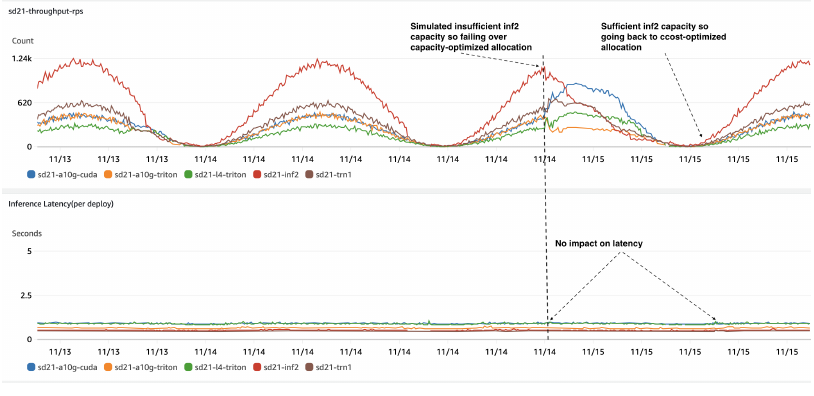
The relevant evidence is that the system changes the mix of serving deployments while the reported latency remains relatively steady. That is more informative than comparing chips in isolation: it tests whether the control loop responds to a capacity event.
The study does not, however, provide the range of failure trials, workload descriptions and end-to-end cost accounting needed to forecast a particular company’s savings. Its pricing-derived table entries also need more unit clarity before they can be used as per-request economics. Use the experiment as a design demonstration, then measure costs on your own request distribution.
Two backends can accept the same request and differ in numerical behavior, supported settings or output quality. Selected generated images are useful smoke tests, but they do not establish equivalence across prompts. Before treating backends as interchangeable, test the settings and outputs the product actually depends on.
A second risk is oscillation: the cheapest pool becomes briefly available, traffic moves back, capacity tightens again, and the controller repeatedly changes direction. A recovery policy needs evidence that capacity has stabilized. A third is incomplete accounting. Warm fallback machines, duplicate model artifacts and time spent loading models all cost something even when the nominal preferred device looks economical.
These are implementation questions derived from the architecture, rather than failures quantified by the paper. They determine whether the proposed flexibility pays for its operational complexity.
The authors’ hardware-agnostic inference repository supplies an AWS implementation using accelerator-specific images and model pipelines. It is useful as a reference for separating serving deployments and routing policies. Review its settings before reuse; sample infrastructure is not a universal production configuration.
KEDA handles event- or metric-driven application scaling through Kubernetes’ Horizontal Pod Autoscaler. Karpenter NodePools express the constraints for provisioning machines. They are complementary: one scales the application, the other supplies eligible infrastructure. The routing controller is a further part of the design.
A useful first experiment needs only two backends. Prepare and validate the same model on both, replay representative requests, and determine a safe throughput target for each. Keep the existing single-backend service as the baseline. Then restrict the preferred pool, observe queueing and tail latency, and test recovery while preserving output-quality checks.
Record cost per successfully completed request, rejected or retried requests, time to ready capacity, and performance during the transition. Include warm standby costs. If availability improves but the operating burden is large, a simpler fixed fallback may be preferable to continuously adjusting cost weights.
For related context on hardware-aware optimization, see our discussion of AI models and functional safety, where system behavior matters beyond a model’s isolated score.
The value of heterogeneous inference is optionality that has been exercised under load. A collection of supported accelerator names is not that capability.
This research offers a credible architecture for testing it: benchmark complete serving configurations, distinguish routing from scaling, and deliberately remove preferred capacity. Adopt the additional machinery when those tests show a worthwhile improvement over a simpler service—not because hardware diversity alone promises lower costs.
Adaptive Orchestration for Large-Scale Inference on Heterogeneous Accelerator Systems: Balancing Cost, Performance, and Resilience, Yahav Biran and Imry Kissos. Version 2, March 27, 2025. Original Figures 6 and 7 reproduced for analysis.
Compare the cost of communication between stages with the parallelism lost by combining them.
Measure the workload and energy used before making an AI sustainability claim.





