What a Sierra Leone teacher chatbot study shows about low-bandwidth AI, answer usefulness, factual errors and sustained adoption.
Select a figure to open it at full size.
An answer can exist online and still be difficult to use. A teacher with a small phone, intermittent connectivity and a limited data budget may have to download a large document to find a few paragraphs relevant to tomorrow’s lesson.
A study of 529 teachers in Sierra Leone examines whether an AI assistant delivered through WhatsApp can reduce that friction. Over 17 months, teachers submitted 40,350 queries. The research compares those responses with web pages surfaced by local Google searches and asks other teachers to assess their usefulness.
The strongest finding concerns access and packaging: short, tailored text can make information much cheaper to retrieve. The study does not establish improved student learning, universal factual reliability or operation without an internet connection. For product teams, it offers a detailed example of designing around a user’s actual constraints.
The service, theTeacher.AI, appeared as a WhatsApp contact. A teacher sent a message; a backend passed the conversation and education-specific instructions to GPT-3.5 Turbo; the response returned through WhatsApp. The model named here is the one used during the study, not a recommendation for a new deployment.
The system description and appendix prompt explain several consequential choices. Responses were supposed to use short, simple language, remain within primary and secondary education, consider limited classroom resources and ask for clarification about students’ ages or available materials when necessary. Teachers also received onboarding and practice, rather than merely being handed access.
This was a cloud-connected text service. It was not an SMS-only, offline or federated-learning system. Those distinctions affect what a team must budget for, how information moves and which users can actually reach it.
Most requests were relatively ordinary information needs. The authors’ classification put 69% in facts and concept clarification, with 11% in lesson planning and assessment. The interesting opportunity was not limited to sophisticated tutoring: even a concise explanation of a familiar topic could be easier to obtain through chat than a conventional search journey.
One appendix example asks how to teach fractions to eleven-year-old pupils in Sierra Leone. The AI response suggests visual representations, sharing familiar objects and hands-on activities involving equal parts. It contains 123 words and requires 844 bytes in the study’s measurement.
One of the search results is a local education ministry mathematics lesson-plan PDF. It contains much more material: 50,352 extracted words and a download of 2,234,701 bytes. The local document is not inherently a worse educational resource. It has a different purpose and may contain curriculum authority that a generated answer lacks.
The mismatch is between the immediate task and the delivered package. The teacher asks for help with one lesson and receives either a short answer or an entire document to navigate. AI can reduce that navigation burden, but a product that connects concise answers to the authoritative curriculum could preserve something valuable from both.
This example also keeps the argument grounded. The study is not showing that the model discovered new educational knowledge. Much of the value lies in selecting and formatting information for the person asking.
Across the sampled responses, the authors report an average of about 0.8 kilobytes for AI response text, versus 2,499 kilobytes for a web page. Their reported ratio is 3,107 to one. The web measurement includes resources loaded with the page, such as scripts, images, styles and documents—not just the words visible on screen.
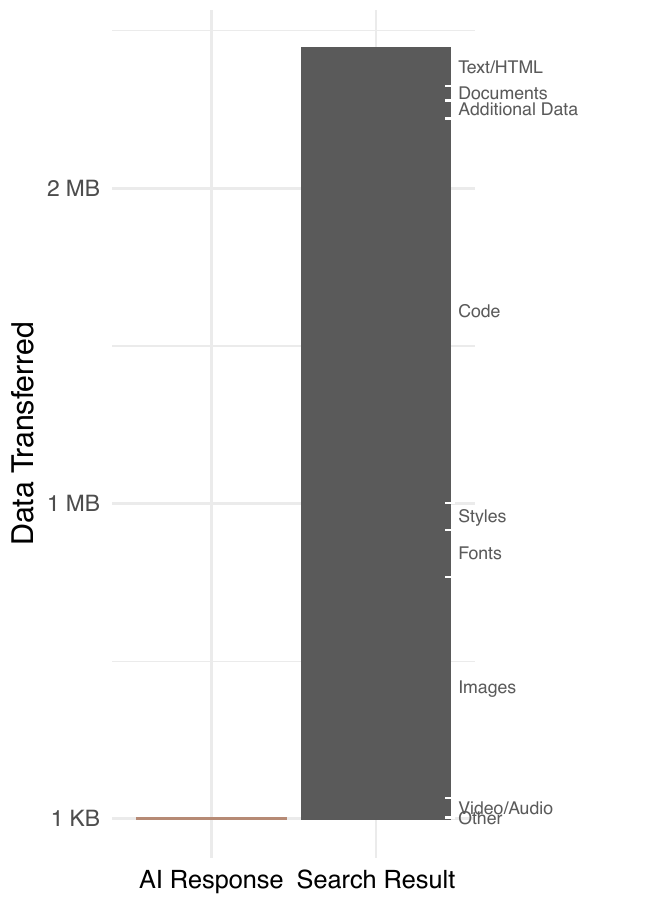
The chart makes bandwidth a product requirement rather than an infrastructure afterthought. A service can have a strong answer and still fail because reaching it requires too much data or too many steps.
There are boundaries to the comparison. The researchers excluded some results because of paywalls, non-text content or scraping problems. They compared against ordinary browser-based search results, not every possible compressed or text-only search design. AI content and the chat interface were bundled together, so the study does not isolate how much of the advantage came from generation versus delivery.
The paper also models bandwidth and model-compute costs using historical prices. That is useful for explaining the economics, but it is not a current quote for operating a teacher-support program. Messaging charges, hosting, support, onboarding and content review must be included in a real deployment budget.
For the quality comparison, the researchers recruited 25 teachers from around the world. Each assessed ten query-response pairs drawn from a sample of 100 queries. The response shown was either the AI answer or the extracted text of one randomly selected result from the top five search results. The source was concealed.
On a five-point scale, AI responses were rated 1.23 points more relevant and 1.12 points more helpful. Evaluators also flagged inaccuracies less often: 10% for AI responses versus 31% for search-result text.
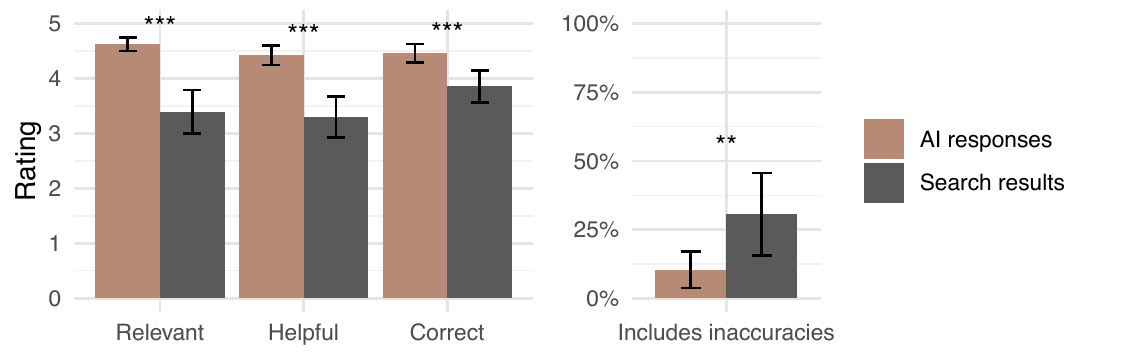
The comparator matters. A single web page may be useful as one source in a search process without being a complete answer to the question. Evaluators sometimes treated irrelevance or an incomplete answer as a problem with correctness. The result supports the usefulness of direct answers in this setting; it does not prove that the model is more factually reliable than careful research across multiple sources.
Nor did the AI responses avoid errors. The researchers independently verified at least three hallucinations in the sampled 100 responses. A teacher who cannot easily check a generated answer may benefit from its convenience while becoming more exposed to a confident mistake.
That is why a low-bandwidth product still needs a way to show where important claims come from and route uncertain questions to a better source. Removing friction should not remove the reader’s ability to challenge the answer.
Usage was sustained for some teachers, but the median teacher submitted only 2.4 queries per month and used the service on 0.9 days per month. The proportion active fell from 62% in the first month to roughly 19% by month seventeen.
Those figures are a more useful product signal than the total query count alone. The service addressed real needs, yet it did not become a frequent habit for most participants. The study cannot determine whether declining use reflects satisfied needs, access barriers, disappointment or some combination.
The population also matters. This was an English-language deployment, with training, among teachers given access through participating schools. It does not demonstrate equivalent performance in lower-resource languages or among users who receive no onboarding. The researchers did not observe classroom use closely enough to establish changes in teaching practice or student achievement.
The adoption lesson is to investigate who stops using the service and why. A high cumulative message count can coexist with a product that leaves many intended users behind.
The authors link their FabData-LLM repository, which provides abstractions for model APIs, stored chat history and token management. It is a useful starting point for understanding the model-facing portion of the design. It is not a complete, ready-to-deploy WhatsApp education service; messaging integration, access control, content policy and operational support remain separate responsibilities.
For a small pilot, existing backend code can also manage a message queue, a bounded conversation history and a model call. The difficult requirements are mostly product and evaluation choices:
The paper’s prompt instructions are an artifact to study, not a guarantee that a model will obey them. Our guardrails analysis examines why safety and usability need their own tests.
The research makes a strong case for treating bandwidth, language and presentation as part of the AI system. A more powerful model is not automatically a more accessible product.
The next useful experiment is narrower than “replace search with AI”: deliver a concise, locally useful answer through a channel people already use, preserve access to authoritative sources, and test whether the whole service remains useful after onboarding. The evidence supports that product direction. Claims about educational transformation need the additional classroom evidence the study does not yet provide.
Daniel Björkegren, Jun Ho Choi, Divya Panchaksharappa Budihal, Dominic Sobhani, Oliver Garrod and Paul Atherton, Could AI Leapfrog the Web? Evidence from Teachers in Sierra Leone. arXiv:2502.12397v3, 2 December 2025. This revision uses the expanded study, including its supplementary examples, methods and limitations.
Ask whether an explanation improves the user’s next unaided decision.
See what user reviews suggest about recovery, control and satisfaction with AI products.





