PatchCore detects unusual product images using a memory of normal patches. Explore original diagrams, missed defects and practical inspection checks.
Select a figure to open it at full size.
A manufacturer often has far more images of acceptable products than examples of every defect that might occur. That creates a different problem from ordinary image classification. The system must notice something unusual without having seen a labeled example of that particular fault.
PatchCore, developed by Karsten Roth and colleagues, tackles this problem by building a memory of normal visual patterns. A new product is suspicious when part of its image looks unlike the normal patches in that memory. The method is useful to understand because its strengths and its failure cases both follow from that design.
This revision focuses on AI visual inspection. It replaces the earlier discussion’s unsupported connection between acceptance-sampling research and AI performance. Detecting an unusual image and deciding whether to release a production batch remain separate quality decisions.
A whole-image description can hide a small scratch inside a mostly normal product. PatchCore instead extracts local features from a pretrained image network, using intermediate layers that retain useful visual detail. Nearby features are aggregated to give each patch some surrounding context.
The training images contain normal products. Their patch representations form a memory bank. During inspection, each patch from the new image is compared with the closest normal representation in that bank. A large distance means that the patch is unusual relative to the stored normal examples.
Those distances serve two purposes. They create a heatmap showing where the image differs from normal, and they contribute to an image-level anomaly score. The system’s scoring gives particular importance to the most anomalous region, with an adjustment based on its neighborhood in the memory bank.
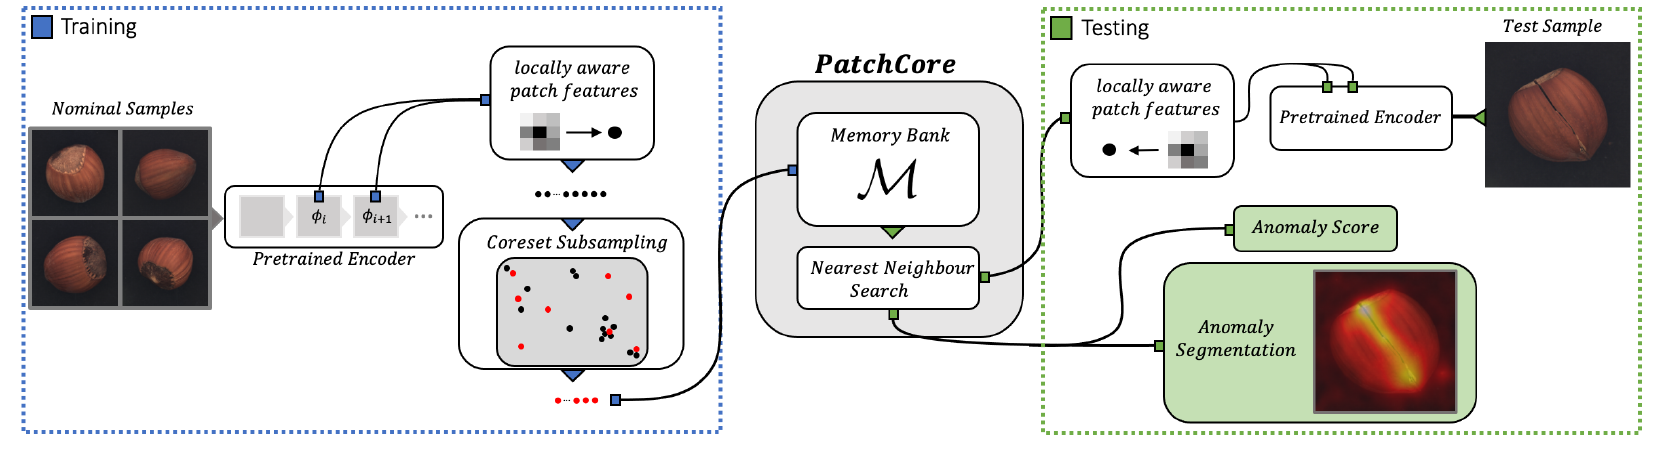
A simple example makes the distinction clear. If normal metal surfaces contain a range of harmless textures, the memory needs to represent that variation. A scratch is detectable when its local representation differs sufficiently from those normal textures. The method does not know, by itself, whether the difference violates an engineering tolerance. It knows that the appearance is unusual.
Keeping every patch makes comparison expensive. Keeping random patches can discard rare but acceptable appearances, causing unnecessary alarms. PatchCore uses a selection procedure designed to cover the normal feature space with a smaller representative set, called a coreset.
The selection repeatedly adds examples that improve coverage of the existing patch representations. The goal is not to remember only the most common appearance. It is to preserve the range of normal appearances while reducing the number of comparisons at inspection time.
That mechanism explains an important operating requirement: the normal training set must include legitimate variation. A compact memory cannot preserve a camera angle, material finish or lighting condition that was absent from the data in the first place.
The principal evaluation uses MVTec AD, a benchmark with 15 object and texture categories. It contains 5,354 images, including 1,725 test images. The authors evaluate both whether an image is anomalous and where the anomalous region lies.
With a memory containing 25% of the available patch features, PatchCore reports an image-level AUROC of 99.1%. A 1% memory reports 99.0%. AUROC measures how well scores rank anomalous images above normal ones across possible thresholds. It is not the percentage of defects caught at a deployed alarm setting.
That distinction is visible in the paper’s own threshold analysis. At its F1-optimized operating point, the reported errors include 19 normal images flagged as anomalous and 23 anomalous images missed. A high aggregate score can coexist with failures that matter on a production line.
The authors also report approximately 0.17 seconds per image for a 1% memory, compared with 0.6 seconds for the full memory in their timing setup. That is evidence of the memory-versus-computation tradeoff, not a guaranteed inspection speed on a factory camera system. Higher-resolution and ensemble variants have different costs and should not be mixed into the same configuration’s performance claim.
The supplementary examples are especially valuable. They show defects that are cropped away during preprocessing, subtle anomalies that produce insufficient image-level scores, and fine detail that is difficult to distinguish at the selected resolution. Other failures involve normal visual variation that looks unusual to the model.
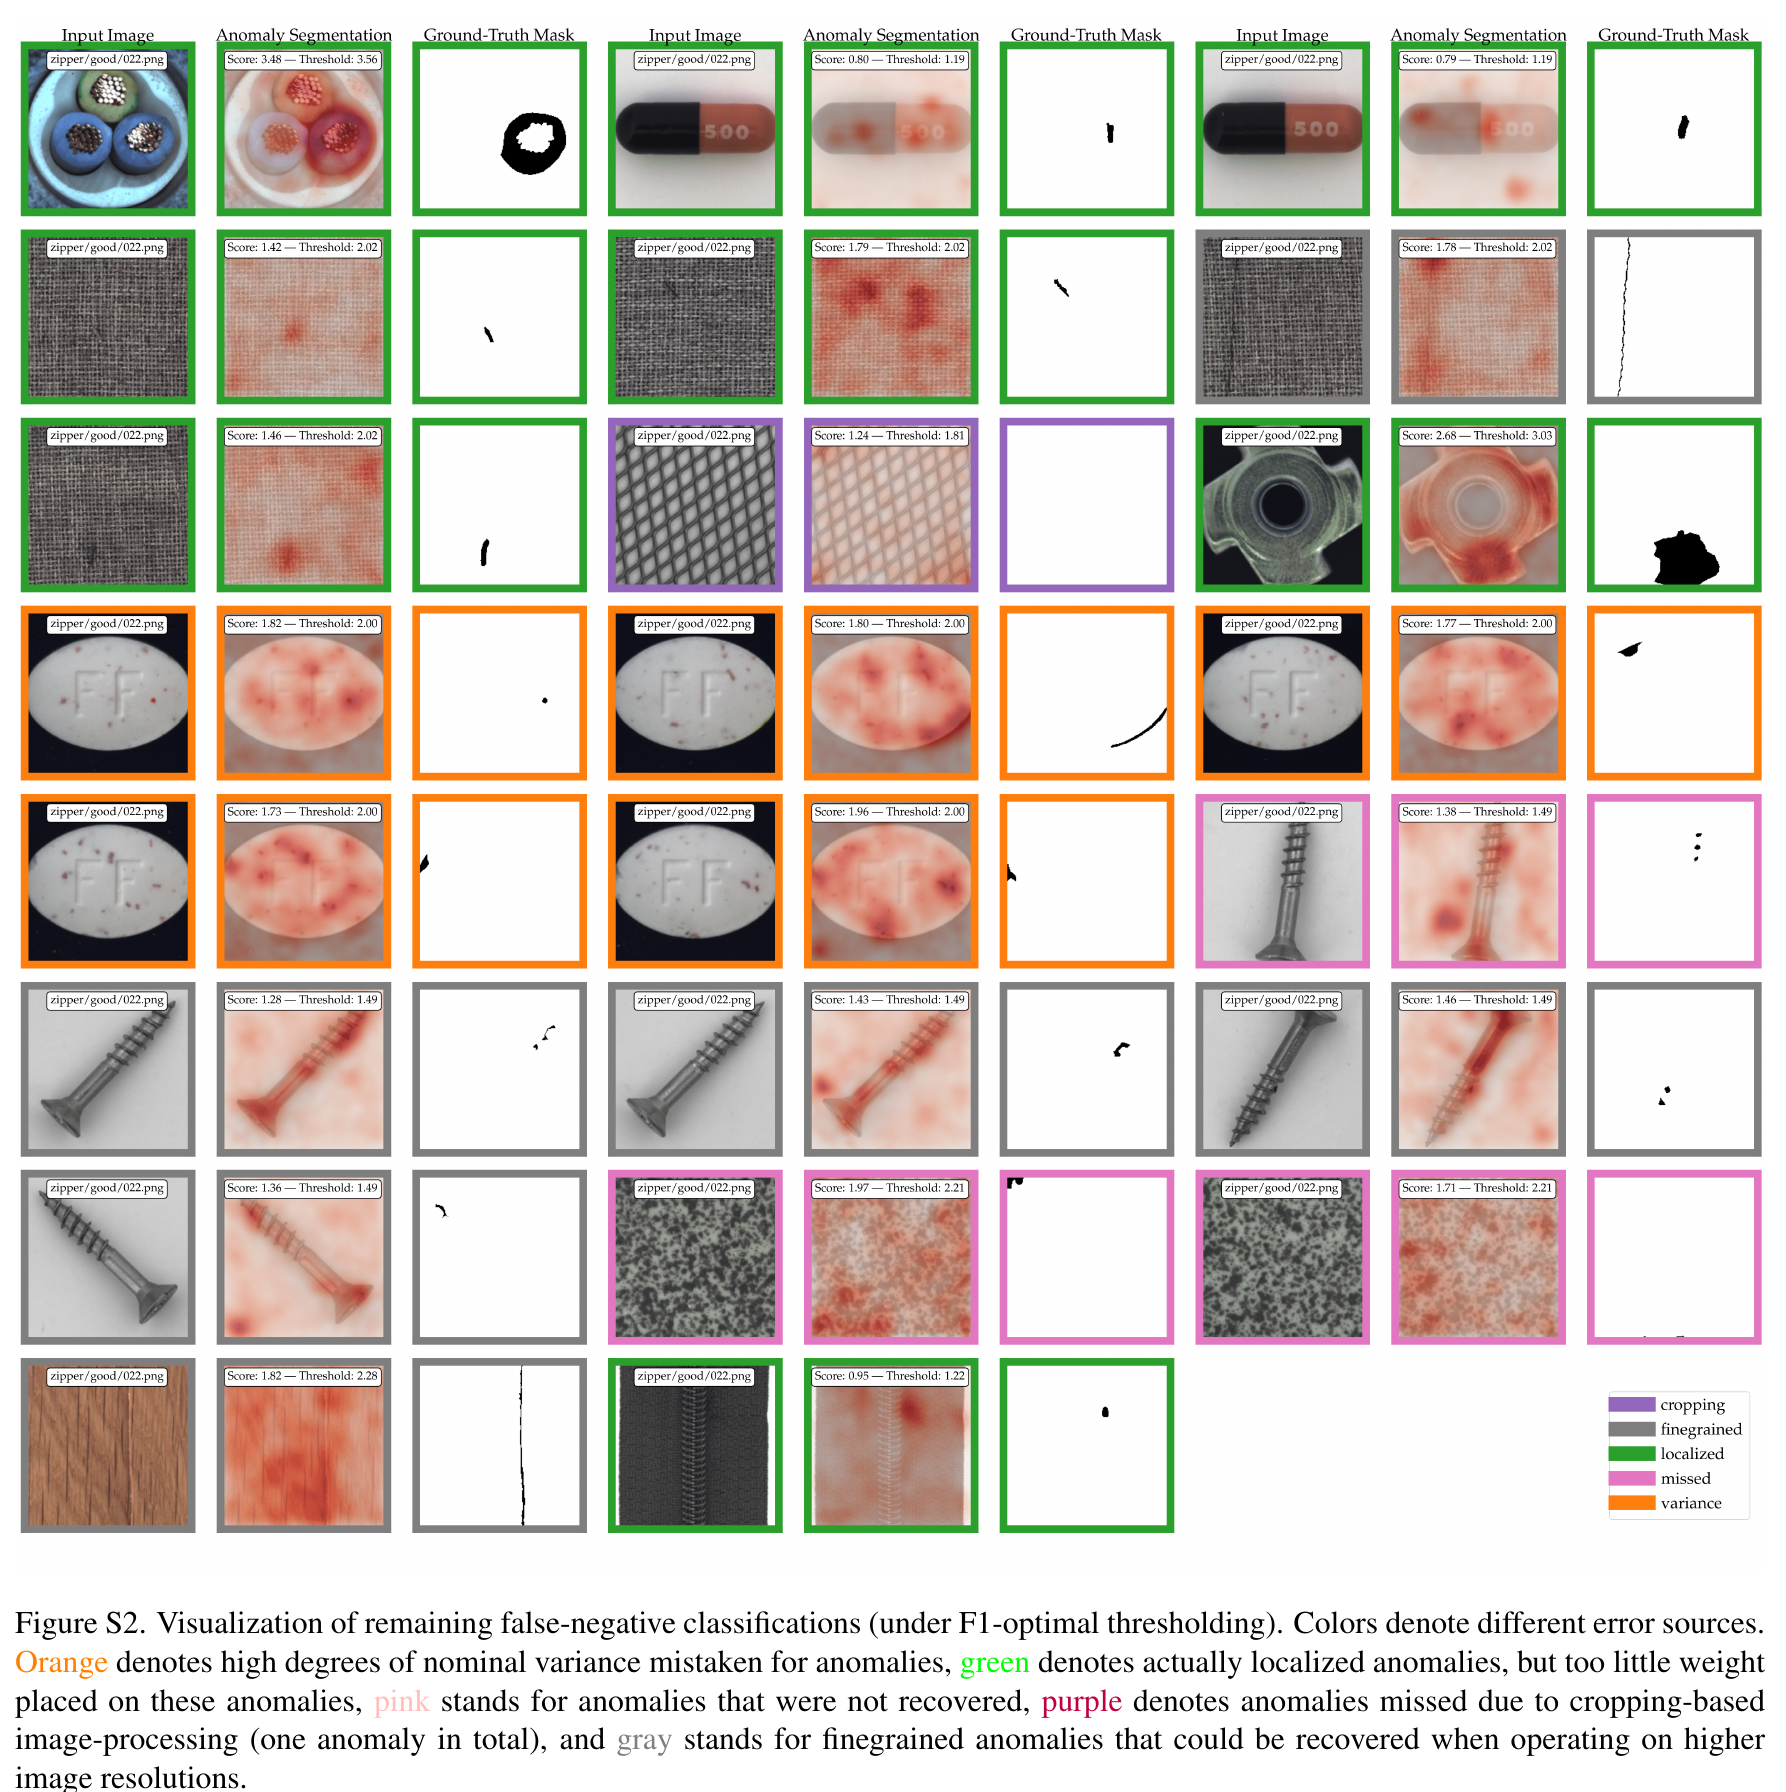
These examples change how a team should evaluate the system. If preprocessing removes the relevant edge of the product, adjusting the alarm threshold will not recover that missing evidence. If a heatmap highlights a defect but the image is accepted, the image-level scoring and threshold deserve inspection. Different failures require different fixes.
The benchmark also cannot establish that the memory remains valid after a supplier changes a finish or a camera drifts. Such changes alter what “normal” looks like. A production evaluation needs to distinguish real defects from changes in image acquisition and legitimate process variation.
A useful first deployment candidate is a repeatable visual inspection task with stable image capture, abundant normal examples and a clear path for human review. Keep the existing inspection process as the baseline while the model runs in shadow mode.
Split the data by production batch or time where possible, rather than scattering near-identical images across training and testing. Include known defect types, subtle faults and legitimate variations. Choose the threshold using a validation set, then measure missed defects and false alarms on untouched images at that fixed setting.
The acceptance decision should reflect operating costs. A low false-alarm rate is not attractive if consequential defects pass through. Catching more defects may also be unusable if the inspection team is overwhelmed with normal products. Record both outcomes, along with localization usefulness, latency and the handling of uncertain cases.
The same principle applies to AI guardrails: an aggregate classification score does not replace an evaluation of the errors the operation can tolerate.
The official PatchCore implementation provides the research workflow using PyTorch feature extraction and nearest-neighbor search, including memory construction and evaluation. It is the most direct starting point when the goal is to understand or reproduce this method.
Begin with one product family and a verified normal-image set. Inspect the preprocessing output before training the memory, then review anomaly maps alongside the final decisions. Keep the camera configuration, backbone, memory selection and threshold in the experiment record. A change to any of them creates a new configuration to evaluate.
Advance beyond shadow mode only when the fixed-threshold results improve the existing process on held-out production conditions and a human fallback is defined. Model code and benchmark results do not supply the factory’s release policy. No factory trial or model execution was performed for this article.
PatchCore’s appeal is that it makes strong use of normal data and retains a visible connection between the suspected defect and the image region that triggered concern. The representative memory is a substantive engineering idea, not merely a larger classifier.
The paper’s error examples are as useful as its leading scores. A team that studies them will ask better questions about image capture, legitimate variation and threshold selection. Those questions determine whether a promising anomaly detector becomes a useful inspection tool.
Karsten Roth, Latha Pemula, Joaquin Zepeda, Bernhard Schölkopf, Thomas Brox and Peter Gehler, Towards Total Recall in Industrial Anomaly Detection, arXiv version 2, May 5, 2022; CVPR 2022.
Turn assembly requirements into questions that reveal logically incorrect products.
Explore how inspection teams can identify predictions that need a second look.





