What 177 papers reveal about GPT in games: content tools, gameplay, player research and the limits of live control. Includes practical implementation guidance.
Select a figure to open it at full size.
Game teams face several different opportunities under the same “generative AI” label: drafting dialogue, building levels, controlling characters, analyzing player feedback and creating new interactions. They have different failure costs and need different tests.
GPT for Games: An Updated Scoping Review (2020–2024) organizes 177 papers into five overlapping use cases. It is a map of research activity, rather than evidence that one model or integration will improve retention or production economics.
The practical value is in separating applications that can be reviewed before release from those that must behave reliably while a player is interacting with the game.
Yang, Kleinman and Harteveld screened 5,988 records and assessed 258 full texts before selecting the 177 papers. The review’s updated search took place in January 2025 and covers research through 2024. It is a historical view of GPT-related game research, not a comparison of today’s model offerings.
The five categories describe what the model does:
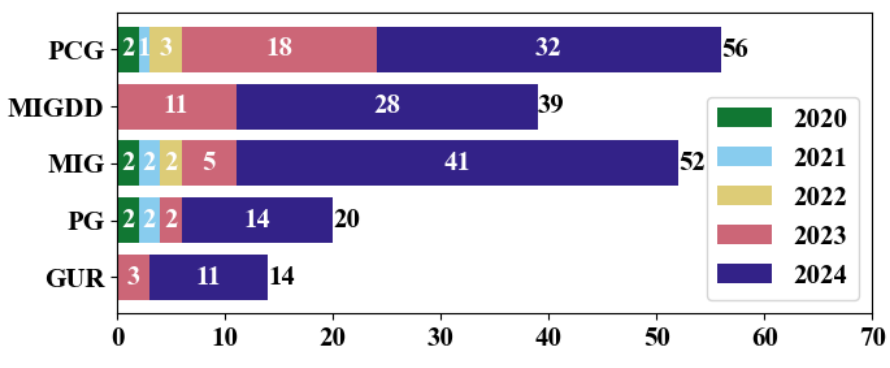
A long bar does not identify the best commercial use case. It means the review found more papers in that category. Studies vary in tasks, models and evaluation, so their results cannot be combined into a single claim that “GPT improves games.”
The review becomes more useful when we inspect how particular systems divide responsibilities.
One reviewed Angry Birds system gives GPT the game rules and a description of the scene, including object size, material and coordinates. GPT selects a target. A separate calculator determines the slingshot angle needed to launch the bird toward it.
That sequence matters. Language-based interpretation and target choice are one task; applying the trajectory calculation is another. The model does not have to invent the physics every time it acts.
The review reports that this system works better in simple situations and needs improvement for more complicated firing strategies. The architecture demonstrates a bounded role for a language model, while the remaining difficulty concerns choosing good actions over a more complex situation. See the game-playing discussion.
A related boundary appears in the reviewed Doom experiment. GPT-4 receives screenshots and generates textual control commands. It can perform basic actions such as opening doors, navigating and fighting. But it struggles with spatial awareness, long-term reasoning and tracking enemies it can no longer see. Planning-oriented prompts help, yet the review reports performance substantially below reinforcement-learning approaches in that study.
These are findings from the studies summarized by the review, not new experiments conducted by its authors. Together, they suggest a practical design question: which parts of the loop benefit from language understanding, and which need explicit state, calculation or a specialized controller?
For an offline content tool, a designer can inspect a proposed quest or level before it reaches players. The useful output may be a draft that reduces editing work. Errors can be caught during the existing production process.
For a live character, an error becomes part of the player’s experience immediately. The model must remain consistent with current world state, avoid inventing unavailable actions and respond within the interaction’s timing budget. A fluent sentence is not sufficient if it grants an item the game never created or forgets an event that just happened.
The review includes systems that ground generation in structured information, such as knowledge graphs representing locations, characters and objects. That is a meaningful pattern: supply a constrained representation of the world, then use generation to express or extend it. It does not eliminate validation, but it makes the boundary between known state and generated content clearer.
A third use case—player research—needs a different check again. The review describes GPT-assisted analysis of game reviews and gameplay transcripts. A summary may be useful while still missing a minority concern or misclassifying a player’s intention. Compare extracted themes with human-coded examples and keep the underlying evidence available to the team.
It does not demonstrate a general increase in revenue, engagement or studio productivity. It also does not establish that results from small, constrained games transfer to a persistent multiplayer world.
The authors explicitly call for more demanding environments and richer evaluations. Dynamic games require responses to changing state, unseen opponents and interactions over time. A system that produces convincing individual turns may still fail when those turns accumulate.
For a studio, the implication is to test complete player-visible sequences. Judge a character across a conversation and its resulting state changes; judge a level after it is played; judge a design assistant after the creator has finished correcting its output. Measuring generated volume alone misses the work transferred to validation and repair.
An offline experiment can begin with your existing content pipeline. Export a small, approved set of world facts and content constraints, generate candidates, then review them through the same checks used for human-authored content. Track accepted output and editing time against the current process.
For a Godot runtime prototype, the engine’s HTTPRequest interface can connect to a backend service. Keep model credentials and output validation on that backend. The engine should retain authority over game state; generated text or proposed actions should be checked before they become game events.
Start with one reversible interaction, such as describing an already-known object. Add a timeout and a scripted fallback. Record invalid references, contradictory dialogue and latency as well as player preference. A small prototype passes only if the full interaction works, including failure behavior.
For the wider distinction between generated plans and reliable action, see our analysis of autonomous-agent architecture.
The strongest opportunity is a specific bottleneck with a clear reviewer or validator. Content drafting, a constrained interaction and player-feedback analysis can each be sensible experiments, but they should not share one vague “AI quality” score.
This review helps teams choose what to test. It does not replace testing. Give the model a role whose output can be inspected, keep game rules explicit, and expand only when the complete experience improves.
GPT for Games: An Updated Scoping Review (2020–2024), Daijin Yang, Erica Kleinman and Casper Harteveld. Version 2, March 14, 2025. The article uses this review and its original Figure 3; descriptions of individual game experiments are attributed to the review.
See how richer descriptions connect language instructions to the details of movement.
Explore why remembering a preference is different from applying it appropriately.





