An ONNX-based research workflow checks model architecture after training and partitioning. Learn what its validators establish—and what they do not.
Select a figure to open it at full size.
A model can pass an accuracy test and still arrive on a device in a form that has not been adequately checked. Training updates its weights. Export changes its representation. Deployment may split computation across different processors. Each step creates a question beyond whether the model usually predicts the right label: is the deployed system still the system we intended to build?
In Workflow for Safe-AI, Suzana Veljanovska and Hans Dermot Doran propose a way to make those transformations more traceable. Their example concerns an industrial shape-recognition system, where some computation needs stronger reliability guarantees than the rest.
For embedded AI teams, the useful contribution is a concrete validation workflow. It is not evidence that an ONNX file, a successful accuracy test or this workflow alone makes a product safe.
The authors start with a practical constraint: qualifying every feature of a large machine-learning toolchain can require substantial effort. Their proposal is to keep the trusted workflow small and inspect what the more complex tools produce.
They use ONNX, a format for describing a model as connected operations, as a common representation from model creation through deployment. The workflow preserves a reference architecture before training. After training, a validator compares the result with that reference. Later, a second validator checks what happened when the trained model was partitioned for different execution environments.
This separates two questions that are easy to conflate. The training process is supposed to change learnable parameters. It is not supposed to silently change an architectural feature that the team relies on. Checking that distinction creates an explicit place to catch unintended transformations.
The original workflow diagram shows two validation gates, rather than a single check immediately before deployment.
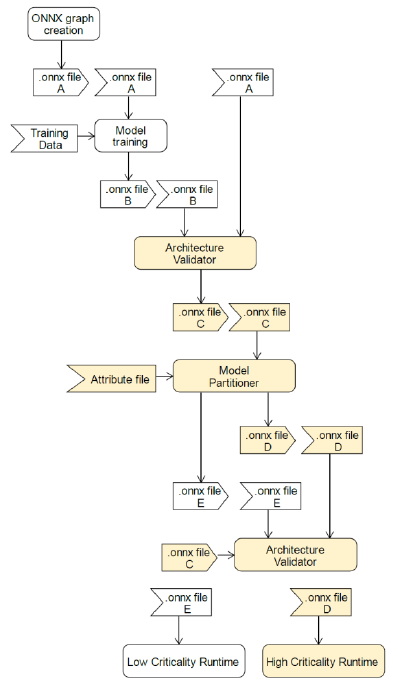
The paper labels the initial model A. Training produces B, which should retain A’s architecture while containing updated trainable weights.
The first validator extracts a readable account of the model: its layers, connections, input/output mappings and non-trainable hyperparameters. It performs the same analysis on B and compares the two. Unexpected differences produce an error report. A successful check produces the validated representation C, with metadata recording that validation.
C then enters a partitioner alongside instructions describing how the work should be divided. The partitioner produces D and E for execution on platforms with different reliability requirements. This is where the second validator becomes important. A correct original model does not establish that the split preserved its connections or that each piece was assigned correctly.
The second validator reconstructs the complete architecture from the partitions and their allocation metadata. It checks the result against C, while identifying the reliability features deliberately added during partitioning. Unauthorized changes must be distinguished from intended additions. The output is either a discrepancy report or validated partitions.
The engineering value is the chain of evidence: reference, transformation, comparison and recorded outcome. If the deployed model changes later, the team has a defined comparison to repeat, rather than relying on a familiar filename or a past test result. Sections III–IV describe the two validators.
The motivation comes from the authors’ earlier work on detecting anomalous shapes using AlexNet, an image-classification network. A classifier’s prediction is paired with a more constrained shape-validation path.
That path starts with edges. A Sobel filter extracts image-edge information; the shape’s outline is then represented using distances from its center to its boundary. Symbolic Aggregate Approximation, or SAX, turns the resulting sequence into a compact string that can be compared with other shape descriptions.
Instead of computing all edge processing separately, the authors describe replacing the first of the network’s 96 first-layer channels with Sobel kernels. That channel supplies information for the reliable validation path. They also describe redundant arithmetic for that convolution: repeat the relevant operations and compare their outputs.
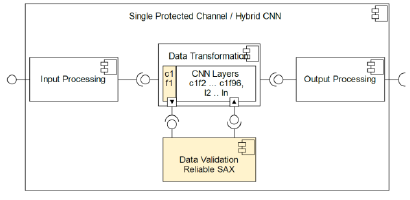
The important idea is narrower than “make the entire neural network deterministic.” A specific path supplies evidence to a specific checker. The main classifier still does the broader recognition work. This is most plausible when a safety-relevant property can be expressed and checked independently; it does not automatically transfer to open-ended language generation.
This short paper presents the architecture and development process. It describes Python validators and links the workflow to the V-model, where requirements and design decisions have corresponding verification activities.
It does not report a new comparative deployment study, quantified failure probability or completed product certification. Its statements about unchanged classifier accuracy refer to earlier work. Those statements should not be read as measurements demonstrating the reliability of every component in the proposed workflow.
Architecture consistency also has a precise limit. Two models can have the same layers and connections while different weights produce different predictions. A structurally valid graph can still contain a poor classifier. Likewise, a deterministic shape checker can reliably compute a result that is unsuitable for the environment if its assumptions are wrong.
A team therefore needs separate evidence for model behavior, the checker’s coverage, runtime behavior and the system’s response when checks fail. The workflow makes some of that evidence easier to organize; it does not collapse those questions into one pass/fail badge.
ONNX can provide the inspection surface. Its model checker checks consistency of an ONNX model. Use it to catch representation problems, then add application-specific comparisons for the architecture and attributes that must remain unchanged. The built-in checker is not the paper’s complete validation workflow and does not confer safety qualification.
A useful first implementation is a model-change report in the existing build pipeline. Preserve the reference graph, record allowed weight changes, compare topology and non-trainable attributes after training, and retain the reports with the resulting artifact. Before adding partitioning, deliberately alter a connection or protected attribute in a test fixture and verify that the comparison rejects it.
For a partitioned prototype, add a reconstruction test: can the deployment pieces be traced back to the approved architecture, with intended reliability additions explicitly accounted for? Pair that with behavior tests on the target runtime. A graph comparison should not be asked to detect numerical or timing differences it was not designed to measure.
The paper’s V-model discussion also gives a useful organizational rule: define what a validator must detect before building it. A test that only proves it accepts one good model says little about whether it catches the transformations that matter.
The strongest lesson is to make the path from training to deployment inspectable. Teams already evaluate model outputs; fewer treat each deployment transformation as a claim that needs its own evidence.
Start with a constrained application and a small set of explicit invariants. If those invariants cannot be stated, or if no useful independent check exists for the output, this particular architecture offers less than its “safe AI” label might suggest. For broader agent risks, the large-model safety survey addresses a different set of failure modes.
Workflow for Safe-AI, Suzana Veljanovska and Hans Dermot Doran, ZHAW School of Engineering. This article uses arXiv version 2, submitted 20 March 2025.
See why generated motion-control code needs behavioral checks beyond valid syntax.
Explore whether a building controller can reuse earlier learning when its available controls change.





