A study of 628 participants tests whether contrastive AI explanations improve independent decisions. Explore the design, original charts and limits.
Figures open at full size. Wide tables scroll sideways.
An AI assistant can help someone pick an answer without teaching them how to make the next decision. For product teams building decision-support tools, those are different outcomes. A useful recommendation today does not establish that the user will be more capable tomorrow.
Research by Zana Buçinca and colleagues tests a specific way to close that gap: explain why the AI’s recommendation is preferable to an alternative the person might reasonably consider. In an online experiment, this design improved participants’ subsequent decisions without AI compared with an explanation that only justified the recommendation.
The finding is encouraging, but it has an important boundary. The explanations helped short-term learning; they did not reliably protect people from following bad AI advice. A product that aims to develop users’ skills needs to measure both.
Suppose someone sees a recommendation and thinks another option also looks sensible. Listing the reasons for the recommended option may leave the real question unanswered: what makes it better than the alternative?
The researchers call an explanation that addresses this comparison contrastive. Their distinctive contribution is how they select the alternative: use a model of previous human choices to predict an option people are likely to consider. This gives the explanation a chance to address a plausible misunderstanding, rather than compare against an arbitrary or obviously poor choice.
The study does not treat this predicted choice as a personalized reading of someone’s mind. It uses a generic model trained from other people’s decisions. That is a useful distinction for product design: anticipating a common source of confusion is more modest than claiming to know why a particular user disagrees.
Participants chose an exercise for a fictional person from seven options. The fictional profile described goals, capabilities and preferences. The study’s reference model, developed with a kinesiology expert, determined which choice counted as correct for the experiment.
In the authors’ interface example, Natalie wants to build muscle and improve flexibility. The AI recommends pilates, while the predicted human alternative is resistance training. The explanation acknowledges the muscle-building benefit of the alternative, then points to flexibility as the reason the recommended option better fits the study’s scoring of this profile.
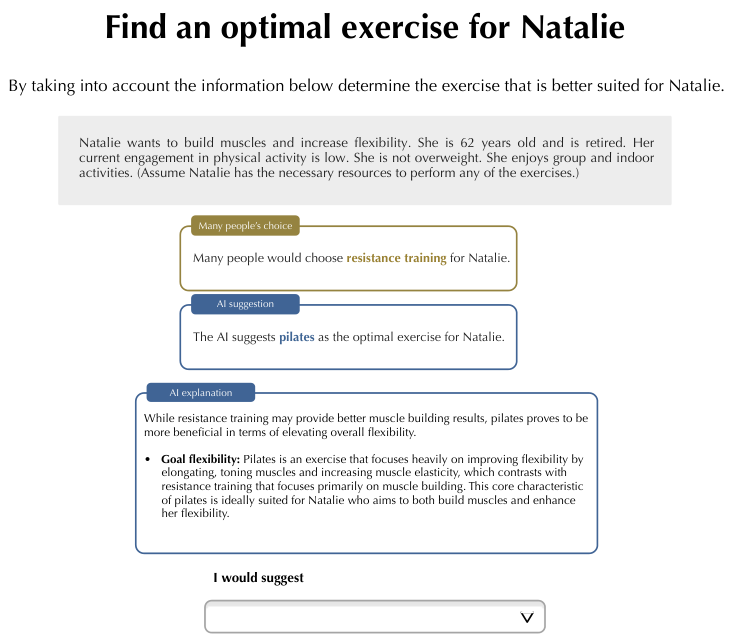
The useful design feature is the connection between an option’s characteristic and the person’s goal. A label such as “flexibility” alone would not teach that relationship. A comparison that acknowledges the other option’s benefit also avoids pretending that the rejected choice has nothing going for it.
The system separates choosing an answer from writing the explanation. It has four parts:
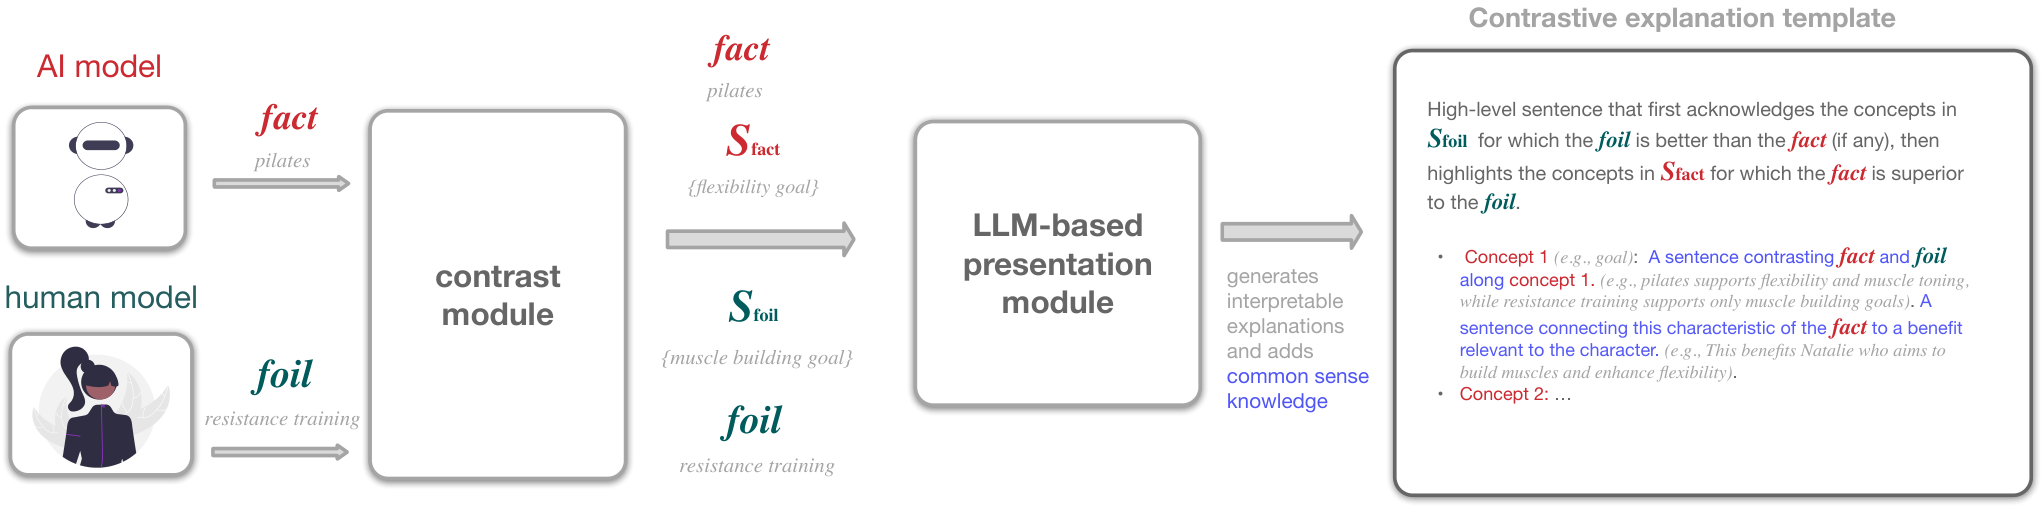
The appendix’s explanation prompt makes the mechanism concrete. It instructs the presentation stage to acknowledge any advantages of the alternative, focus on the supplied differentiating concepts, and connect each characteristic to a benefit relevant to the profile. The research therefore offers more than the advice to “ask an LLM for a better explanation”: it constructs the comparison before asking for prose.
That structure did not eliminate the need for review. The first author inspected the generated explanations, and the paper reports occasional confusion about indoor versus outdoor preferences. A constrained explanation generator still needs checks on what it says.
The experiment recruited 800 US adults through Prolific and retained 628 participants after its exclusion criteria. Each person completed five decisions without AI, fourteen intervention tasks, then five further decisions without AI. The final unaided block is crucial: it tests whether people learned something they could use after the assistance was removed.
Participants were assigned to one of five designs: no AI; an explanation supporting only the AI’s choice; a comparison with a predicted human alternative; a comparison with a random alternative; or a comparison shown after the participant first entered their own choice.
The AI advice was deliberately simulated to be correct on ten of the fourteen intervention tasks. This allowed the researchers to study responses to bad advice as well as good advice. It is not a measurement of the accuracy of GPT-4 or any current assistant.
After accounting for pre-test performance, the reported unaided post-test accuracy was 47% with a predicted-alternative comparison, compared with 39% for the one-sided explanation and 32% without AI. The predicted-alternative versus one-sided comparison was statistically significant: an eight-percentage-point difference in this short experiment.
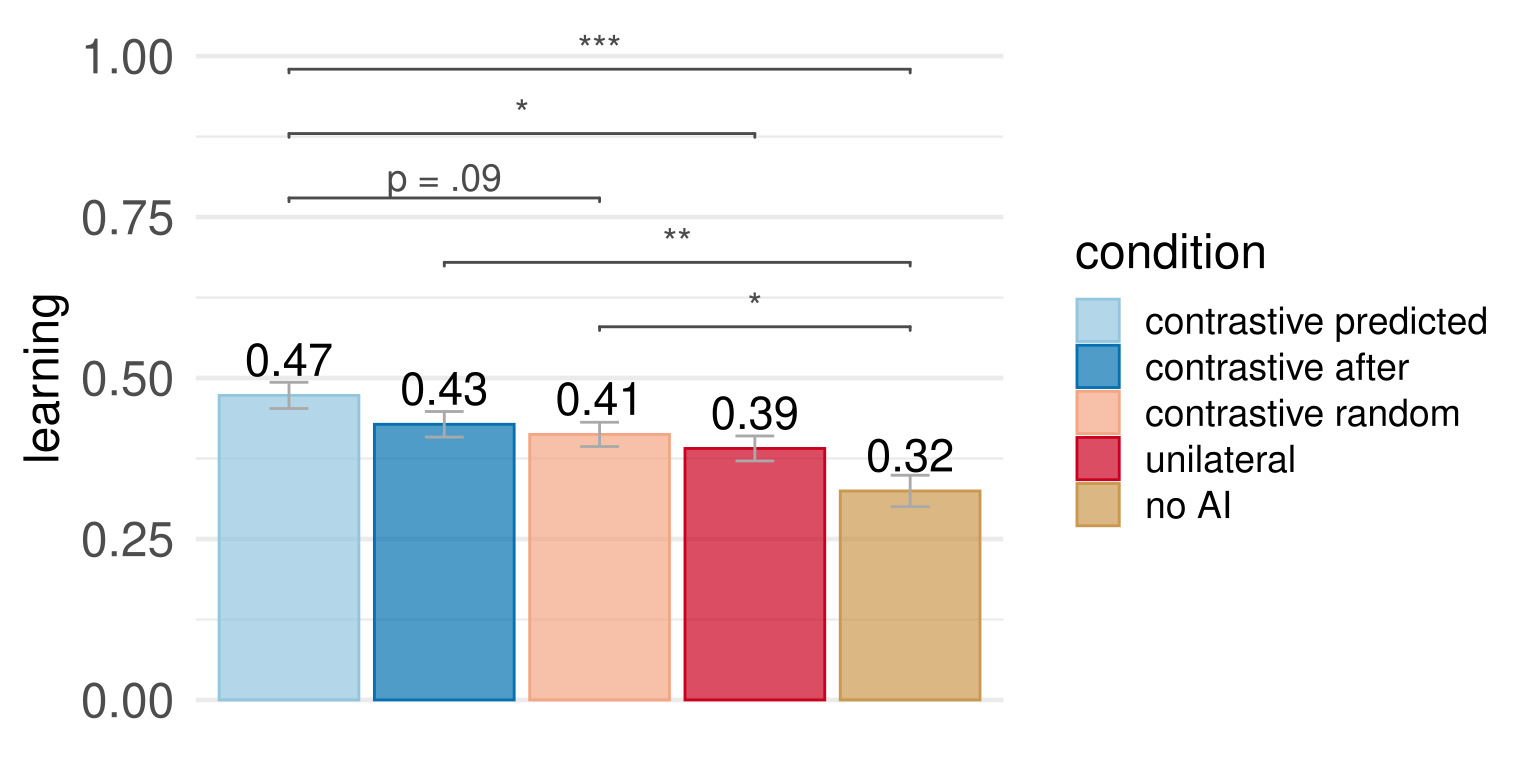
The other comparisons prevent a broader claim. Asking people to decide first and then explaining the contrast produced a reported 43% post-test score, but its difference from the one-sided design was not statistically significant. The predicted-alternative design also did not conclusively outperform a random alternative: that comparison’s reported p-value was 0.09. The evidence supports the main comparison with one-sided explanations; it does not settle every choice of alternative or timing.
During the intervention, when advice was available, reported accuracy was 56% for predicted comparisons and 58% for one-sided explanations. That difference was not statistically significant. The study did not establish that the comparison improved immediate task accuracy, or prove that the designs are equivalent in every setting.

That distinction changes what a product team should measure. If the goal includes developing human capability, acceptance rates and assisted task scores leave part of the job unmeasured. You need to see what users can do without the recommendation.
When the simulated AI gave an incorrect recommendation, participants in the predicted-comparison condition followed it about 58% of the time—similar to the one-sided explanation condition. This percentage concerns the incorrect-advice tasks, not every decision in the experiment.
The way errors were constructed matters. The researchers made the incorrect AI suggestion a plausible human choice rather than an obviously absurd option. The comparator could also be wrong. Showing two options therefore did not ensure that the correct answer was among them.
The appendix adds another practical concern: making an alternative visible can steer attention toward it. The authors found that participants who rejected the AI’s suggestion were more likely to select the displayed alternative in the comparison designs. The original chart separates cases where the AI was correct and incorrect.
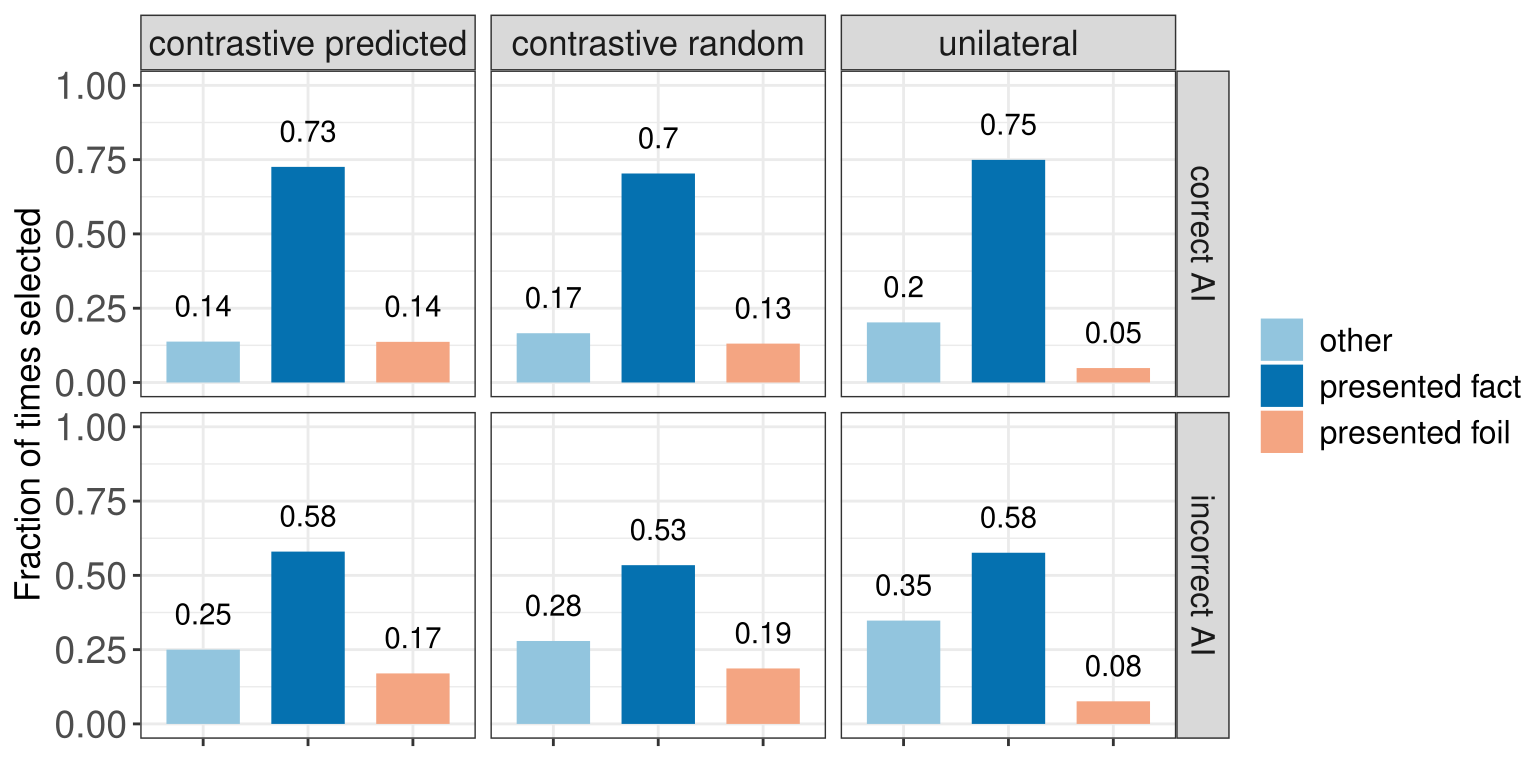
For a product designer, the implication is concrete: a comparison helps frame a decision, but can also narrow the options users consider. Keep a route to other answers and disagreement. Evaluate explanations on incorrect recommendations as well as correct ones; a clear rationale for bad advice can remain persuasive.
This approach is most relevant where users repeatedly choose among plausible alternatives and can learn a transferable distinction. A software-support tool might compare two remediation options using their prerequisites. An analyst assistant might explain why one data interpretation fits the evidence better than another. These are possible applications of the design, not deployments tested by this study.
Start with a decision where your team can define an acceptable answer and explain its tradeoffs. Collect the alternatives users actually consider. If the comparison addresses something nobody was wondering about, it may add reading without teaching much.
The experiment establishes short-term learning in one task with crowdworkers. It does not demonstrate durable professional skill development, clinical effectiveness or prevention of workforce deskilling. The authors also found that learning benefits varied with participants’ tendency to consider alternative viewpoints. Test with the people who will use your product rather than assume an average result applies equally to everyone.
The timing result is useful too. Participants who had to answer before receiving the explanation reported lower feelings of competence, autonomy and connection to the AI than those shown a predicted comparison. That does not make the answer-first design universally wrong. It means the extra interaction has a user-experience cost worth measuring alongside learning.
Begin with a structured comparison, using existing application logic. Store the recommended option, a plausible alternative, the criteria favoring each, and evidence for those criteria. Render that information with a simple template before adding an LLM. This helps the team check whether the comparison itself is useful, without confusing the quality of the decision evidence with the fluency of generated prose.
Use choice data when predicting alternatives is worthwhile. The researchers trained a linear support-vector model from 100 choices collected from twenty people, converting them into pairwise exercise comparisons. For a prototype with suitable labeled comparisons, scikit-learn’s support-vector classifiers offer an implementation option. This is a component for predicting a choice, not a ready-made explanation system. The study’s small, shared human model should not be mistaken for a validated model of each individual user.
If your application already records a user’s proposed answer, you can compare against that instead. Where a standard practice supplies the obvious alternative, you may not need another learned model. These choices have different interaction costs; the study’s timing comparison gives a reason to test them rather than require users to enter a choice by default.
Add language generation only where it earns its place. Supply the selected options and supported differences to the presentation layer. Check that it preserves the alternative’s genuine advantages and does not invent a reason for preferring the recommendation. Keep the evidence and generated wording separately available for inspection. A fluent sentence cannot establish the underlying recommendation’s correctness.
A useful product evaluation follows the research’s separation of outcomes:
Define the success condition before the trial. An increase in confidence or recommendation acceptance is not a substitute for better decisions. If users learn more but become more likely to accept bad advice, the design needs additional work.
The strongest idea here is that an explanation should address the decision the person is trying to make, including the alternative they might reasonably favor. The research shows that this can teach more than a justification written solely around the AI’s answer.
We would test this design in recurring decision tasks with clear evaluation criteria. We would measure independent performance and responses to bad advice separately, and favor the simplest comparison mechanism that produces useful evidence. Sustained learning across real users and longer periods would justify a stronger claim. For now, this is a promising way to design for human capability, with a specific experiment behind it—not a cure for overreliance.
Zana Buçinca, Siddharth Swaroop, Amanda E. Paluch, Finale Doshi-Velez and Krzysztof Z. Gajos, Contrastive Explanations That Anticipate Human Misconceptions Can Improve Human Decision-Making Skills. This article uses arXiv version 2, dated 19 March 2025, associated with CHI 2025. Original figures are attributed to the researchers; SVG charts are rendered without changing their plotted content.
Match an explanation method to the decision or challenge a reviewer needs to make.
See how connectivity, interface and teaching context shape a practical AI service.





