When should an agent gather another clue? Research compares information seeking with reward optimization, revealing tradeoffs in consistency and cost.
Select a figure to open it at full size.
An agent that always chooses the action with the best expected payoff can still have an uncomfortable pattern of results: a good average, interrupted by expensive runs of poor decisions. When feedback is noisy and the environment changes, learning enough to avoid those runs can be valuable in its own right.
Nicholas Barendregt and colleagues examine this tradeoff in a deliberately small decision problem. They compare an agent that optimizes expected reward with one that optimizes information about the environment. Both use the same evidence and belief-updating machinery. What differs is the objective used to decide when to stop gathering evidence and act.
This is computational research on sequential decision-making, relevant to the design and evaluation of agents. It is not a field study showing that information-seeking companies earn higher returns. Its practical value is a precise way to ask what an agent should optimize when consistency matters alongside average performance.
Imagine an agent choosing between two resource patches. At any given time, one is more likely to reward a visit. The agent can spend an action gathering a noisy clue about which patch is favorable, or commit to a choice and receive feedback. Both observation and commitment consume part of a finite time budget.
The environment can switch which patch is favorable between decisions. Rewards are also unreliable: a good choice can go unrewarded, and a bad choice can occasionally pay off. The agent therefore cannot treat its last outcome as a perfect report of the underlying state.
The original task diagram makes that distinction unusually clear. In the second illustrated decision, the agent receives a reward despite choosing the unfavorable option. In the third, it chooses the favorable option but receives a negative outcome. Learning requires combining evidence and feedback, rather than equating a win with a correct decision.
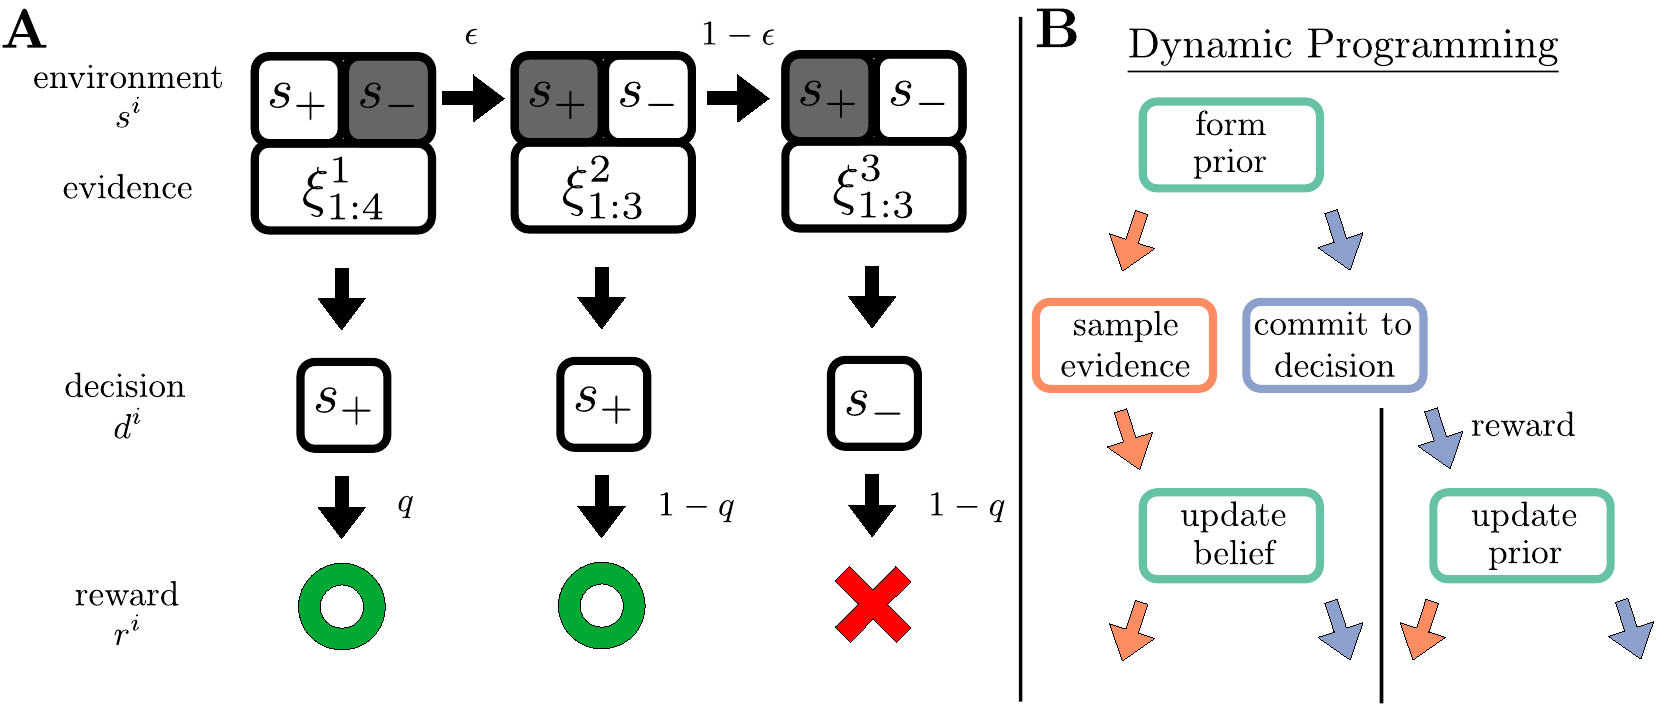
The study assumes the state remains fixed while the agent gathers clues for a particular decision. It can change after commitment. That keeps the experiment interpretable, but it is simpler than a world that changes during deliberation itself.
The reward-maximizing agent asks which available action offers the best expected reward over the remaining horizon. Gathering a clue can be worthwhile because it improves a later decision, even though observing yields no immediate reward.
The information-maximizing agent instead asks which action is expected to reduce uncertainty. Importantly, acting can also provide information: the resulting reward or disappointment is evidence about which patch was favorable. Information seeking does not therefore mean always asking another question or delaying every choice.
Both policies are computed using a planning procedure that considers what can happen next. The authors also vary how strongly each policy discounts future benefits. With full emphasis on the immediate step, the reward-oriented agent has no reason to pay for a clue whose benefit arrives only later. The information-oriented agent can still value that clue because reducing uncertainty is itself its objective.
That contrast explains why the paper should not be read as a comparison between an intelligent learner and a foolish, permanently greedy baseline. Reward maximization with a longer horizon can value learning too. The differences depend on the objective, the horizon and the environment.
When the environment is stable and reward feedback is reliable, both policies can stop taking separate observations and keep acting. The action itself provides useful information, and the knowledge carries into the next decision. Under those conditions, paying for an additional clue can add little.
Across other conditions, the policies produce different mixtures of sampling and committing. Reward maximization generally produces the higher average reward rate. Information maximization often produces a more consistent reward rate across repeated runs. That is a tradeoff between how much is earned on average and how widely outcomes vary, rather than a universal victory for one policy.
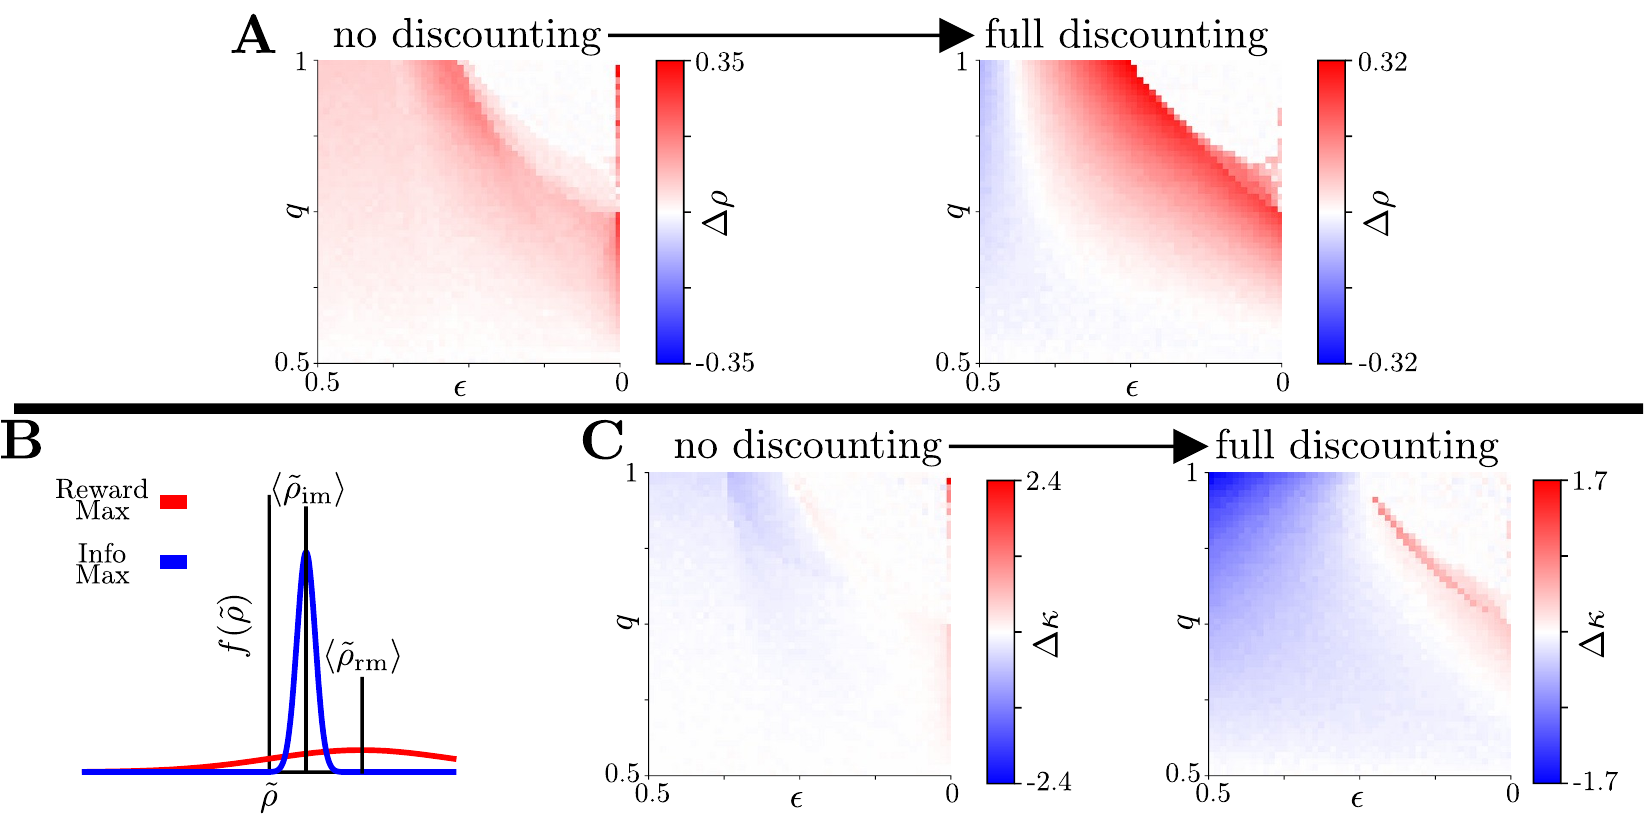
In the top row, red regions favor reward maximization on average reward. In the lower-right comparisons, blue regions favor information maximization on the paper’s robustness measure, which relates average reward to its variability. The horizontal direction moves from a more changeable environment toward a more stable one; the vertical direction increases the reliability of reward feedback.
The narrow blue curve in panel B explains the intuition: a strategy can have a slightly lower center while avoiding as many very poor runs. It is an illustration of the argument, not an empirical histogram to read numerical probabilities from.
Discounting makes the difference more pronounced. When the reward-oriented policy becomes short-sighted, information seeking can even achieve higher average rewards in some volatile or unreliable settings. The mechanism is that it continues to gather useful evidence where an immediate-payoff policy keeps committing without investing in later choices. The results and discussion connect those outcomes to the policies’ objectives.
The model has two mutually exclusive alternatives. Evidence against one automatically favors the other. In a product with many actions, evidence against one candidate does not identify the best replacement. The paper discusses that extension as future work, rather than demonstrating it.
The information objective also does not directly price the consequences of a mistake. Changing reward and punishment magnitudes changes what the reward-oriented policy values, while the information objective continues to value reducing uncertainty. An agent can become better informed about something that is not the most important business risk.
Finally, the robustness measure is not a direct promise that a chosen loss threshold will never be crossed. If the organization cares about outages, irreversible actions or a worst-case budget, those outcomes should be evaluated explicitly. A favorable average-to-variability ratio is not a substitute for the actual requirement.
The supplementary experiments vary observation costs, evidence quality and reward structure. Their role is to show that the exploration boundary depends on those conditions. They do not yield a universal rule such as spending a fixed percentage of every agent’s budget on research.
The authors’ SequentialRewardInfo repository contains the task and strategy implementations, simulation scripts, and figure data. It is the most direct starting point for understanding or reproducing the comparison. Its abstractions support extending the task and decision strategies; it is not a ready-made controller for an enterprise workflow.
A first application experiment should retain the paper’s separation between belief formation and action selection. Feed competing policies the same observations and compare their choices. If both the information source and the objective change at once, any benefit becomes difficult to interpret.
For example, an agent choosing whether to request another diagnostic log before attempting a reversible repair could compare immediate action, a fixed evidence-gathering rule and a policy that values additional information. This is a proposed software experiment, not a use case tested in the paper. Account for the time and cost of acquiring the log, whether it actually distinguishes the possible faults, and whether the system changes before the agent acts.
Evaluate repeated scenarios, not one successful demonstration. Measure average completion cost, variability, poor-outcome frequency and recovery after a change in conditions. Include stable cases where more information is unnecessary. A useful information-seeking policy should justify the delay it introduces as well as the mistakes it avoids. Our coverage of multi-agent systems addresses a related question: whether additional reasoning work improves the final outcome enough to justify its cost.
The research makes a useful challenge to agent evaluation: the best average result may conceal a pattern of failures that the product cannot tolerate. Information acquisition deserves its own evaluation, especially when feedback is noisy and conditions change.
But more research is not automatically better decision-making. Start by identifying what the next observation could change, what it costs and which bad outcomes matter. The paper offers a controlled comparison for that work, not a blanket instruction to make every agent more inquisitive.
Information-Seeking Decision Strategies Mitigate Risk in Dynamic, Uncertain Environments, Nicholas W. Barendregt, Joshua I. Gold, Krešimir Josić and Zachary P. Kilpatrick. Version 1, March 24, 2025. Original Figures 1 and 4 reproduced for explanation.
Explore how predicting action consequences differs from producing a plausible plan.
Explore how confidence scores can support escalation or abstention instead of automatic acceptance.





