Read the original IoT botnet detector’s errors, distinguish attack-family mistakes from missed attacks, and design a realistic evaluation.
Figures open at full size. Wide tables scroll sideways.
An intrusion detector can recognize that traffic is malicious while assigning it to the wrong attack family. It can also score well on a balanced research dataset without producing a manageable alert stream in a working network.
A paper by Amna Naeem and colleagues proposes a hybrid neural model for IoT botnet classification. It combines convolutional layers, a bidirectional LSTM and attention, reporting roughly 98.8% test accuracy—rounded to 99% in the paper's headline account.
For an IoT security team, the architecture is worth understanding. The more useful evidence, however, is in the original confusion matrix: it shows what the model confused, which is different from simply counting every classification error as an undetected attack.
The model uses three successive kinds of processing. Convolutional layers learn local patterns in the input representation. A bidirectional LSTM processes a sequence in both directions. Attention weights the resulting representations before dense layers produce a class prediction.
The final output has ten classes: benign traffic and nine selected botnet attack types. This is a supervised classifier trained on labeled examples, rather than a demonstrated detector of every previously unseen attack.
The authors' original architecture diagram makes the sequence visible. Normalization, pooling and dropout sit between the learned layers to support training; the final softmax produces the class scores.
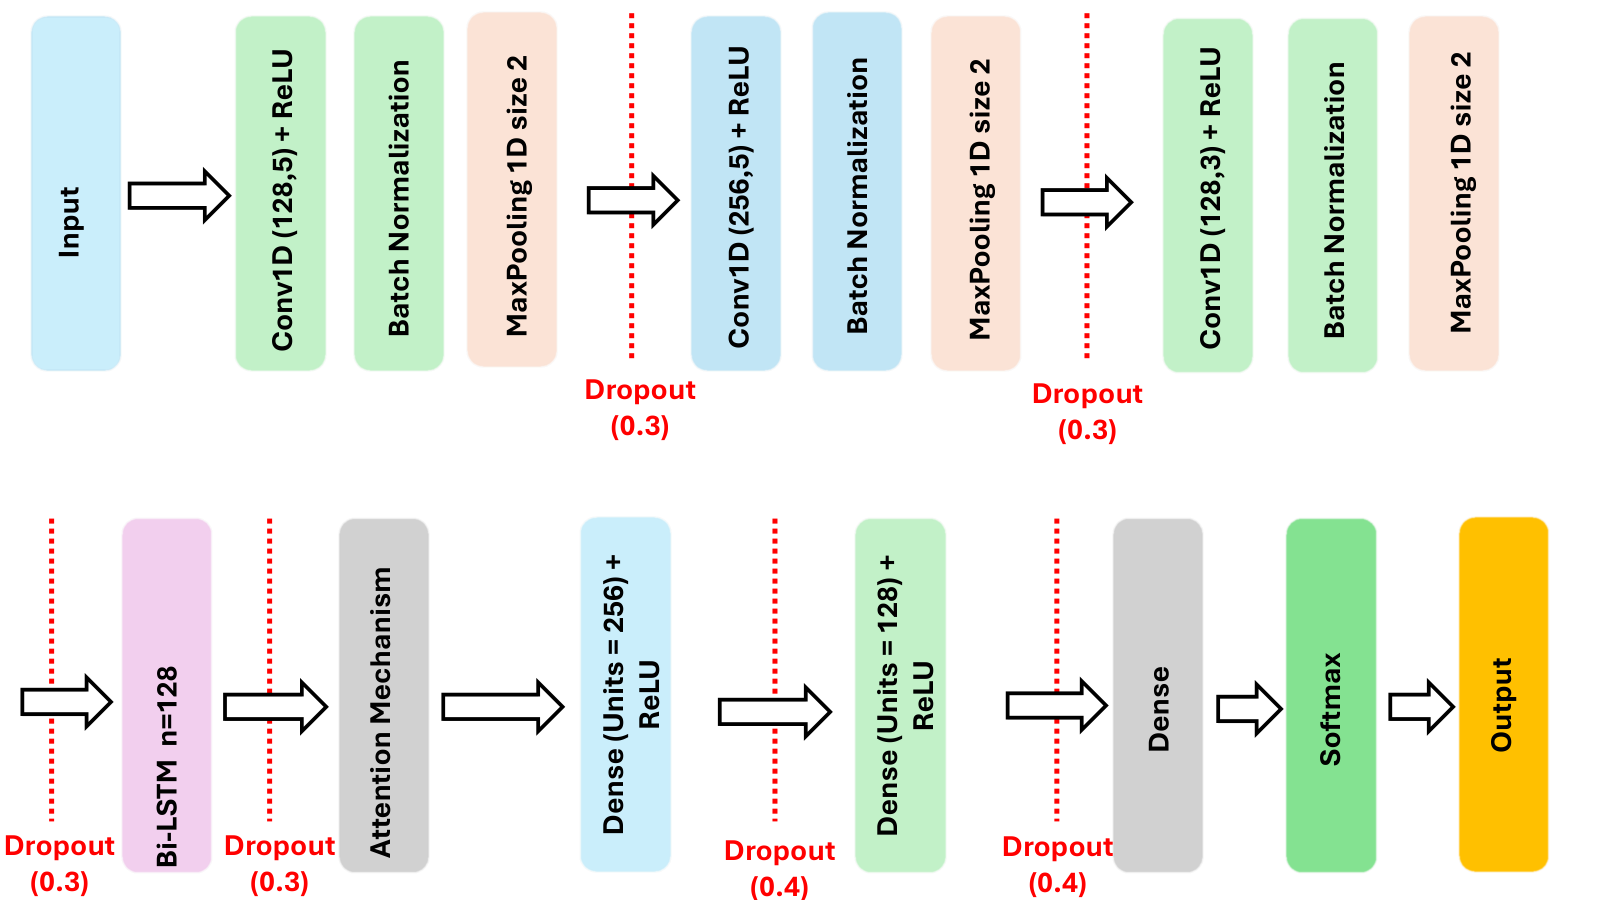
One implementation detail remains important: the paper does not clearly specify how the input is arranged into sequences. Its dataset contains statistical traffic features, so the presence of an LSTM alone does not establish that the model learned a chronological sequence of packets. A reproduction needs the input shape, feature ordering and sequence construction before making that claim.
The study uses N-BaIoT, a dataset of normal and botnet-infected IoT-device traffic. Its records contain 115 statistical features calculated across time windows ranging from 100 milliseconds to one minute. Those inputs already summarize traffic behavior; the classifier is not reading raw packets directly.
The researchers sample 10,000 records for each of ten classes, making a balanced 100,000-record experiment. They allocate 80% to training and 20% to testing. The original dataset contains ten attack types plus benign traffic, but this experiment selects nine attack types. The classification report does not include the Gafgyt TCP class.
The distinction matters for the headline result. The reported accuracy applies to this selected, balanced task. It is not a test of the entire original dataset at its natural class frequencies, every IoT device a team might deploy, or attacks outside the selected labels.
Training used an NVIDIA T4 GPU and took approximately one hour. The authors report about 50 milliseconds per sample for inference. That does not include every possible cost of collecting traffic, building the feature windows and delivering an alert on the intended production hardware.
The confusion matrix places the true class on each row and the model's predicted class on each column. Correct classifications lie on the diagonal. Off-diagonal cells reveal where the mistakes went.
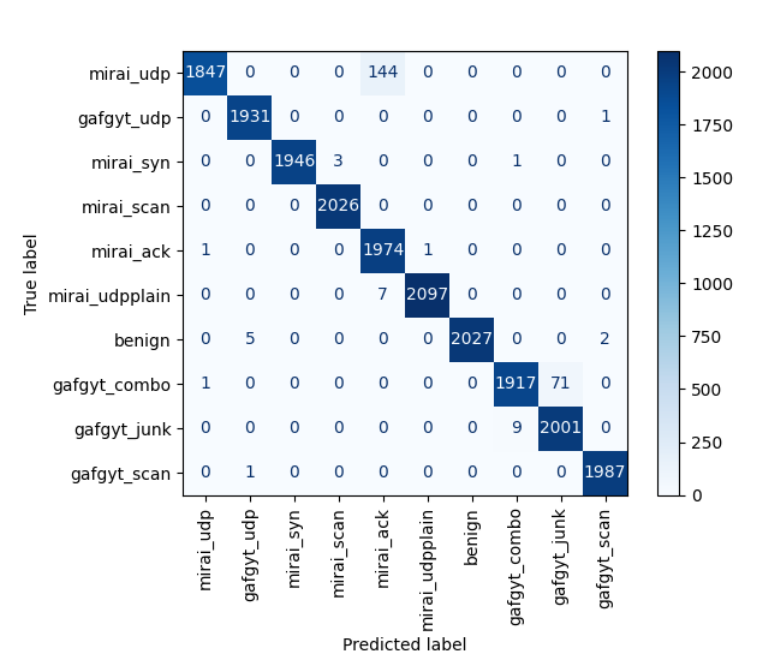
Take Mirai UDP. The row contains 1,991 test examples: 1,847 receive the correct label and 144 are classified as Mirai ACK. That produces about 92.8% recall for the specific Mirai UDP class. It does not mean 7.2% of those attacks passed as benign. In this matrix, those errors went to another attack category.
The distinction changes how a team evaluates usefulness. If the system only needs to raise a generic malicious-traffic alert, this particular confusion may be less damaging. If the label selects a response procedure or shapes an analyst's investigation, getting the family wrong still matters.
The benign row asks the other operational question. Of 2,034 benign examples, 2,027 stay benign and seven are assigned to attack classes. Those are false alerts in this test. They are not an estimate of daily alert volume on another network, where the mix of traffic and device behavior may differ.
The paper's class-report table has some inconsistent accuracy entries, so the matrix is the clearest way to understand these concrete errors. The result is strong classification on this split, with a specific pattern of confusion—not a universal guarantee of protection.
The paper does not clearly demonstrate evaluation on held-out devices or a later time period. Without those separations, a strong score does not tell a team how well the model transfers to new hardware or changing normal behavior.
Its comparison table draws on results from prior architectures rather than a clearly controlled experiment removing one component at a time. Some reported class scores are better, while others are not. The comparison therefore does not establish that attention or bidirectional processing caused every improvement.
There is also a difference between model latency and alert latency. A feature that summarizes a time window must be available before the classifier can use it. A bidirectional model must operate on an already available input sequence, rather than relying on future traffic beyond the scoring time. The deployment design has to make that boundary explicit.
These are testable gaps. They point toward a more realistic evaluation, not a reason to dismiss the architecture without trying it.
A security team should score malicious-versus-benign detection separately from attack-family classification. The original matrix shows why combining them into one number obscures the operational tradeoff.
Begin with a passive comparison against the existing detection process. Preserve device identity and capture time, then hold out devices and later traffic where those are the intended generalization targets. Fit scaling and other learned preprocessing only on the training partition.
Measure false alerts per device over time, missed malicious episodes, family-label errors and end-to-end delay. Repeated records from one attack are not equivalent to many independent incidents, so report the unit of evaluation clearly.
Finally, compare the hybrid model with a simpler classifier on the same features and split. A more complex neural architecture earns its place when it improves the decision the team actually makes at an acceptable operational cost. The same discipline applies to the graph-feature baseline in Ethereum scam detection.
Use the UCI N-BaIoT dataset documentation to preserve the device and attack-file context when constructing a reproduction. Combining files without retaining their origin can make a device-level holdout impossible later.
Scikit-learn's grouped and time-aware validation tools help define evaluations where related observations or future records are separated appropriately. Select the split around the deployment question; a random row split and a new-device test answer different questions.
For the architecture, Keras's Bidirectional wrapper provides bidirectional recurrent processing. It does not decide what the sequence represents or which records were available at prediction time. Resolve those data-contract details before translating the paper's layer diagram into code.
An existing feature pipeline and simple baseline are enough to begin evaluating whether the selected traffic statistics carry useful signal. Add the hybrid stages only after that comparison is reproducible.
This paper is most useful as a candidate architecture with an inspectable error pattern. Its confusion matrix provides more actionable information than the rounded 99% headline.
We would test it as an additional detection signal, with separate criteria for alerting and attack classification. Evidence from new devices, later traffic and realistic alert loads would justify a stronger deployment recommendation. Until then, its benchmark score should guide an experiment rather than a protection promise.
Amna Naeem, Jawad Ahmad, Muazzam A. Khan, Aizaz Ahmad Khattak and Muhammad Shahbaz Khan, Efficient IoT Intrusion Detection with an Improved Attention-Based CNN-BiLSTM Architecture. Version 4, 11 February 2026. Original architecture and confusion matrix are reproduced with attribution for discussion of the method and its results.
Explore transaction-graph signals for scam detection and the limits of a small labeled sample.
Examine why familiar benchmark results may not transfer to incoming real-world media.





