MoonCast research explains how scripts and shared audio context shape AI podcasts, with original results, voice-quality tradeoffs and implementation options.
Select a figure to open it at full size.
A two-person AI podcast can pronounce every word clearly and still sound like two separate readings pasted together. The missing qualities are often conversational: short responses, changes in rhythm, natural turn-taking and continuity between speakers.
MoonCast tackles the problem in two stages. It produces a spoken-style script from source material, then generates the conversation using a speech model that can see a long stretch of context. The paper’s most useful result is that these are connected problems: improving the voice generator does not compensate for a script that reads like an essay.
For teams turning research, training materials or other documents into audio, the question is whether this approach creates a better listening experience without making the content harder to verify.
The script pipeline first builds a structured brief from the source, including its title, authors, abstract, topics, citations and conclusion. A second stage turns that material into a host-and-guest exchange rather than reading the brief aloud.
The role descriptions and prompts in Appendix C show what the authors mean by a conversational script. The speakers explain unfamiliar ideas, respond to each other and use short acknowledgments or fillers where appropriate. The output represents separate speaker turns in structured form.
This is more than inserting “um” into finished paragraphs. A listener needs one speaker’s contribution to create a reason for the other to respond. The script determines those opportunities before the speech model decides how they sound.
There is also an editorial risk. A prompt that adds background explanation may introduce information beyond the source. An audio-production workflow should preserve the brief and script so a reviewer can verify those additions before synthesis. Natural delivery makes a statement easier to hear; it does not make the statement true.
MoonCast uses short reference recordings—roughly three to ten seconds—to establish voices. “Zero-shot” means it can use those reference voices without separately fine-tuning for each speaker. It does not mean generating an identified voice without any reference audio.
The system represents speech as sequences of audio tokens and conditions generation on the script, reference material and speaker changes. At 50 tokens per second, five minutes of audio already produces about 15,000 audio tokens. Long conversational context therefore becomes an engineering requirement, not simply a larger prompt for the script writer.
The model generates a connected token sequence, while a separate component turns chunks into waveform audio. That chunk conversion uses short surrounding references to support continuity. This differs from synthesizing every turn independently and joining the recordings afterward, where changes in rhythm and voice can accumulate at the joins.
Reproducing the trained system is a substantial undertaking. The paper describes an internal processed audio collection of roughly 515,000 hours and training the text-to-semantic model on 64 A100 GPUs. Testing an accessible speech baseline is therefore different from recreating MoonCast’s research training pipeline.
Long context is not unlimited reliability. The paper discusses ambiguous short responses and incorrect speaker assignment, and its training data filters overlapping speech. Its scope is two-speaker Chinese and English conversation, rather than unrestricted multi-person discussion.
The podcast evaluation uses four source materials—two PDFs and two URLs—and five raters. These are small listening tests of generated examples, not audience-retention experiments.

On the English examples, MoonCast receives 4.63 for spontaneity and 4.50 for coherence, compared with 3.78 and 3.80 for CosyVoice2. But its quality score is 4.25 versus 4.33, and its similarity score is 4.08 versus 4.38. The separate automated voice-similarity measure is also lower for MoonCast.
That is an instructive tradeoff. A conversation can sound more natural as an exchange without best reproducing a reference voice. A team producing an educational conversation may weight those properties differently from one whose primary requirement is consistent narration by a particular licensed voice.
The numbers describe the tested systems and historical settings. They are not a current leaderboard for every speech product.
To investigate the script’s contribution, the authors take seven Chinese podcasts containing 125 turns and compare script versions through the same speech-generation system. They contrast the original transcript, a more written-style version and a version with conversational features reintroduced.
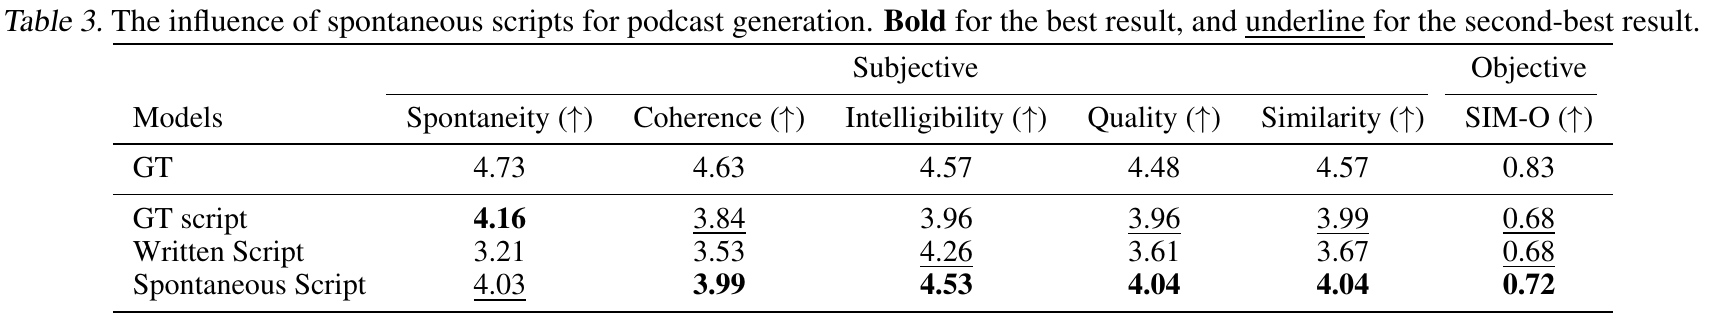
Spontaneity falls from 4.16 with the original transcript to 3.21 with the written-style script, then rises to 4.03 with the spontaneous version. Coherence moves from 3.84 to 3.53 and then 3.99.
The natural recorded audio remains ahead on those measures: 4.73 for spontaneity and 4.63 for coherence. The experiment supports improving the script, while showing that regenerated conversation still has a gap to close.
For a production team, this suggests a useful order of work: inspect whether the script creates a conversation before spending time tuning voice parameters. It also suggests comparing script variants with the speech system held constant, so a perceived improvement has an interpretable cause.
The MoonCast demonstration site lets teams hear the research examples. It should not be treated as proof of a ready-to-deploy production service or an available end-to-end reproduction package.
For an accessible baseline, CosyVoice provides speech-synthesis models and inference code. It is an alternative system for testing your content pipeline, not MoonCast itself. Start with the same approved short script and authorized reference voices across candidates; check the specific model version rather than importing the paper’s historical scores.
A speech-recognition toolkit such as FunASR can help compare a generated transcript with the approved script. Transcription is a screening aid: listen separately for speaker swaps, awkward joins, emphasis and missing meaning.
An initial acceptance review should cover source accuracy, script clarity, voice consistency, turn-taking and editing effort. Keep the ability to repair an individual segment. Do not infer production savings from a listening score; measure the time needed to reach an acceptable final episode.
Our GPT-for-games review makes a related distinction between generated content and content that has passed the review needed for release.
MoonCast is valuable because it treats conversation as more than alternating voices. Its architecture and script experiment explain why shared context and spoken structure matter.
The immediate opportunity is a disciplined document-to-audio workflow: preserve evidence, approve the script, compare synthesis and listen to the complete result. Better spontaneity is worth pursuing when it improves understanding. It should not obscure unsupported additions or weaken control over what the audience hears.
MoonCast: High-Quality Zero-Shot Podcast Generation, Ju and colleagues. Version 2, March 19, 2025. This article uses the method, script prompts, limitations and original Tables 2–3.
Check which facts, qualifications and reporting periods survive an AI-generated summary.
See what user reviews suggest about recovery, control and satisfaction with AI products.





