How MAIR orders restoration tools, where its experiments improve speed, and how to evaluate image fidelity before adopting an agent pipeline.
Select a figure to open it at full size.
A photograph can be dark, noisy and compressed at the same time. Running a good enhancement model on it does not guarantee a good result: brightening the image first may also make its noise more visible, while an aggressive restoration model may add detail that was never captured.
MAIR—Multi-Agent Image Restoration—asks a more specific question: can a system choose a sensible sequence of specialist tools without repeatedly trying large numbers of combinations?
The researchers’ answer combines a model of how images become degraded with a scheduler and specialist agents. In their experiments, MAIR reduced average processing time from 63.04 to 35.42 seconds compared with an earlier agentic system. The contribution is a constrained restoration process, with useful evidence about tool order and selection. It is not a demonstration of real-time processing or universally superior image fidelity.
The paper’s proposed model separates degradation into three stages. Scene conditions introduce problems such as rain, haze or low light. Image capture adds problems such as blur, noise or limited resolution. Storage compression can introduce further artifacts.
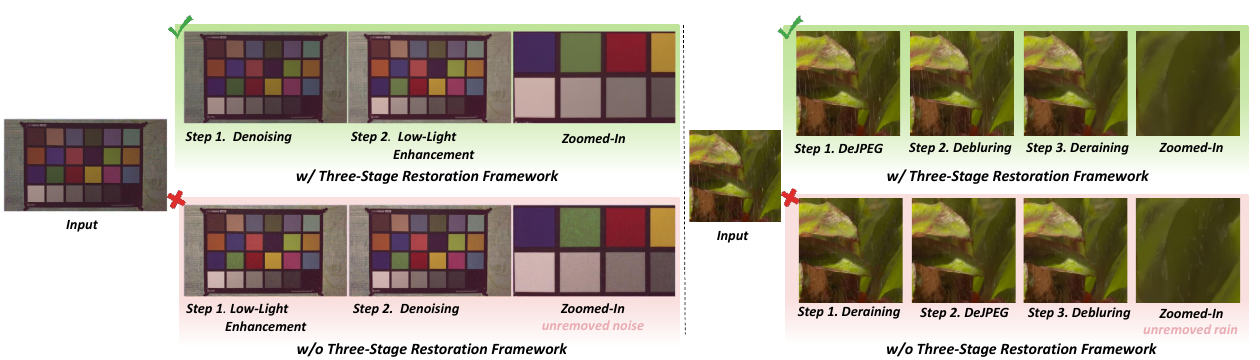
MAIR generally reverses that sequence: remove compression artifacts, address capture-related problems, then handle scene-related problems. The point is to reduce the number of plausible plans. If every repair can occur anywhere, a planner faces many more combinations, including sequences that make subsequent repair harder.
This is a simplifying assumption, not a physical law. Images can pass through editing, recompression and other processes that violate it. The paper also assumes that the available tools can adequately counteract their assigned degradation. A planner cannot recover information simply because it has found a neat ordering.
The researchers tested the ordering idea by trying more than 13,000 tool sequences on five real-world validation sets. Depending on the set, 87% to 98% of the highest-scoring plans followed the proposed framework. The top-three results also strongly favored it. Those results support using the order as a default search constraint; they leave room for exceptions. The ranking combined several image-quality metrics, so “best” here means best under that evaluation, rather than a guarantee of human preference or factual reconstruction.
MAIR does not ask one general agent to remember every tool and solve the entire problem. Its first level builds the plan; its second level performs the repairs.
In the authors’ workflow diagram, the input has compression artifacts, blur and haze. The scheduler proposes JPEG repair, deblurring, super-resolution and dehazing. A perception model, DepictQA, describes the degradation; GPT-4o uses that description, the user’s instruction and stored experience to choose the sequence.
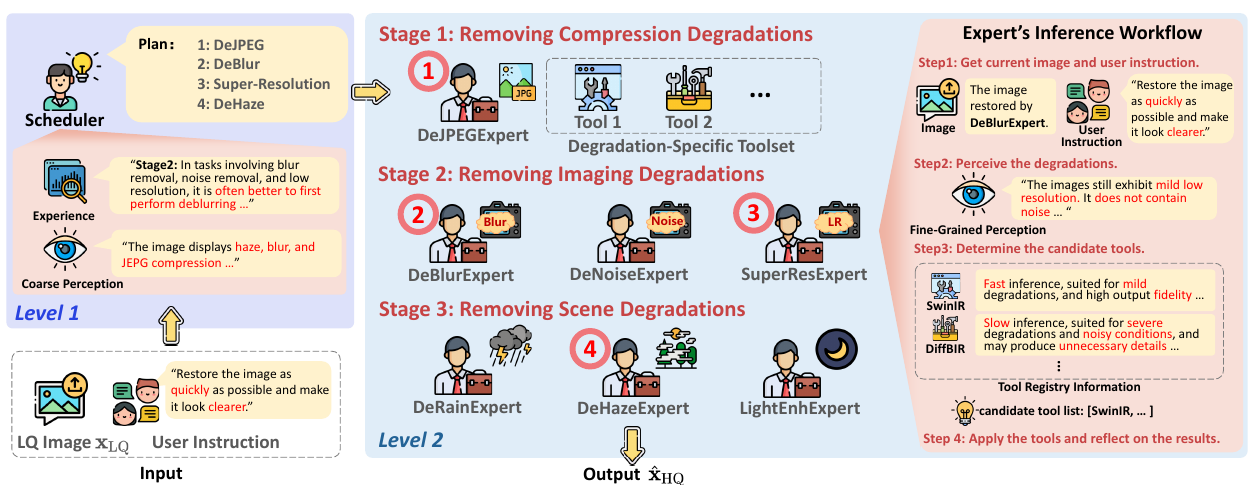
Each expert examines the current image, after any previous repairs. It then chooses candidates from a registry describing what each tool does, the conditions it suits, its speed and relevant weaknesses. That distinction matters: a tool appropriate for mild noise may be inadequate for severe noise, even though both are labeled “denoising.”
The expert applies a candidate and checks whether the targeted degradation has fallen below a threshold. If not, it tries another candidate. If none passes, it compares the candidate outputs and chooses the best available one. The fallback therefore means “best among these attempts,” not “successfully restored.” A production workflow should retain that difference in its status and logs.
Within each of the three broad stages, repair order is still a decision. The authors derive guidance from their earlier restoration attempts, using GPT-4o to summarize sequences that worked well. The system is consequently not reasoning from the input image alone: it benefits from offline experience and specialized pretrained restoration models.
The paper’s color-chart example is more informative than simply saying the architecture is multi-agent. With a dark, noisy input, the successful sequence removes noise before enhancing the lighting. Reversing those operations leaves visible noise in the illustrated result.
Its second example compares two sequences on foliage affected by rain and other degradation. Repairing JPEG artifacts, then blur, then rain produces a cleaner illustrated result than starting with rain removal. These examples show the consequence of changing the intermediate image presented to the next tool.
A separate tool-selection example starts with a heavily noisy image of a lizard. The single-agent configuration chooses a SwinIR setting suited to lower noise; the specialist configuration chooses X-Restormer for the stronger degradation before dehazing. The practical lesson is that a tool registry needs conditions and limitations, not just names and descriptions of ideal use.
Together, these examples make two different claims understandable: choosing a repair sequence matters, and choosing an appropriate tool within that sequence also matters. Neither follows merely from increasing the number of agents.
The evaluation includes 1,440 synthetically degraded images and two real-world test sets: 100 images with reference counterparts and 100 without. The authors use several metrics because closeness to a reference and perceived visual quality are different objectives.
On the real-world sets, Table 5 reports average tool calls falling from 5.15 to 1.82 per image, alongside the processing-time reduction from 63.04 to 35.42 seconds. The experiments used two NVIDIA RTX 3090 GPUs. These are historical measurements of the compared configurations; they do not predict throughput for a different image size, model service or hardware setup.
The quality results also resist a simple winner label. On the paired real-world set, MAIR scores 21.67 on PSNR, a reference-based reconstruction measure, while InstructIR scores 26.01. MAIR performs better than that model on several other measures, but AutoDIR also edges MAIR on MUSIQ in the same table. The full comparison shows why the right choice depends on the quality criterion.
The authors then remove individual components to test their contribution. Removing the three-stage constraint lowers measured quality. Replacing intelligent candidate selection with random selection also hurts performance. In a separate synthetic-set comparison, the multi-agent configuration uses 883 GPT-4o tokens versus 2,410 for the single-agent version while improving the reported quality measures. This supports focused specialist context in this setup; it is not a general rule that multiple agents cost less.
The paper acknowledges two important limitations: its degradation model cannot cover every real-world case, and inference still takes tens of seconds. For an overnight media-processing job, that latency may be acceptable. For a live camera feed, it changes the feasibility of the design.
A useful prototype starts with a small, fixed restoration pipeline and a representative sample of your own images. Keep the untouched originals. Include images that should receive no repair, and examples where texture, text or fine edges must remain faithful.
BasicSR provides a PyTorch-based toolbox for restoration tasks including super-resolution, denoising, deblurring and JPEG artifact removal. It can support the fixed-tool baseline and experiments with individual models. It is not the MAIR scheduler; a team still needs to define the execution order, input compatibility and evaluation procedure.
DepictQA provides image-quality assessment through vision-language models and is part of the paper’s perception approach. Use such a judge to help identify issues and compare outputs, but validate its judgments against human review and downstream task performance. Asking the same type of model to select and approve repairs is not independent proof that important detail survived.
Only after establishing the baseline should you add the MAIR-style choices: a three-stage plan, a small registry of tools with documented operating conditions, and an explicit stopping rule. Existing application code can coordinate those stages; a general multi-agent platform is not required to test the idea.
For a product-photo workflow, evaluate whether repairs preserve labels, colors and small design features as well as improving appearance. For a downstream vision model, evaluate its actual task on both original and restored images. These are different acceptance tests. A visually pleasing output may be a worse input for measurement.
Log the selected tools, intermediate images, processing time and fallback status. Cap attempts and preserve a route to return the original. The useful adoption threshold is an improvement over the fixed pipeline that survives review at an acceptable cost and latency—not merely a higher automatic aesthetic score.
MAIR’s strongest transferable idea is to give an agent a constrained problem and tools described in operational terms. Domain knowledge narrows the plan space; specialists decide within that space; intermediate evaluation determines whether to continue.
That makes it a credible direction for mixed-degradation batch workflows. It does not justify the earlier leap from “clearer images” to better diagnosis, business outcomes or universal accuracy. Those require evidence from the actual downstream task.
For the broader coordination question, see our analysis of agent orchestration and accountable workflows. In both cases, the useful unit of evaluation is the complete process rather than an isolated model response.
Xu Jiang, Gehui Li, Bin Chen and Jian Zhang, Multi-Agent Image Restoration. arXiv:2503.09403v2, 17 March 2025. The reported comparisons, diagrams and examples above refer to that version.
Test whether a model’s reasoning remains grounded in the image it is explaining.
Compare agent-team structures and the point where adding agents stops helping.





