MacNet tests how AI agent team size and network structure affect quality. Learn the scaling limits, merge risks and a practical evaluation approach.
Select a figure to open it at full size.
If one AI agent produces a flawed answer, adding another reviewer can help. But a larger team also creates more messages, more opportunities to lose context and more work deciding which revisions to keep. The useful question is how to organize that extra effort—and when further effort stops paying off.
MacNet, presented at ICLR 2025, studies that question by arranging language-model agents into different networks. The researchers increase network size, compare connection patterns and examine the artifacts those agents produce.
Their results support structured collaboration under the tested conditions, with gains that eventually flatten. They also show that the best structure depends on the task. The paper is a reason to test agent organization deliberately, not a prescription to put a thousand agents into a product.
MacNet organizes collaboration as a directed graph without cycles. Some agents create or revise an artifact—an answer, a piece of code or a written response. Others criticize it and request changes. The direction of the connections determines which work becomes available to whom.
The unusual detail is that agents occupy both parts of the network: actors sit on nodes, while critics sit on connections. An actor’s draft reaches a critic, the critic requests a refinement, and a subsequent actor produces the revised artifact. The paper limits each local interaction to a small number of exchanges in its default configuration.
The original diagrams show both the network choices and a simple software example: a critic requests a graphical interface for a game, and the next actor changes the artifact accordingly.
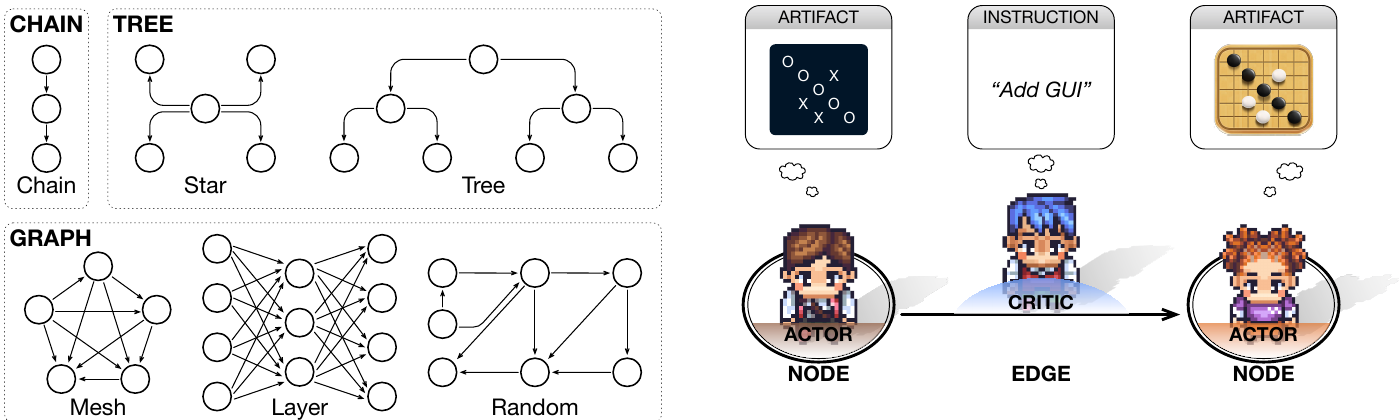
That example explains the unit of progress. Agents are supposed to improve a shared piece of work, rather than simply generate independent answers and vote. A useful critique must result in a change that later agents can preserve or build on.
To avoid sending an ever-growing transcript to everyone, MacNet propagates the final artifact from each local interaction. The detailed conversation stays local. At a branching point, different agents can develop the work in different directions; at a merging point, a downstream agent must combine the incoming artifacts.
This memory rule makes larger networks possible, but it creates a tradeoff. A final artifact may omit the reasoning behind a decision or a requirement that was discussed earlier. The paper itself discusses version rollbacks and lost visibility in deeper structures. Compact communication needs a preservation strategy, not merely a shorter prompt.
The scaling experiments increase the number of actor nodes from one to 64. In a densely connected, acyclic network, each forward connection can also carry a critic.
For example, a fully connected 64-node directed acyclic graph has 2,016 connections. With one critic per connection and 64 actors, that would represent 2,080 agents. This arithmetic explains how a network with dozens of nodes can involve more than a thousand agents; it does not mean that the experiment used a thousand independent model weights or simultaneously running machines.
It also explains why node count is a poor cost estimate. A sparse chain and a dense network with the same number of actor nodes can require very different amounts of interaction. The paper’s memory analysis reduces the context burden on the final receiving agent, but that is not the same as making the total system’s cost grow linearly.
For a product team, the budget should therefore track model calls, input and output tokens, execution time and final quality. “Number of agents” is a configuration detail, not a complete resource measure.
The default comparisons use roughly four actor nodes and GPT-3.5 for the agent interactions. They cover four different tasks: answering knowledge questions, generating functions that pass tests, developing software from requirements, and writing coherent sentences from supplied concepts.
Table 1 averages the task scores into a quantity called “Quality.” The random topology has the highest reported average, 0.6522, compared with 0.6078 for MacNet’s chain and 0.5757 for the chain-of-thought baseline.
But that average hides important differences. On HumanEval, the function-generation benchmark, AgentVerse scores 0.7256 while MacNet-Random scores 0.5244. MacNet-Chain scores 0.3720 there. On the constrained writing task, the tree topology leads the reported MacNet variants. A higher cross-task average therefore does not establish that a configuration is better for your coding assistant—or any one workload.
This is also why it is worth reading the table rather than relying on the paper’s broadest claims. Its numerical results support a more qualified conclusion: collaboration structure changes performance, and the tradeoffs are task-dependent.
The next experiment increases network size. The original chart shows the reported average quality across tasks for six network structures.
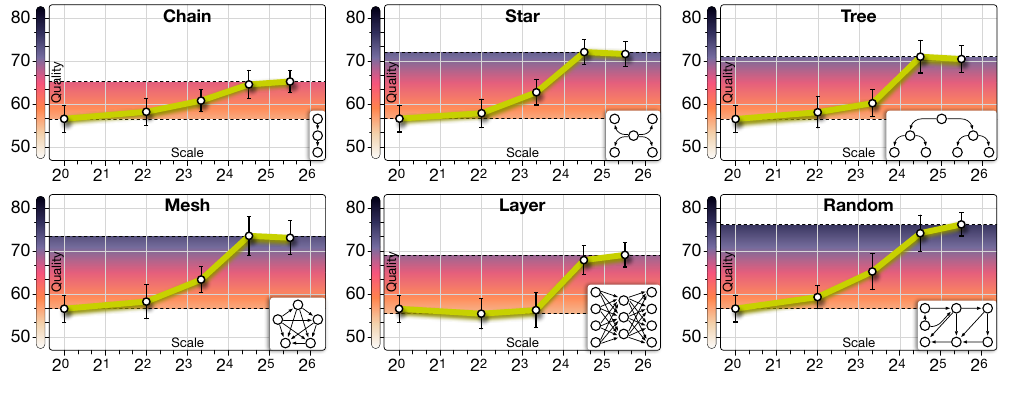
The pattern is generally slow initial improvement, a steeper middle region and eventual saturation. The authors describe a logistic growth pattern and suggest balancing network size with shape and cost.
The plateau is the practical point. Once additional reviewers mostly repeat existing observations or add low-value revisions, more interaction can spend resources without materially improving the result. Different structures reach that point differently, and these historical models and tasks cannot establish where it will occur in a current application.
The study also examines why improvement might happen. In a software-development analysis, larger networks discuss more categories of issues, from syntax and runtime errors to unmet requirements. Generated artifacts become longer too. In the illustrated comparison, artifact length rises from 314 to 2,359 tokens between one and sixteen actor nodes.
That is evidence about what changes during collaboration. It does not prove that length or discussion diversity causes correctness. A longer solution can satisfy more requirements, but it can also create more code to maintain and more opportunities for defects. The evaluation needs to distinguish useful coverage from expansion alone.
MacNet’s branching and merging behavior exposes a problem familiar to engineering teams. Two independently improved versions are not automatically compatible.
Suppose one branch adds a user interface and another changes the data model. A final actor can produce an apparently complete artifact while dropping a validation rule from one branch. Passing only the finished work makes that omission harder to detect if the rule is not represented in the artifact or its tests.
A practical implementation should therefore carry a compact requirements record and executable checks alongside the artifact. That is our recommendation for applying the paper’s memory tradeoff: preserve the facts needed to evaluate a revision, while avoiding indiscriminate transcript sharing.
For code, retain the diff, test results and unresolved requirements. For a research response, retain the claims and their supporting sources. In either case, the next agent should be able to tell what changed and what must remain true.
The broader question of authority and recovery sits outside this benchmark. Our agent orchestration analysis covers those operational responsibilities.
The authors publish a MacNet branch of ChatDev. Its documented workflow generates a graph, configures the model backend and prompts, runs the task in dependency order, and records generated software and interaction logs. Use that research implementation when the goal is to reproduce or extend topology experiments. It should not be treated as evidence of production readiness.
A smaller experiment can use an existing task runner: create an artifact, ask a critic for a bounded review, revise it, then run the same acceptance checks. Add branching only when there is a concrete reason to explore alternatives. This provides a simpler baseline before adopting a larger network.
For a coding workflow, compare a single model, a sequential review-and-revision loop and one branching arrangement on the same held-out tasks. Give each a declared time and token budget. Tests should cover requirements that were not shown in the agent prompts, while a human review checks maintainability and unnecessary complexity.
Track final correctness, regression count, dropped requirements, review burden, latency and spend. Also inspect failed merges: an average score can improve while rare but consequential requirements disappear. Repeat runs because model outputs and randomly generated networks can vary.
Only increase the scale if the next increment improves a meaningful outcome. If the network generates longer artifacts without improving acceptance results, the bottleneck may be the task specification, available evidence or evaluator rather than the number of agents.
MacNet makes agent organization an experimental variable. That is valuable: teams can test who reviews what, which information travels forward and how competing revisions are combined.
The evidence favors careful coordination over a simple headcount story. Start with a small process whose failures you can inspect, then justify every added branch with measured value. We would increase the budget when the system finds and fixes important errors the simpler process misses—not when the architecture diagram acquires more agents.
Chen Qian and colleagues, Scaling Large Language Model-based Multi-Agent Collaboration. ICLR 2025; arXiv:2406.07155v3, 17 March 2025. Results and original diagrams refer to this version.
Explore coordination, ownership and recovery when several agents contribute to one workflow.
Consider when agreement between models adds evidence and when it repeats the same mistake.





