MAP explores how AI assistants handle conflicting user preferences. Understand its retrieval workflow, early results and a practical path to shared scheduling.
Figures open at full size. Wide tables scroll sideways.
An assistant can remember your preferred meeting room and still make a bad booking. Someone else may need that room at the same time, for a higher-priority activity. Serving several people turns personalization into a problem of collecting constraints, resolving conflicts and explaining who gets what.
For teams building workplace assistants, shared-home controls or resource scheduling, MAP offers a useful design lesson: check whose information has been considered before trusting the plan. Its early experiments favor a structured, multi-agent workflow over a single chatbot. They also show that better retrieval does not eliminate planning mistakes.
Christine P. Lee, Jihye Choi and Bilge Mutlu’s MAP research starts with a limitation of individual personalization. A system cannot meet one person’s request responsibly if doing so breaks another person’s rules.
The authors propose three connected stages: gather relevant information, use it to produce and explain a plan, then accept corrections. Their contribution is a workflow built around multiple people’s needs, implemented through agents with separate responsibilities. The system retrieves supplied preferences; it does not discover people’s hidden intentions.
That distinction matters. A fluent answer can conceal a missing constraint. An assistant may explain why it chose the sunny room without revealing that it never retrieved a colleague’s booking. The first question is therefore whether the system has assembled the relevant rules for everyone affected.
MAP separates the work among a Planner, a Rule Manager and a Rule Retriever. Users first supply documents containing preferences, schedules and other rules. Those documents are divided into passages and stored for retrieval.
The Planner receives the request. The Rule Manager breaks the information need into questions for each user, then asks the Rule Retriever to find the answers. The retriever combines keyword and meaning-based search. If an answer is missing, the manager can rephrase its question and try again. It organizes the results by person before returning them to the Planner.
This is more specific than telling an assistant to “consider everyone.” The workflow creates an intermediate record of whose information was collected. The Planner can then resolve conflicts using the supplied policies and explain its choices. The implementation appendix describes this record as a nested structure with a field for each user and subfields for the information required.
The original diagram shows why these stages belong together:
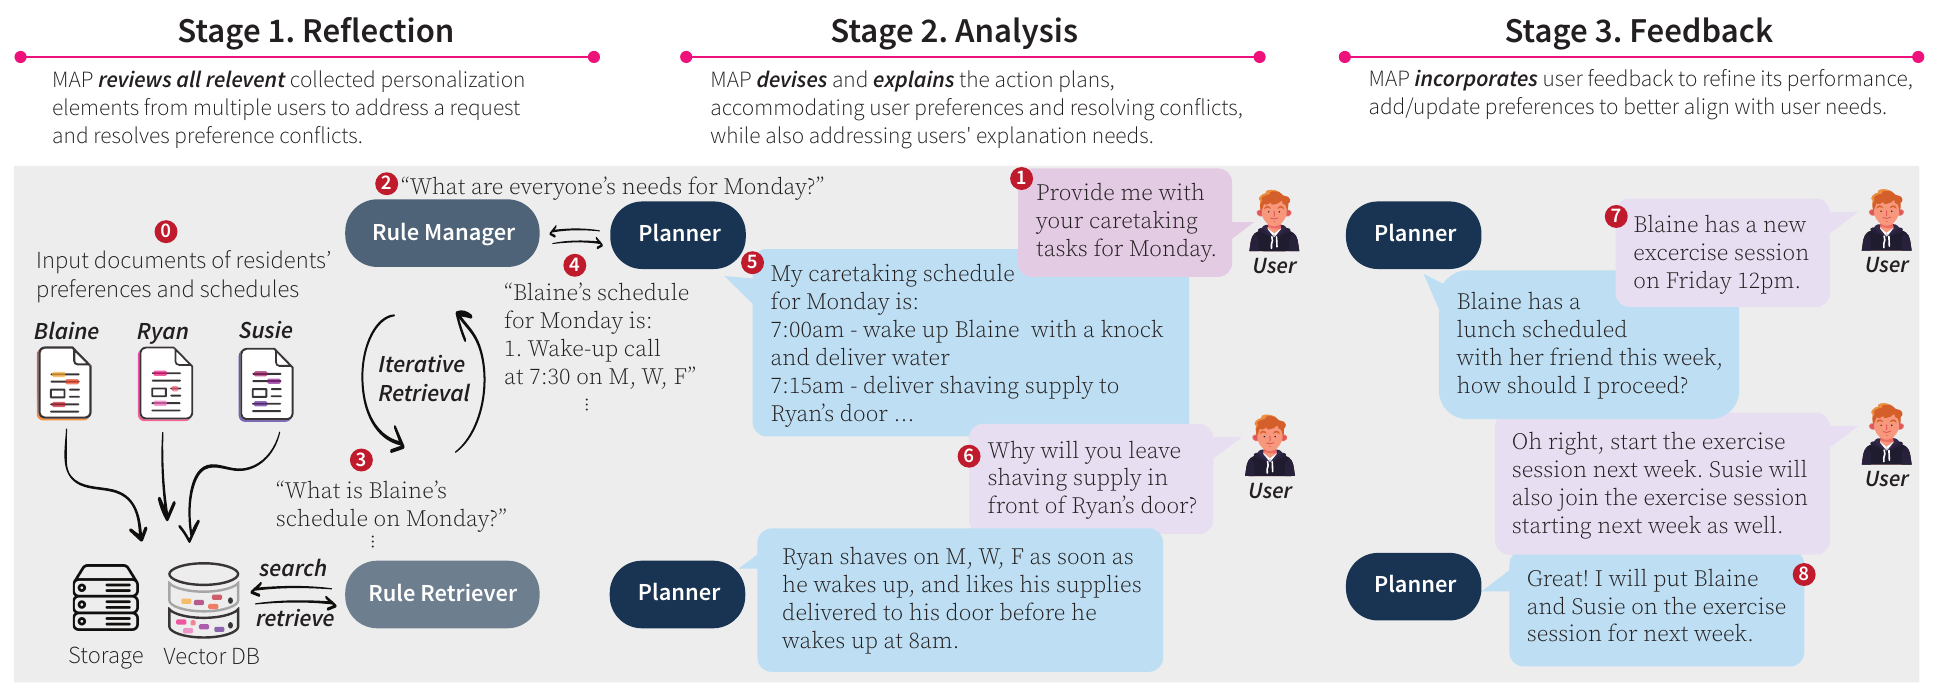
In the diagram’s care scenario, the assistant proposes delivering shaving supplies before a resident wakes. When asked why it will leave them outside the door, it explains the resident’s routine. Later, a user adds an exercise session; the assistant identifies an existing lunch arrangement and asks how to proceed. These exchanges make the underlying schedule visible enough to correct.
The feedback mechanism has an important boundary. The implemented Planner retains corrections in the conversation. The paper describes writing new information back into the document store as future work. A product built from this idea still needs an explicit way to approve, save and revoke lasting changes to someone’s preferences.
The paper’s workplace scenario makes conflict resolution concrete. Employees have different room preferences and schedules. The Planner instructions require retrieving both schedules and preferences for every user. They also specify a priority order: client consultations, team meetings, brainstorming, then other activities.
Consider how those supplied rules apply when two requests compete. The Planner should first check both employees’ availability and requirements. It should allocate the preferred Sun room according to the activity priority, consider the Apple room as an alternative, and suggest another time when neither room is available. The priority policy supplies the decision rule; the language model’s job is to apply and explain it.
This is also where a product team must make a choice the model cannot make on its behalf. Who approved that priority order? Which requirements are mandatory, and which can be negotiated? MAP’s other scenarios use different policies. Its shared-home example sends temperature disagreements back to the housemates for discussion. Its fictional care scenario uses alphabetical priority. That last rule is an experimental simplification, not a policy to import into a care product.
The quantitative comparison uses three researcher-designed scenarios: meeting rooms, an assistive robot and shared-home temperatures. Each contains three users, 60 rules about preferences and schedules, and 12 conflicts. Each system produces five weekday plans over three runs: 45 plans per condition, or 90 in total. The researchers compare them with a reference solution written by the scenario designer.
The evaluation asks two practical questions: did the system retrieve the relevant information, and did it identify and resolve the conflicts? These are different failure points. A missing preference can make a conflict invisible; a retrieved preference can still be applied incorrectly.
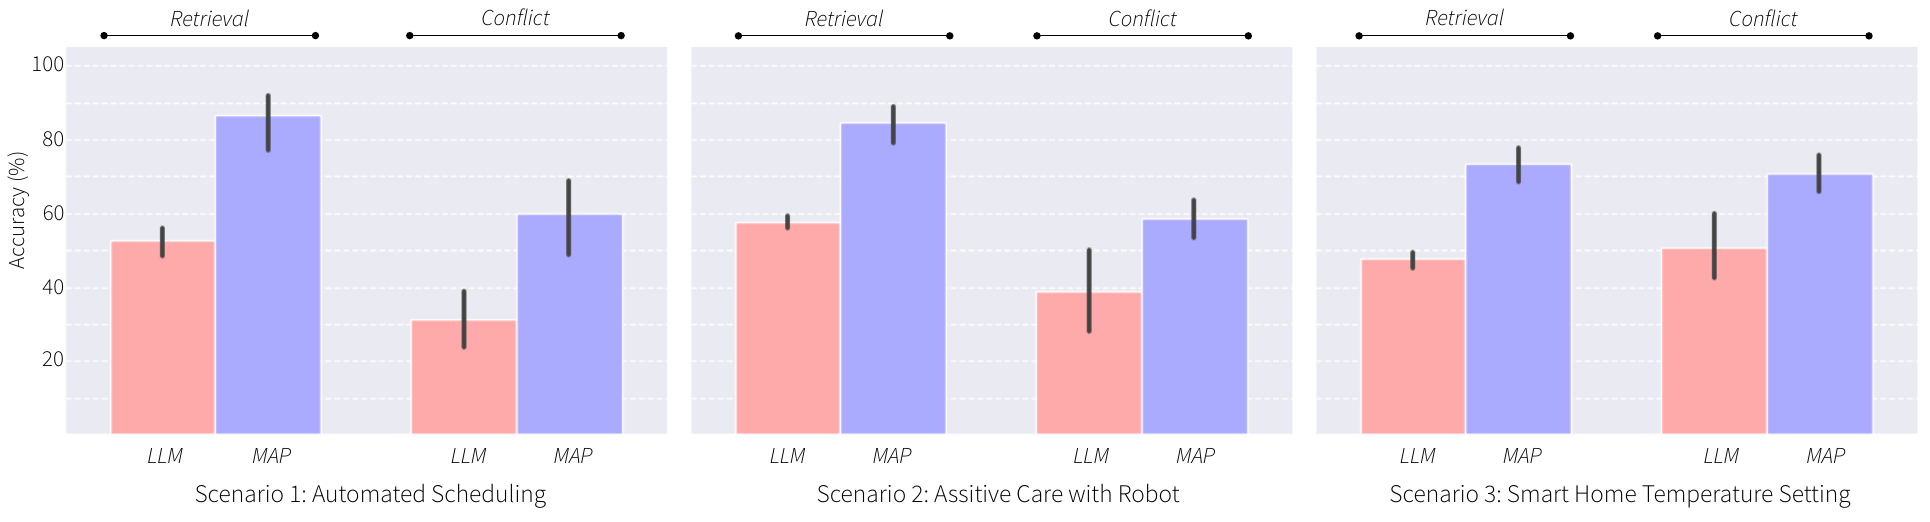
The chart shows MAP ahead in all three scenarios. In workplace scheduling, for example, the bars put retrieval at roughly the mid-80% range and conflict handling around 60%, compared with roughly 50% and 30% for the single-chat approach. These are approximate readings from the figure, not exact published table values. The gap between retrieving information and resolving conflicts is itself useful: assembling the rulebook is necessary, but it does not guarantee a correct schedule.
The comparison also changes several things at once. The research repository describes its monolithic baseline as a chat agent without retrieval-augmented generation. The results therefore support the complete MAP workflow over that baseline. They do not establish that three agents outperform one agent given the same retrieved information, validation checks and inference budget.
A separate qualitative study involved 12 participants recruited through a university mailing list. Participants used hypothetical scenarios rather than operating the system in their own workplaces or homes. Eleven reported reduced effort or time, but seven also identified problems such as missing information, unresolved conflicts or inconsistent decisions. Those responses support interest in the interaction design; they are not measured productivity gains from a deployment. The user-study findings also describe demand for visibility into the rules the system used.
The strongest initial application is an assistant that proposes a shared plan for approval. Meeting rooms, team equipment and support coverage all have identifiable users, resources and competing requirements. A useful product should show the proposed allocation alongside the constraints that shaped it, including unresolved disagreements.
For a scheduling pilot, keep a record for each request: person, activity, time window, resource, mandatory requirements, preferences and source. This is our implementation recommendation, derived from MAP’s emphasis on complete retrieval. If any required field is missing, ask for it before presenting the plan as complete.
Then test three approaches on the same cases: the existing scheduling process, a single assistant with the complete rule record, and the MAP-style division of work. Include collisions, updated preferences, unavailable rooms and contradictory instructions. Count missed constraints and unresolved conflicts separately, alongside review time and inference cost. If the structured single assistant performs just as well, the extra orchestration has not earned its complexity.
Corrections need their own test. Change an employee’s availability, rerun the plan and check both the immediate answer and the next session. A correction that survives only within one conversation is a different capability from a durable preference update. This connects to the broader problem of keeping agent plans consistent as circumstances change.
MAP’s published code is the closest starting point for studying the design. Its repository contains documents and scenario-specific examples built with Langroid, plus a single-chat baseline. Begin with the workplace example and synthetic preferences so you can compare retrieved rules with known answers. Treat the repository as a research implementation: its historical model configuration and dependencies need checking in your environment before use.
Langroid supplies the agent and retrieval building blocks. Its DocChatAgent documentation describes document ingestion into a vector store and answering with retrieved passages. That can support MAP’s information-gathering stage; it does not establish that every user’s constraints have been retrieved. Record coverage explicitly and preserve the source of each rule.
For a small, structured scheduling problem, an ordinary database and validation code may be enough. Check room collisions and mandatory time constraints deterministically, then use the assistant to interpret requests and explain alternatives. Separate preference changes from permissions to act. An employee’s request should not silently become an organization-wide allocation policy.
MAP makes a persuasive case for treating shared personalization as a visible process. Its most transferable idea is the intermediate rule record: the system should be able to show whose needs informed its decision before anyone accepts the plan.
The evidence is early, and the remaining conflict errors argue for supervised proposals. We would adopt the workflow’s explicit retrieval, explanation and correction stages first, then retain multiple agents only if a matched comparison shows that they improve reliability enough to justify their cost.
MAP: Multi-user Personalization with Collaborative LLM-powered Agents, by Christine P. Lee, Jihye Choi and Bilge Mutlu. CHI EA 2025; this article uses arXiv version 2, dated March 18, 2025. The original figures are reproduced with attribution under CC BY 4.0.
Explore why remembering a preference is different from applying it appropriately.
Collect individual constraints and preferences before asking an AI to choose for a group.
Examine how conversation context becomes the next tool call and its arguments.





