Research on AI-generated characters shows why prompt rewriting alone can fail, how negative prompts help, and where detection and utility still matter.
Select a figure to open it at full size.
An image generator can produce a recognizable character even when the prompt never names it. A description can carry the same visual associations: clothing, occupation, colors and distinctive features may be enough.
That creates a practical problem for teams trying to enforce a policy against particular character outputs. A name filter may pass the request, and a prompt rewrite may preserve precisely the features that make the result recognizable.
The ICLR 2025 paper Fantastic Copyrighted Beasts and How (Not) to Generate Them investigates this gap. It tests ways to reduce character recognition while preserving a useful generic image. Its strongest lesson is to evaluate both outcomes together. A system that avoids every targeted character by refusing every request has not solved the product problem.
The study asks two connected questions. First, how readily do image and video models produce recognizable characters from indirect descriptions? Second, can interventions reduce those outputs without discarding the user’s broader request?
The authors evaluate a list of 50 well-known characters using several generation models. Their main mitigation comparison focuses on Playground v2.5, with additional tests on other image models and VideoFusion. These are the systems and configurations studied in the paper; the results do not establish the behavior of current commercial services.
The authors deliberately use character recognition as a measurable proxy. Their automated detector asks whether the image contains an identifiable character. That does not determine whether a particular output infringes copyright, nor does passing the detector establish permission to use it.
For a product team, the test is useful as a policy evaluation: does this intervention reduce a specified class of outputs, and what useful requests does it damage along the way?
The paper’s indirect-anchor method generates candidate descriptions and keywords, then ranks them in several ways. One method looks for words close to the character’s name in an embedding space. Another looks for words that frequently appear alongside the name in a corpus. A language model’s ranked suggestions provide a further comparison.
The reasoning is straightforward: if a model has repeatedly encountered a character alongside a set of attributes, that attribute bundle may point toward the character even without its name. The paper’s familiar plumber example illustrates the effect. A nominally generic request can still activate a very specific visual association.
The researchers find that short keyword sets can be effective triggers, and that longer descriptions can also generate recognizable characters. This does not prove which individual training records caused a given output. It does show why testing only exact names misses an important class of requests.
The same issue can undermine a rewrite. Replacing a character name with a detailed physical description may remove the obvious string while preserving the recognizable combination. The text looks more generic to a simple filter, but the generation problem remains.
Prompt rewriting changes the positive description sent to the image model. It can remove a name, alter features or redirect the image toward a more generic subject.
Negative prompting supplies concepts the generation process should move away from, where the model and interface support it. In this study, those negative prompts include a target name and selected associated keywords. This is different from adding a sentence such as “do not copy” to an ordinary text instruction: the negative prompt is a distinct input to the diffusion-generation process.
The researchers compare each control separately and then combine them. The original image grid makes the difference visible. Its first row uses character names without mitigation. Subsequent rows add negative prompting, rewriting, or both.
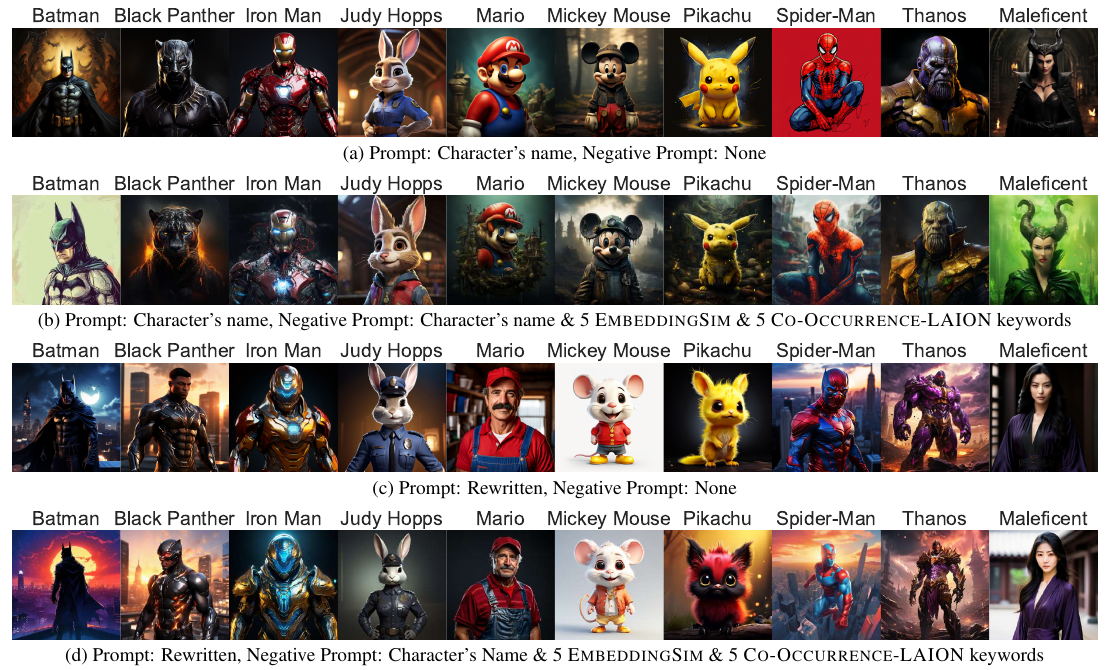
Look at the difference between replacing a name and changing the resulting appearance. Some rewritten-only examples remain readily recognizable. The combined approach often moves further away while keeping a broad category such as a mouse or a costumed person. Whether that is useful depends on the actual request; preserving a generic category is a narrower goal than satisfying every detail.
The main table evaluates two things. DETECT counts how many of the 50 target characters the evaluator recognizes. CONS assesses whether the generated image retains a general requested characteristic. Lower detection and higher consistency are desirable under the study’s objective.
Across three runs on Playground v2.5, the average detection count is 30.33 with no intervention. Rewriting alone reduces it to 14.33. Combining rewriting with the target name and two sets of associated keywords in the negative prompt reduces it further to 4.33. The corresponding consistency scores are 0.75, 0.80 and 0.81.
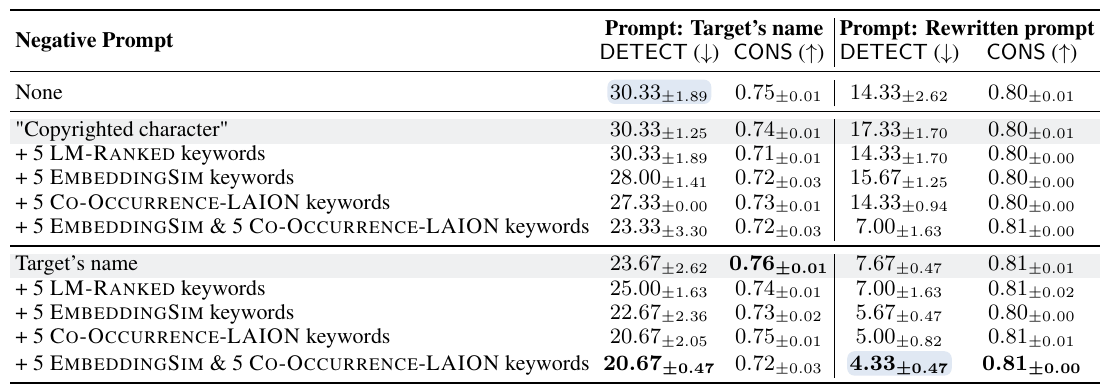
This is evidence that the controls can complement one another. It is also evidence of residual failures: the combined count is reduced, not eliminated. Results differ across models. In the cross-model comparison, VideoFusion still has an average detection count of 11.33 with the combined intervention.
Consistency needs equally careful interpretation. A score for whether the output depicts a cartoon mouse does not test all aspects of a user’s intent, image quality or satisfaction. It prevents one obvious failure—solving the detection problem by producing unrelated images—but it is not a full product-quality measure.
The detector itself is imperfect. In an appendix check using 200 images and author annotations, GPT-4V agrees with the majority human judgment 82.5% of the time. A team should therefore inspect examples and audit disagreements rather than turn the automatic count into a certificate.
The mitigation experiment assumes that the system knows which character is relevant so it can construct the negative prompt. In an actual product, many incoming requests will be ordinary descriptions with no intended reference to a character.
Appendix E.2 explores two ways to identify possible references: asking a language model and retrieving similar descriptions from a character database. Those experiments use a balanced set of character descriptions and ordinary prompts. They support the feasibility of an additional detection stage, but do not remove the need to test false alarms and missed references in real traffic.
This matters operationally. If the detector associates too many generic animals or occupations with known characters, the system may unnecessarily distort legitimate requests. If it misses an indirect reference, the targeted negative prompt may never be applied. A good result from the generation stage cannot compensate for a poorly evaluated routing stage.
The authors’ CopyCat repository provides the research evaluation components: generation configurations, prompt sets, character detection and consistency scoring. Use it as a reproducible experiment structure. Its historical model dependencies and evaluation assumptions still need checking in your environment; no deployment performance is established by the repository alone.
For an experiment with a supported diffusion model, the Diffusers SDXL pipeline exposes negative-prompt inputs. That provides a place to test the paper’s generation-side intervention. It does not supply the character-reference detector or decide which outputs your product should allow.
A minimal evaluation can use your existing generation runner and four conditions: unchanged prompt, rewrite only, negative prompt only, and both. Keep model versions and other settings fixed, record seeds and repeat samples. Include benign requests near the same concepts so the evaluation measures unnecessary changes as well as targeted detections.
Review a sample of outputs with people who understand the policy and the intended use. Separate the questions: Is the targeted character recognizable? Does the image meet the legitimate request? Did the system refuse, distort or misclassify a benign input? Record uncertain cases instead of forcing every judgment into a confident yes or no.
Then test the complete sequence, including the initial reference detector. Measure how often it routes correctly and how much extra latency and review work the controls create. This catches a failure that isolated mitigation numbers cannot: applying a good control to the wrong requests.
Our guardrails analysis develops the same broader evaluation principle—measure protection alongside the useful activity that the protection can interrupt.
The paper offers a practical correction to a weak assumption: removing a forbidden name from a prompt does not necessarily remove the model’s association with the character.
The useful response is an end-to-end evaluation of reference detection, generation controls and retained utility. Rewriting and negative prompting are candidate components, with measured benefits in these experiments. Neither eliminates the need to inspect failures or establishes that an output is legally cleared.
A release decision should rest on performance against your policy and your users’ legitimate tasks, using current model configurations. A low score on one historical detector is supporting evidence, not the decision itself.
Luxi He, Yangsibo Huang, Weijia Shi and colleagues, Fantastic Copyrighted Beasts and How (Not) to Generate Them. ICLR 2025; arXiv:2406.14526v2, 26 March 2025. The examples, tables and mitigation findings above refer to that version.
Separate data provenance, permission records and payment mechanisms in generative AI.
Compare harmful-request detection with the legitimate work a safety filter can accidentally block.





