Why minimizing pipeline communication can sacrifice parallelism—and how the research compares grouping, startup time and execution time.
Figures open at full size. Wide tables scroll sideways.
Two pipeline stages can run faster when they share an execution environment and avoid communicating across a boundary. Put too much work into one group, however, and independent branches may lose the opportunity to run in parallel.
That tradeoff is the subject of Automated Planning for Optimal Data Pipeline Instantiation. The researchers use automated planning to decide how operators should be grouped for execution, while respecting their software requirements. Their experiments show why neither “minimize groups” nor “maximize parallelism” is a sufficient rule on its own.
For a data-platform team, the useful question is where time is actually spent: starting environments, moving data between groups or executing the work inside them.
A pipeline is represented as a graph. Operators perform work; connections carry data between them. Operators also have requirements—such as a library or runtime—which must be available in the container image assigned to their group.
The researchers work with the VFlow engine. Their optimizer changes the grouping of operators and the associated execution images. It does not rewrite the analytical meaning of the pipeline, invent a new business transformation or continuously reroute live traffic in response to demand.
The workflow converts a VFlow graph from JSON into a planning problem expressed in PDDL. One file describes the available actions and costs; another describes this particular graph and its requirements. The ENHSP planner produces a grouping plan, which is converted back into a VFlow graph and executed for measurement.
This makes the optimization rule explicit. A planner can search for a configuration that scores well under its specified costs, but those costs still need to correspond to the runtime behavior the team cares about.
The paper compares two main heuristics.
The connection heuristic makes communication across groups more expensive than communication within a group. In the model, the respective costs are 20 and 5. These are planning weights, not measured network latencies. The intention is to keep connected work together where possible.
The node heuristic strongly penalizes creating groups and treats the two types of communication equally. It favors packing more operators into fewer groups, even if that produces more crossings between them.
The original comparison shows why these objectives differ. Both illustrated arrangements use two groups. In the connection-oriented arrangement, only one connection crosses the group boundary. In the node-oriented arrangement, several do.
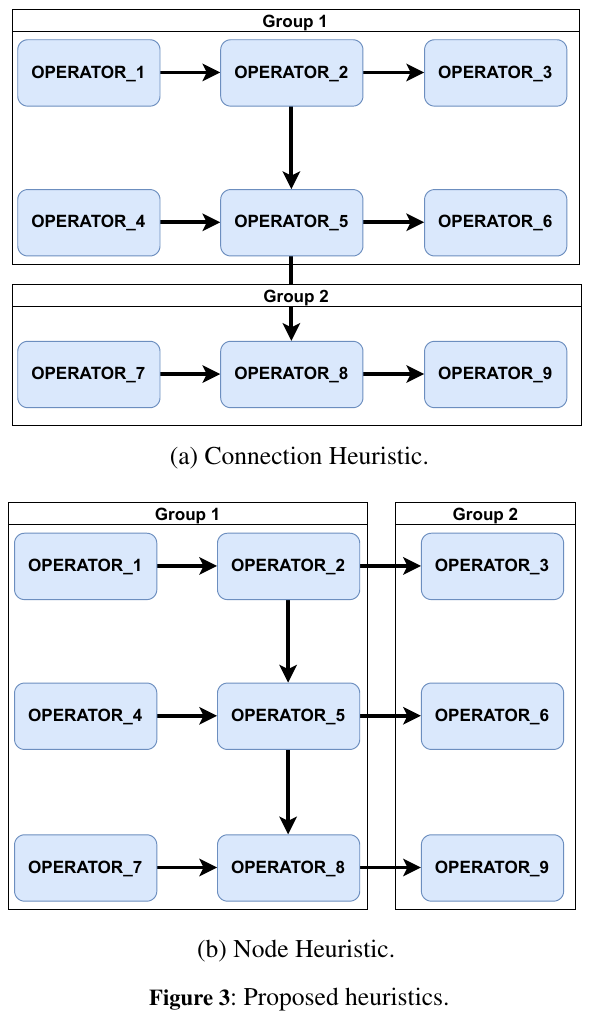
A grouping must also satisfy the operators’ requirements. If two operators require incompatible images, an attractive arrangement on paper may not be executable. That is why image compatibility is part of the planning problem rather than a deployment detail to check afterward.
The evaluation uses synthetic pipelines with 14 operators: twelve perform computation, one generates work and one marks completion. The computational work calculates Fibonacci numbers, allowing the researchers to increase its intensity. They test a sequential arrangement and a parallel arrangement with three lines of four computational operators.
Special requirement tags make grouping nontrivial. The experiments run on a cloud cluster with two worker nodes. Each graph is run five times, and the first execution is distinguished from later executions because startup behavior differs.
The measurements separate setup time, execution time and their sum. That separation is essential to understanding the results. Creating more groups might shorten computation while increasing the time needed to prepare their environments.
The original parallel-pipeline chart below shows one such case. The random grouping has shorter execution than some alternatives but substantially greater setup time, leaving its total worse in this configuration.
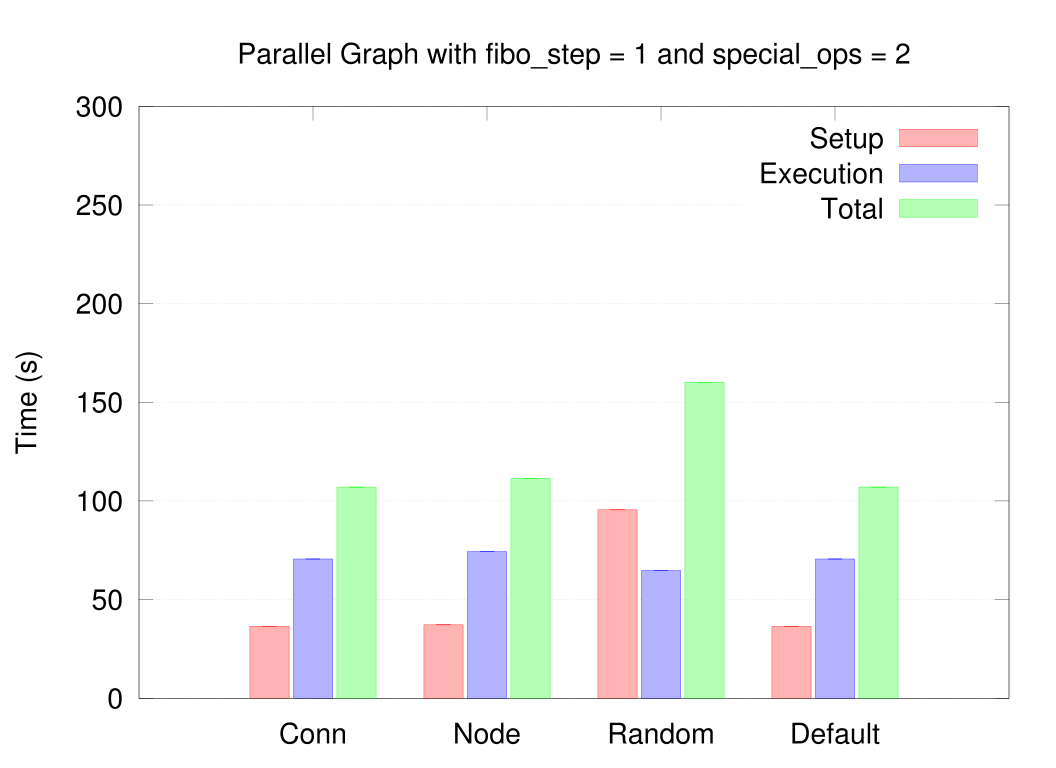
Across the study, the connection heuristic is a strong general performer. But the authors also report parallel cases where random grouping performs well, because additional groups can expose more parallel execution. Some total-time differences are small relative to the reported variation. When the workload gets heavier, execution gains can outweigh extra setup cost.
That is the substantive result: the best objective depends on the graph and workload. A connection-focused heuristic does not explicitly account for all potential parallelism, and the authors suggest further work on hybrid strategies.
The study’s default baseline places all operators in one group. The authors explain that this would not be viable if the synthetic special tags represented real incompatible software requirements. It is useful for showing the effects of grouping, but it is not always a deployable alternative.
A production evaluation therefore needs a valid current configuration as its baseline, not only the fastest unconstrained arrangement. Otherwise, an optimization could appear to lose against an impossible deployment—or appear useful only because the comparison ignores real constraints.
The paper optimizes total execution time. It does not establish cloud-cost savings or resilience improvements. More groups can consume different resources, and a faster run need not be cheaper. Cost and resilience are identified as possible future objectives, so they need separate measurement in an adoption decision.
Consider a pipeline with several independent transformations that later join their outputs. A useful investigation would ask which neighboring stages exchange substantial data, which branches can run concurrently and which stages require different software environments.
Measure the current valid deployment first. Keep cold starts separate from warm runs. Then test a small set of compatible alternatives: co-locate strongly connected stages, preserve independent branches where concurrency helps, and compare against the current layout using the same workload.
This follows the research without assuming that VFlow’s behavior applies identically to every engine. Some engines already fuse operators or schedule work differently. The grouping boundary must have a real execution consequence in your system for this optimization to matter.
Your existing engine’s profiler comes first. Capture setup and execution separately, together with transferred data, resource use and output correctness. A few measured alternatives can establish whether grouping is an important bottleneck before you build a planner integration.
ENHSP is a candidate when explicit constraints make manual search difficult. The official project accepts a PDDL domain and problem and searches for a plan. The Unified Planning integration provides another route to describing supported numeric planning problems. Optimality guarantees depend on the problem class; a plan that minimizes a modeled cost is not automatically the fastest deployment under actual runtime conditions.
A minimal integration needs a graph exporter, a representation of image requirements, a cost model, a planner invocation and a converter back to an executable graph. Validate compatibility and preserve the original graph so candidate groupings can be compared and reverted. The research paper’s conversion pipeline makes these components visible; ENHSP does not supply a universal drop-in optimizer for Airflow, Dagster or every other orchestration engine.
Use held-out workload sizes and both cold and warm runs. Reject an arrangement that improves mean completion time while breaking correctness, resource limits or an important latency requirement. If resource spending is the business objective, record it directly rather than deriving it from a faster chart. For a different infrastructure-optimization tradeoff, see our E2ETune database analysis.
This paper provides a useful way to reason about deployment boundaries. Its strongest lesson is that group count, communication and parallelism are separate variables.
Start with measurement and a valid baseline. Introduce automated planning when the constraint space is large enough to justify it, and judge the generated arrangement in the actual engine. The evidence supports investigating better grouping; it does not support a general promise of self-optimizing infrastructure or lower cloud bills.
Automated Planning for Optimal Data Pipeline Instantiation, Leonardo Rosa Amado and colleagues. arXiv version 1, submitted 16 March 2025. The work includes SAP Labs participation and support. The illustrations above are original source figures, including a PDF extraction of the two grouping strategies.
Weigh faster configuration search against preparation cost and achieved database performance.
Compare inference-routing decisions when the preferred accelerator is unavailable.





