An SMS study compares AI and human phishing messages. Understand intended clicks, contextual relevance and what the evidence means for security training.
Select a figure to open it at full size.
An AI-generated message does not need to look obviously artificial to be dangerous. But a convincing example also does not tell a security team how often employees would click it in daily life.
This study compares GPT-4-generated and human-authored spear-phishing SMS messages using a structured participant exercise. Its value lies in showing how people assess messages, what context makes them plausible and how easily claims about “click rates” can overreach the measurement.
For security leaders, the practical question is how to turn those observations into better training and evaluation without pretending a tabletop judgment is a live attack result.
The researchers collected personal-context information and prepared messages related to participants’ jobs, hobbies and social interests. Human messages came from novice student authors working under a deadline; the AI condition used GPT-4. This is a specific comparison, not a contest between AI and experienced professional attackers.
Twenty-five participants returned from an initial group of 41. Each assessed 12 messages, producing 300 message judgments: 150 for each source.
Participants arranged printed messages from most to least likely to prompt a click, then placed a threshold indicating where they believed they would have clicked. The original figure shows the procedure:

This design lets participants compare messages and explain their reasoning. It also changes the task: they know they are evaluating suspicious messages and see several together. The resulting intended-click rate should not be used as a forecast of employee behavior in ordinary conditions.
GPT-4 messages receive an intended-click rate of 28.0%, versus 21.3% for human-authored messages. The estimated difference is 6.7 percentage points, but the reported 95% confidence interval runs from −2.9 to 16.3 points and the p-value is 0.147.
In plain language, this sample does not establish that the AI messages are more effective. It also does not establish that the two sources are equivalent. The estimate is too uncertain to support either strong conclusion.
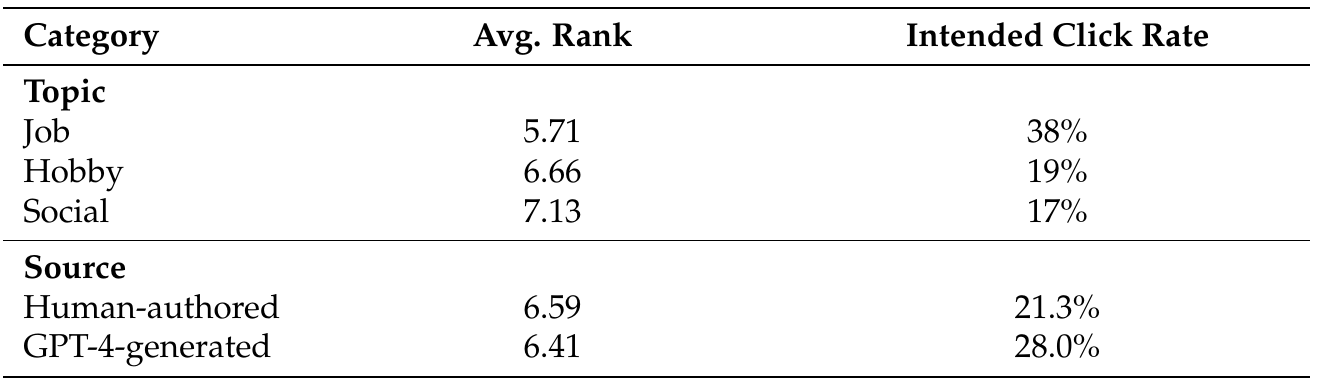
Job-related messages attract higher stated click intention than hobby or social messages. Those percentages describe this exercise and its participants. They are useful evidence that context deserves attention, not universal rates for those categories.
Participants identify the message source correctly in 156 of 300 judgments, or 52%. The uncertainty interval includes chance performance. Recognizing whether AI wrote a message is therefore a weak basis for a defense in this study.
A security program should ask whether the request is legitimate, whether its claimed context is true and whether the action can be verified through a trusted route. “Does this sound like AI?” is a different question, and one the participants did not answer reliably.
The qualitative findings show that personalized content can fail when it does not fit the recipient’s actual situation. One example involves an invented colleague and a work-related pretext that did not match the participant’s responsibilities. The mismatch itself raised suspicion.
The mechanism is straightforward. A message may contain a true detail about someone’s job while drawing a false conclusion about whom they work with or what they handle. Surface relevance creates an opening; accurate contextual knowledge can close it.
This is a stronger training lesson than telling staff to search for awkward wording. Ask them to inspect the relationship, request and expected workflow. Does the claimed sender actually belong in this process? Is the proposed action something that person would normally request? Can the request be confirmed without following the message’s link?
These questions follow from the reported participant reasoning. The paper does not test whether teaching them reduces subsequent real-world incidents; that remains an evaluation a training program would need to perform.
The authors propose a ranking-and-discussion approach, TRAPD, for examining message judgments. It makes uncertainty and reasoning visible: participants choose a boundary, then discuss why particular messages fall on either side.
The paper also acknowledges that the method needs further validation, including repeatability and a clearer relationship to real clicking behavior. A team can use it to learn what people notice without treating it as a calibrated security-risk meter.
For an authorized training session, use an approved collection of benign example messages and conceal source labels initially. Ask participants to rank them, explain the most consequential choices and identify a safe verification step. Reveal the source afterward. The valuable output is the reasoning pattern and the misconceptions exposed, rather than an AI-versus-human scorecard.
Do not compare a later live simulation directly with these paper-card percentages. The delivery channel, participant awareness and opportunities to act differ. Keep the methods separate so a change in measurement is not mistaken for a change in risk.
This research does not require a new model deployment to be useful. An existing training platform, survey tool or set of printed cards can support the ranking, threshold and discussion stages. Record topic, source, judgment and explanation separately so the team can examine why messages were persuasive.
Start with a small facilitated exercise, then revise the training around observed misconceptions. Evaluate learning with new examples rather than repeating the same messages. If the organization also runs authorized operational simulations, use its established process and report those outcomes separately.
The same separation between a model-related score and a real operating outcome appears in our guardrails evaluation analysis. The question is what behavior the measurement actually captures.
The study’s most useful message is that plausible context matters and perceived authorship is an unreliable shortcut. Its small sample and stated-intention method do not justify a claim that AI has conclusively outperformed human attackers.
Use the research to improve what people examine in a suspicious request. Measure the training’s effectiveness in the setting where it will be used, and keep the difference between recognizing a risk and resisting it visible.
Assessing AI-Generated vs. Human-Authored Spear Phishing SMS Attacks: An Empirical Study, Francia and colleagues. Version 3, August 17, 2026; published in the Journal of Cybersecurity and Privacy, 2026, 6, 129. Original Figure 3 and Table 1 are reproduced for discussion of the method and findings.
Examine how personality-driven agents create background activity for cyber-deception experiments.
Examine why familiar benchmark results may not transfer to incoming real-world media.





