Spiking-network research tests membership leakage across time steps and training methods. Explore original results, accuracy tradeoffs and privacy evaluation.
Select a figure to open it at full size.
Spiking neural networks process information through activity over time rather than the usual pattern of continuous neural activations. That architectural difference raises an attractive possibility: could a model be efficient and also reveal less about its training data?
On the Privacy Risks of Spiking Neural Networks tests a specific part of that question. The researchers ask whether an attacker can infer that an image was included in a model’s training set by examining its outputs.
Their results show why “spiking” should not be treated as a privacy guarantee. Some tested spiking models leak less membership information than a conventional model, but the outcome changes with time steps, training method and the attacker’s probing technique.
A membership-inference attack does not necessarily recover the training record. It asks a narrower question: was this particular example used to train the model?
That can still matter. A model may respond more confidently to familiar training examples than to otherwise similar examples it has not seen. An attacker can use those differences as evidence of membership.
The paper evaluates attacks against image classifiers on CIFAR-10 and CIFAR-100, using architectures including ResNet18. The attacker can observe model confidence outputs and uses reference or shadow models under the study’s assumptions. These are controlled image-classification experiments, not tests on patient records or a deployed financial system.
Some spiking models are produced through an ANN-to-SNN conversion and training process; the paper also studies directly trained SNNs. The distinction becomes important when interpreting the results.
The converted models process inputs over different numbers of steps, represented by T. T=1 and T=4 mean one and four computation steps in this experiment; the numbers are not milliseconds of production latency.
The original table reports several attack methods. Focus on the highlighted RMIA rows to follow the main comparison. Its “1%” column gives the percentage of actual members detected when the threshold permits a 1% false-positive rate among nonmembers.
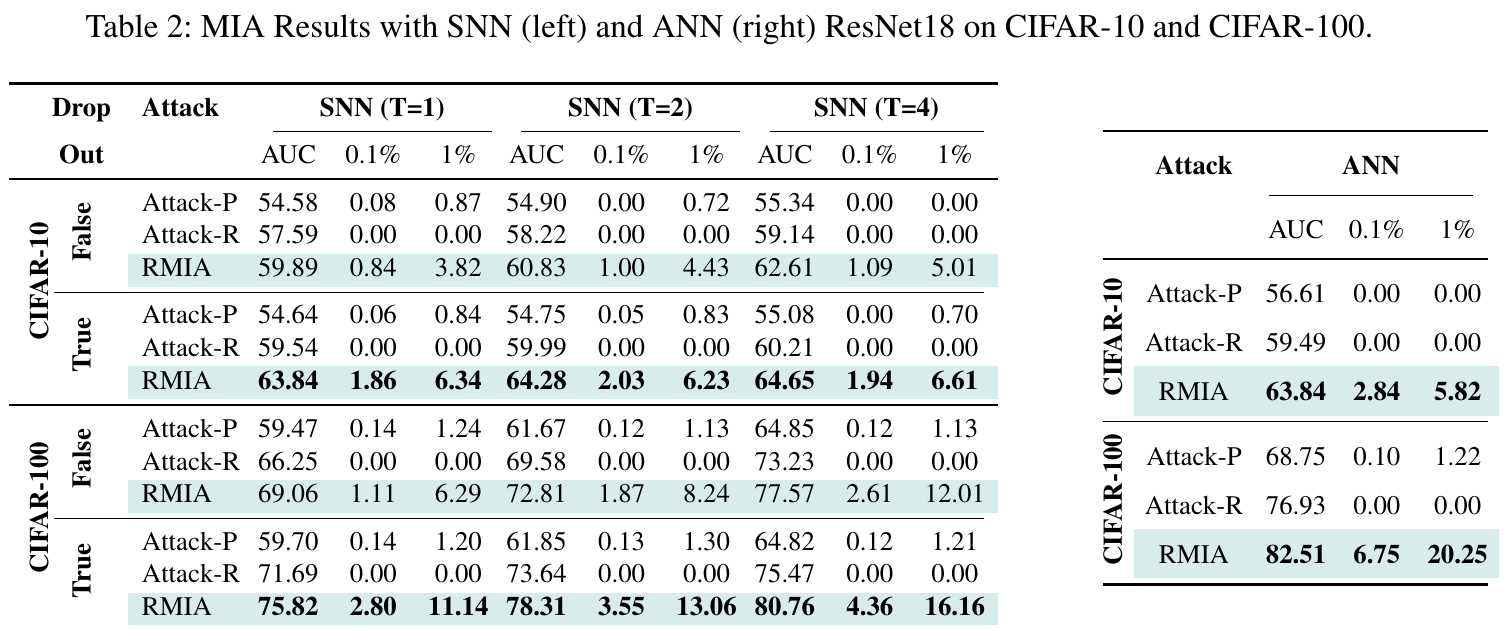
For CIFAR-100, the one-step converted model has a member-detection rate of 6.29% at that threshold without the input-dropout technique. The four-step model reaches 12.01%. Under the stronger probing technique, those values rise to 11.14% and 16.16% respectively. The conventional ANN comparison reports 20.25%.
The threshold has a concrete interpretation: among 100 nonmember examples, the test allows about one false membership accusation on average. At that operating point, the stronger attack detects roughly 16% of actual members for the four-step model. This is not a claim that 16% of a real organization’s database was exposed.
The table also reports AUC, which summarizes how well attack scores separate members from nonmembers across thresholds. It is not directly an attack success percentage. The fixed-false-positive comparison is more useful when the reader wants to understand the tradeoff between finding members and falsely accusing nonmembers.
“Dropout” often appears in discussions of training and regularization. Here, input dropout is an attack technique. The attacker randomly masks portions of an input, queries the model repeatedly and combines the resulting confidence information.
The purpose is to reveal differences in how the model responds to perturbed member and nonmember examples. It is not a defense added to the victim model, and the experiment should not be read as evidence that enabling a training-layer dropout setting improves privacy.
This makes the threat model operationally important. A service that returns detailed confidence values and permits repeated probes exposes a different interface from one that returns a constrained result. The paper tests specified attacker capabilities; a team needs to map those capabilities to its own system before translating the results into risk.
The privacy comparison is incomplete without classification quality. On CIFAR-100, the converted one-step model has 59.5% test accuracy, the four-step model 63.9%, and the conventional ANN 69.5%.
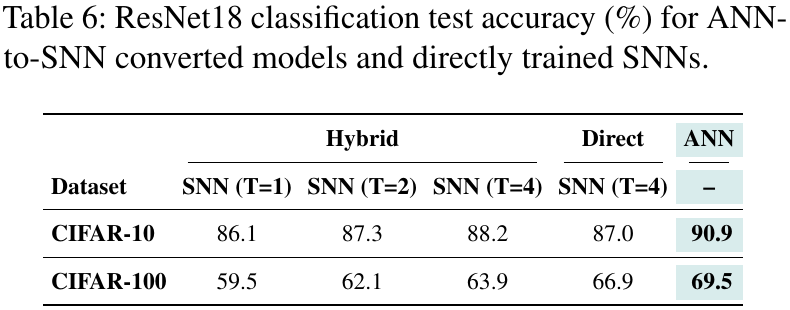
Choosing the one-step model solely because its attack result is lower would ignore the task performance sacrificed in this setup. A practical comparison should retain both measures and examine acceptable operating points.
Training method also changes the picture. The paper’s direct-training comparison reports CIFAR-100 RMIA AUC rising from 59.62 to 62.11 with the input-dropout attack for the four-step model, versus 80.76 in the converted-model result above. Those are different training configurations, so they should not be collapsed into a single number for “SNN privacy.” The direct-training analysis and Table 5 are an important limit on broad architectural claims.
The research therefore supports evaluation, not a blanket recommendation to replace conventional networks with spiking ones. Dataset, training procedure, time steps and attacker access all matter.
The authors’ MIA_SNN repository provides code for the training, conversion and membership-attack workflow. It is the relevant starting point for reproducing the study’s conditions rather than substituting a generic privacy score.
For an authorized evaluation of your own model, preserve separate member and nonmember examples, document what outputs an attacker can see and reproduce the baseline attack before adding stronger probes. Record the query budget and the assumptions behind any shadow models.
Compare configurations at the same task requirements. Report classification accuracy alongside member detection at chosen false-positive rates, and include uncertainty from repeated runs where feasible. A lower attack score caused by an unusable classifier is not a successful product tradeoff.
If the deployed interface differs from the research setup, test that interface explicitly. Restricting outputs or queries may change what this attack can observe, but the paper does not establish those choices as complete privacy defenses. Our guardrails evaluation article similarly argues for testing the actual operating boundary rather than relying on a model label.
This research is valuable because it turns an architectural intuition into a measurable question and then shows where the answer changes. Spiking models can exhibit lower leakage in particular comparisons, while remaining vulnerable to stronger probing.
Use the result to improve the evaluation plan. Choose the model only after examining task quality and privacy under realistic access conditions. Architecture can influence risk; it does not certify the absence of it.
On the Privacy Risks of Spiking Neural Networks: A Membership Inference Analysis, Guan and colleagues. Version 4, June 11, 2025. This article uses the original Tables 2 and 6, with the direct-training counterexample from Table 5.
Examine how industrial sites can learn together while keeping their raw operating data local.
Compare another federated-learning application: exchanging model information across sketch collections.





