How LLMs collect preferences and revise team decisions. Explore the original meeting example, simulation results and the limits of automated consensus.
Select a figure to open it at full size.
Scheduling a meeting is a small example of a larger coordination problem. People have different constraints, preferences and reasons for those preferences. A shared time slot can satisfy the calendar while still being a poor choice for the group.
Papachristou, Yang and Hsu investigate whether language models can help by collecting individual preferences, proposing options and revising them against explicit feedback. Their system treats coordination as a loop, rather than asking one chatbot to produce an answer from a group conversation.
For teams considering AI coordination, the most useful distinction is between helping people evaluate options and deciding that those people have agreed.
The system first conducts individual conversations and extracts preferences into a form the coordinator can use. The coordinator receives those preferences, combines them with available background information and proposes options with reasons.
An evaluator then assesses the options against each member’s preferences. The system uses that feedback to revise the proposal, retaining the strongest candidate found so far rather than assuming every new response is better.
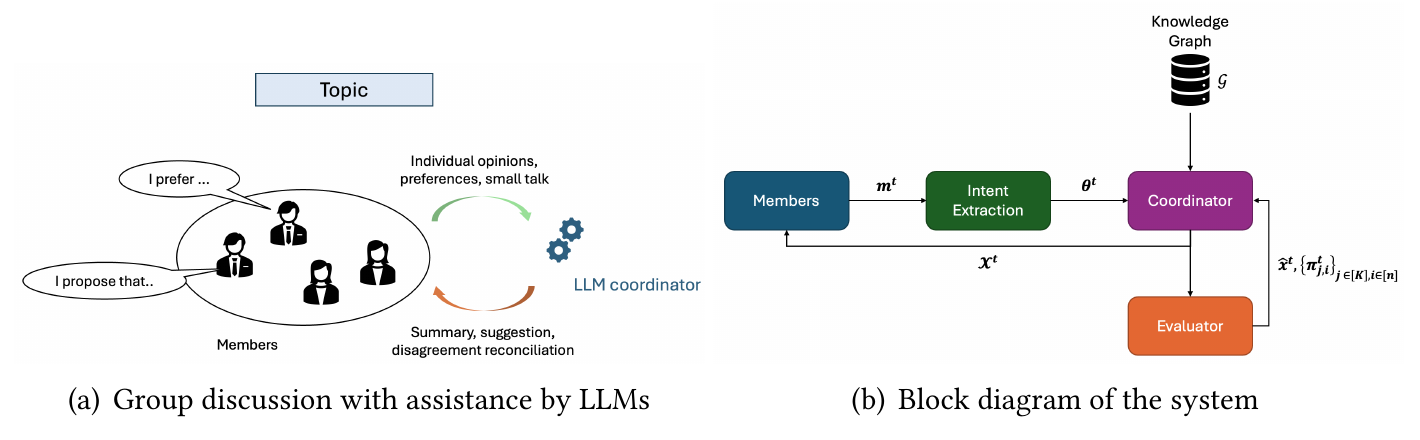
The paper studies meeting coordination as a concrete setting. The important input is more than a list of free times: it includes individual preferences that conversation can help surface. The optional database supplies external context rather than expecting the model to invent it.
Consider how the loop should be interpreted. Extracting a person’s preference produces a claim about what they want. Generating an option produces a claim that a possible decision addresses those wants. Evaluating the option checks the second claim against the first. If the first claim is wrong, a very consistent evaluator can still recommend the wrong decision. A practical system therefore needs a way for members to correct the extracted preferences.
In the authors’ three-member example, two people prefer morning meetings. One wants to protect afternoon deep-work time; another uses the rest of the day for coding and debugging. The third person prefers afternoons, preserving mornings for prospecting and following up with customers.
The coordinator proposes a morning option that it scores as meeting all revealed preferences of members 1 and 3, and an afternoon option that serves member 2 and part of member 3’s preferences. The alternatives expose the disagreement instead of hiding it in a single recommended time.
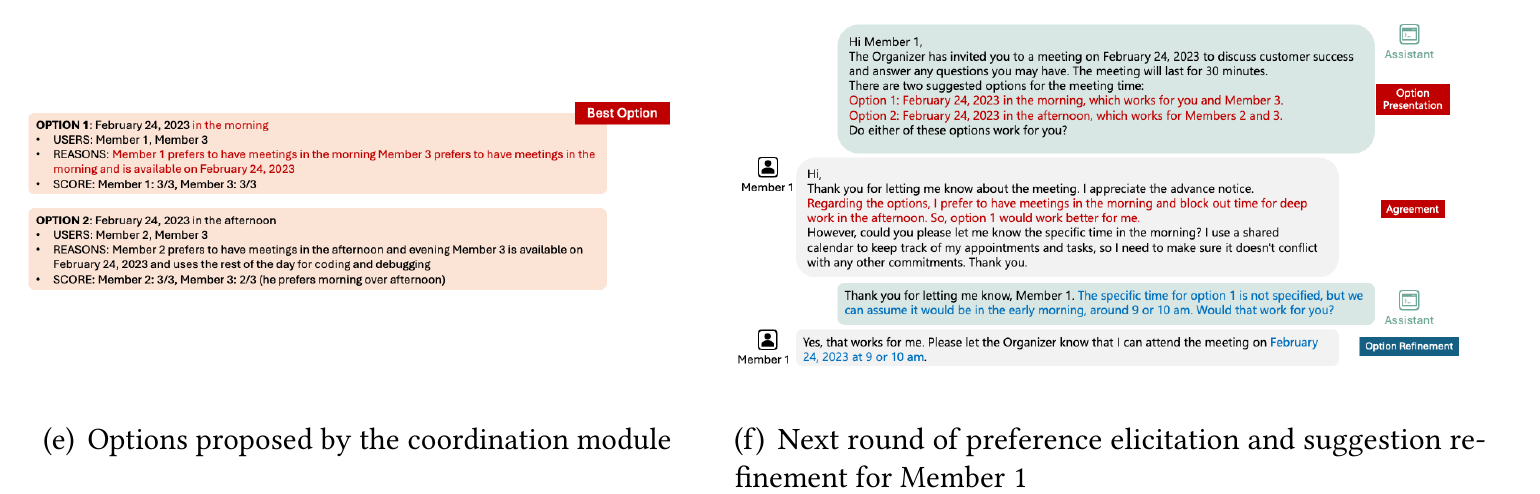
Member 1 then favors the morning option but asks for a specific time. The next exchange narrows the suggestion to around 9 or 10 a.m. That is the point of the loop: a broad preference is a starting point for clarification, not permission to book any slot in that period. The example demonstrates the interaction; it does not show a real meeting successfully completed.
The coordinator’s selection rule first favors options that satisfy at least one preference for as many members as possible. It then uses the average amount of preference fulfillment to distinguish candidates.
That definition is useful, but narrower than everyday agreement. Someone can have one minor preference satisfied while an important requirement remains unmet. An option that covers every person under this rule is not automatically acceptable to every person.
For implementation, hard constraints need a separate treatment. A person being unavailable is not just another preference that can be balanced against convenience. The paper’s objective helps explain its experimental results; a product team must decide which requirements are mandatory before adapting that objective.
The principal comparisons use simulated members and model-based evaluation. They compare the proposed iterative system with single-round conversational and non-conversational approaches, varying group size and the number of options.
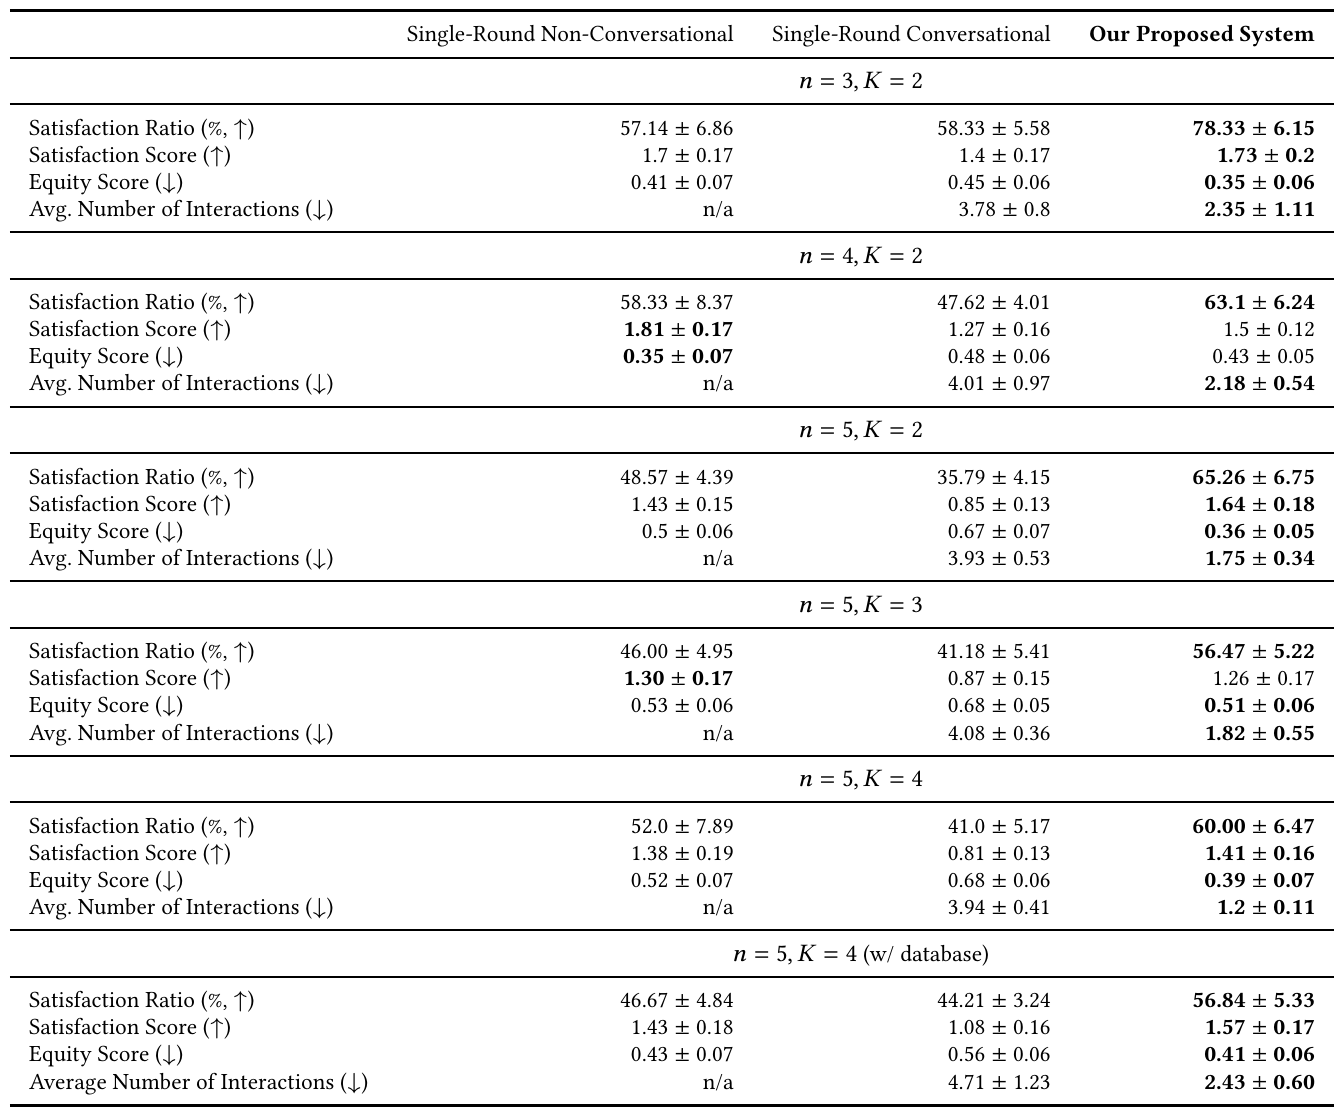
For five members and two options, the proposed system achieves a satisfaction ratio of 65.26%, compared with 48.57% for the non-conversational baseline and 35.79% for the conversational baseline. Under the paper’s definition, this concerns how many simulated members have a preference met by the selected candidate option; it is not a percentage of real teams that successfully scheduled a meeting.
The proposed system averages 1.75 interactions in that condition, versus 3.93 for the conversational baseline. That suggests a way structured collection and evaluation could reduce conversational effort, subject to the simulation’s assumptions.
The table also contains counterevidence. With four members and two options, the non-conversational baseline has a higher satisfaction score, 1.81 versus 1.50, and a better equity score, 0.35 versus 0.43, where lower is better. There is no universal win across every configuration and measure.
The full comparison is more useful than a single improvement claim. Group size, option count, evaluation criteria and supplied information all influence the result.
The study also collects feedback from 45 people on synthetic scenarios. Participants evaluate the proposed outcomes and explanations; they are not 45 teams using the system to negotiate their own actual meetings.
Their mean ratings include 3.51 out of 5 for taking preferences into account, 3.32 for acceptable reasons and 3.07 for how well the proposed options reflect the overall preferences. These are encouraging but moderate responses, not evidence of effortless acceptance.
There is a useful mismatch between the simulations and preferences expressed by participants. Many participants prefer three options, even though the simulation often favors two. A mathematically stronger score does not settle how much choice users want to see. The human evaluation and survey materials make that distinction important for product design.
An existing form, database and workflow service may be enough for an initial implementation. Collect preferences, let each participant verify them, generate a small option set and show which requirements each option meets or violates. Calendar feasibility should be checked against actual availability, not inferred from conversational confidence.
LangGraph is one option when the workflow needs persistent state, repeated evaluation and pauses for human input. Its role is coordinating those steps; it does not supply a validated definition of fairness or agreement.
A minimal pilot should compare the current coordination process with a preference-assisted one on a bounded decision. Measure corrections to extracted preferences, unacceptable options, time to a confirmed decision and whether any participant repeatedly receives poor outcomes. Require explicit confirmation before booking or committing the result.
Our agent-architecture analysis explains why the action boundary matters: a proposal and an authorized state change are different stages of the system.
The promising role for an LLM is making preferences easier to express and tradeoffs easier to inspect. The study gives that idea a concrete architecture and exposes how the objective changes the result.
Build around verified preferences and visible reasons. Keep consent with the participants, and judge the system on actual decisions rather than on simulated satisfaction alone. Coordination improves when the group understands the choice—not merely when a model can score it.
Leveraging Large Language Models for Collective Decision-Making, Marios Papachristou, Longqi Yang and Chin-Chia Hsu. Version 3, March 17, 2025. Original Figures 1 and 3 (selected panels), and Table 1 accompany the explanation above.
Explore how a shared assistant should handle conflicting preferences and constraints.
Examine how conversation context becomes the next tool call and its arguments.





