Why reward-model accuracy alone cannot predict useful AI training. Research explains policy-specific feedback, learning curves and selection tradeoffs.
Select a figure to open it at full size.
A reward model can reliably recognize the better answer and still be a poor teacher. That matters when a team selects a reward model from a leaderboard and assumes its ranking accuracy will translate into faster or better language-model training.
The Princeton researchers behind What Makes a Reward Model a Good Teacher? investigate the missing connection: how the scores assigned to a model’s own outputs affect the direction and speed of learning. Their answer is more useful than another ranking. Evaluate the reward model and the policy being trained together.
Here, the policy is the language model that generates responses. The reward model scores those responses, providing feedback that a reinforcement-learning procedure uses to adjust what the policy produces.
Imagine a policy frequently generates two answers to a prompt. One is substantially better, but its reward is only slightly higher. A ranking test counts the comparison as correct. The learning procedure, however, receives little separation between these common outputs.
The paper formalizes this distinction. Accuracy concerns whether rewards point toward better outputs. Reward variance, measured over outputs the current policy actually generates, concerns how much the scores differ. The latter helps characterize the strength of the learning signal.
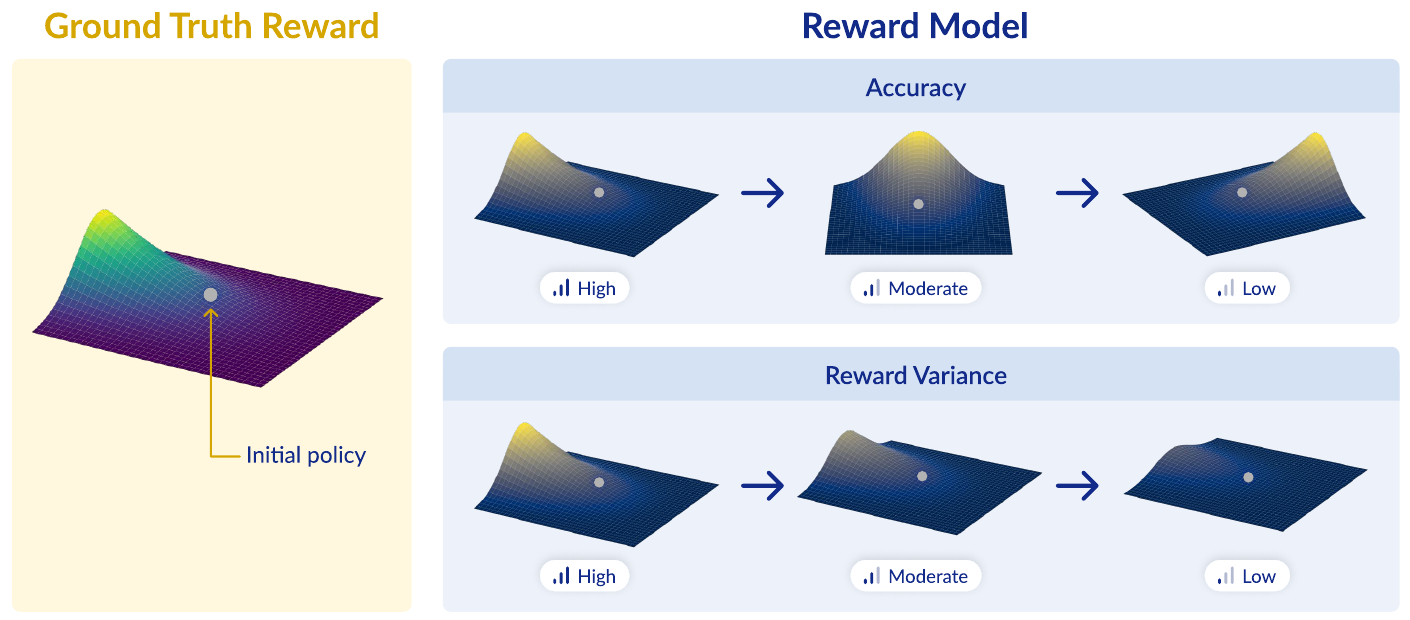
The lower row is the important addition. Even a surface pointing toward the correct answer can be very flat around the policy’s current behavior. Evaluating only which answer wins misses that problem.
This does not mean choosing the noisiest reward model or multiplying every score by a large number. The researchers normalize reward scales for comparison. Arbitrary noise can create variation while directing learning toward worse outputs. The question is whether useful differences are visible among plausible responses, alongside adequate accuracy.
The mathematical analysis studies simplified optimization settings, including exact-gradient learning dynamics. It motivates what to measure; it does not promise a particular speedup for every production training run.
In the main language-model experiment, the authors start with a supervised-fine-tuned Pythia-2.8B policy. They build reward models using different mixtures of response pairs: some generated by that starting policy, others from the broader UltraFeedback data.
They also construct a revealing comparison: a reward model with perfect ordering relative to their reference reward, but deliberately compressed score differences. “Perfect” here is relative to ArmoRM, another model used as the evaluation reference, not perfect agreement with all human preferences.
Training uses RLOO, a reinforcement-learning method, over six epochs, with three runs. The two panels below answer different questions: is the policy getting better at satisfying its training reward, and is it improving according to the separate reference?
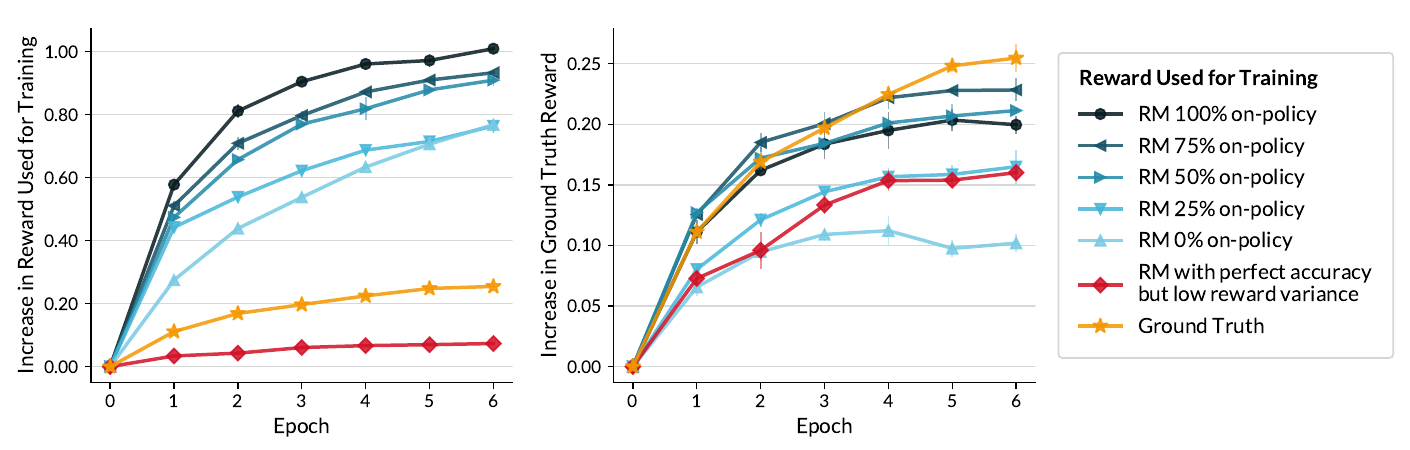
The compressed, perfectly ordered reward—the red line—produces weak progress. Some imperfect reward models teach the policy faster early in training. Yet the model supplying the reference reward eventually overtakes them on the right-hand evaluation. Strong early movement and the best eventual outcome are different properties.
The left panel also shows why monitoring the training score alone is unsafe. A policy can keep improving that score while gains on the reference evaluation flatten or deteriorate. The practical task is to reward useful behavior, not simply behavior that earns high marks from one scorer.
The paper’s Table 1 makes the policy dependence concrete. A reward model trained entirely on the starting policy’s outputs has lower accuracy on the off-policy comparison set than one trained entirely on off-policy data: 0.630 versus 0.762. But it has greater reward variation around the actual starting policy: 0.630 versus 0.314 after normalization.
Those numbers describe different properties, even where a numerical value happens to repeat. The off-policy accuracy asks about a collection of comparisons. The variance asks about the scores this particular policy encounters during learning. A model can look attractive on the former while giving less helpful feedback on the latter.
The appendix provides an important qualification. In another configuration, reward variance by itself correlates only moderately with reference-reward improvement, while a measure combining accuracy and variance correlates more strongly. The relationship changes with the experiment. These small, deliberately constructed comparisons do not establish a universal selection formula. They establish a reason to measure more than ranking accuracy. See the alternative-policy experiments and Table 4.
There is also a task boundary: selecting the best answer from a fixed set is different from teaching a policy to generate better answers. A perfectly accurate ranking can be ideal for the first job without being the fastest teacher for the second.
The researchers’ released code provides the most direct route to their training and evaluation setup, using PyTorch and TRL. Start with its documented configurations when reproducing the result; changing models, reward scaling or training settings changes the experiment.
For an internal selection process, generate response pairs from your actual starting policy on representative prompts. Compare candidate scorers on pairwise correctness and normalized score variation. Then run small training trials with the same budget and inspect quality using a separate evaluation process, including human review where your acceptance criteria require it.
Retain the learning curves, not just the final score. They reveal whether a candidate learns quickly, stalls, or begins exploiting its scorer. Include the simplest acceptable baseline—for example, the existing supervised model—so that extra training must earn its operational cost.
Our guardrails research analysis addresses a related evaluation discipline: an attractive aggregate score must be translated into the behavior the product needs.
Reward-model selection should be a compatibility test. The scorer, starting policy, prompt distribution and training procedure jointly determine whether the feedback is useful.
Accuracy remains necessary evidence. It is insufficient evidence for buying an expensive training run. A short, controlled learning experiment can reveal a weak teacher that a ranking leaderboard would never flag—and an initially promising teacher whose gains do not last.
What Makes a Reward Model a Good Teacher? An Optimization Perspective, Razin and colleagues. Version 4, February 27, 2026; NeurIPS 2025 paper. This article uses its analysis, experiments, appendix checks and original Figures 1–2.
Compare prompts using representative tasks and evaluation examples held out from optimization.
Follow a domain-specific training pipeline and the checks needed before accepting its drafts.





