MCCoder connects AI-generated motion code with simulation and trajectory checks. Explore the experiment, original diagrams and a practical evaluation path.
Figures open at full size. Wide tables scroll sideways.
A motion-control program can run without errors and still move a machine the wrong way. It might select the correct function but use the wrong axis, trigger a movement too early, or reach the requested destination along an unacceptable path. For automation teams, generating plausible Python is only the beginning of the job.
MCCoder investigates whether a language model becomes more useful when it works inside an engineering workflow: break down the request, retrieve the right motion-library documentation, generate code, run it in simulation, and inspect what it actually does. The study reports substantial improvements on some programming tasks. It also shows why a passing endpoint check is an incomplete basis for trusting motion code.
For an engineering leader evaluating this approach, the useful question is specific: Can it produce programs your team can verify more efficiently, without weakening the checks that matter for your machine?
The researchers focus on Python programs that call the WMX3 motion library. This is a particular programming environment, with many functions and variations in their arguments. Choosing a function with a familiar name does not establish that it accepts the parameters required for a particular movement.
MCCoder combines generation with a software-based motion controller, whose simulation engine can execute a program and record its behavior. The model therefore receives concrete feedback about execution errors. Engineers can also inspect the movement over time, rather than judge correctness from code alone.
That distinction matters even when two programs reach the same destination. One could follow the intended curve while another cuts across it. Where the route matters, agreement at the final position misses the essential requirement. The paper’s verification design makes the execution trace part of the evidence used to assess a program.
The authors’ architecture diagram starts with a request containing three operations: move one axis, change a digital output, and coordinate two other axes in a straight-line movement. The system must preserve the requested axis identifiers and parameters while finding the appropriate library calls.
MCCoder handles that request through a connected sequence:
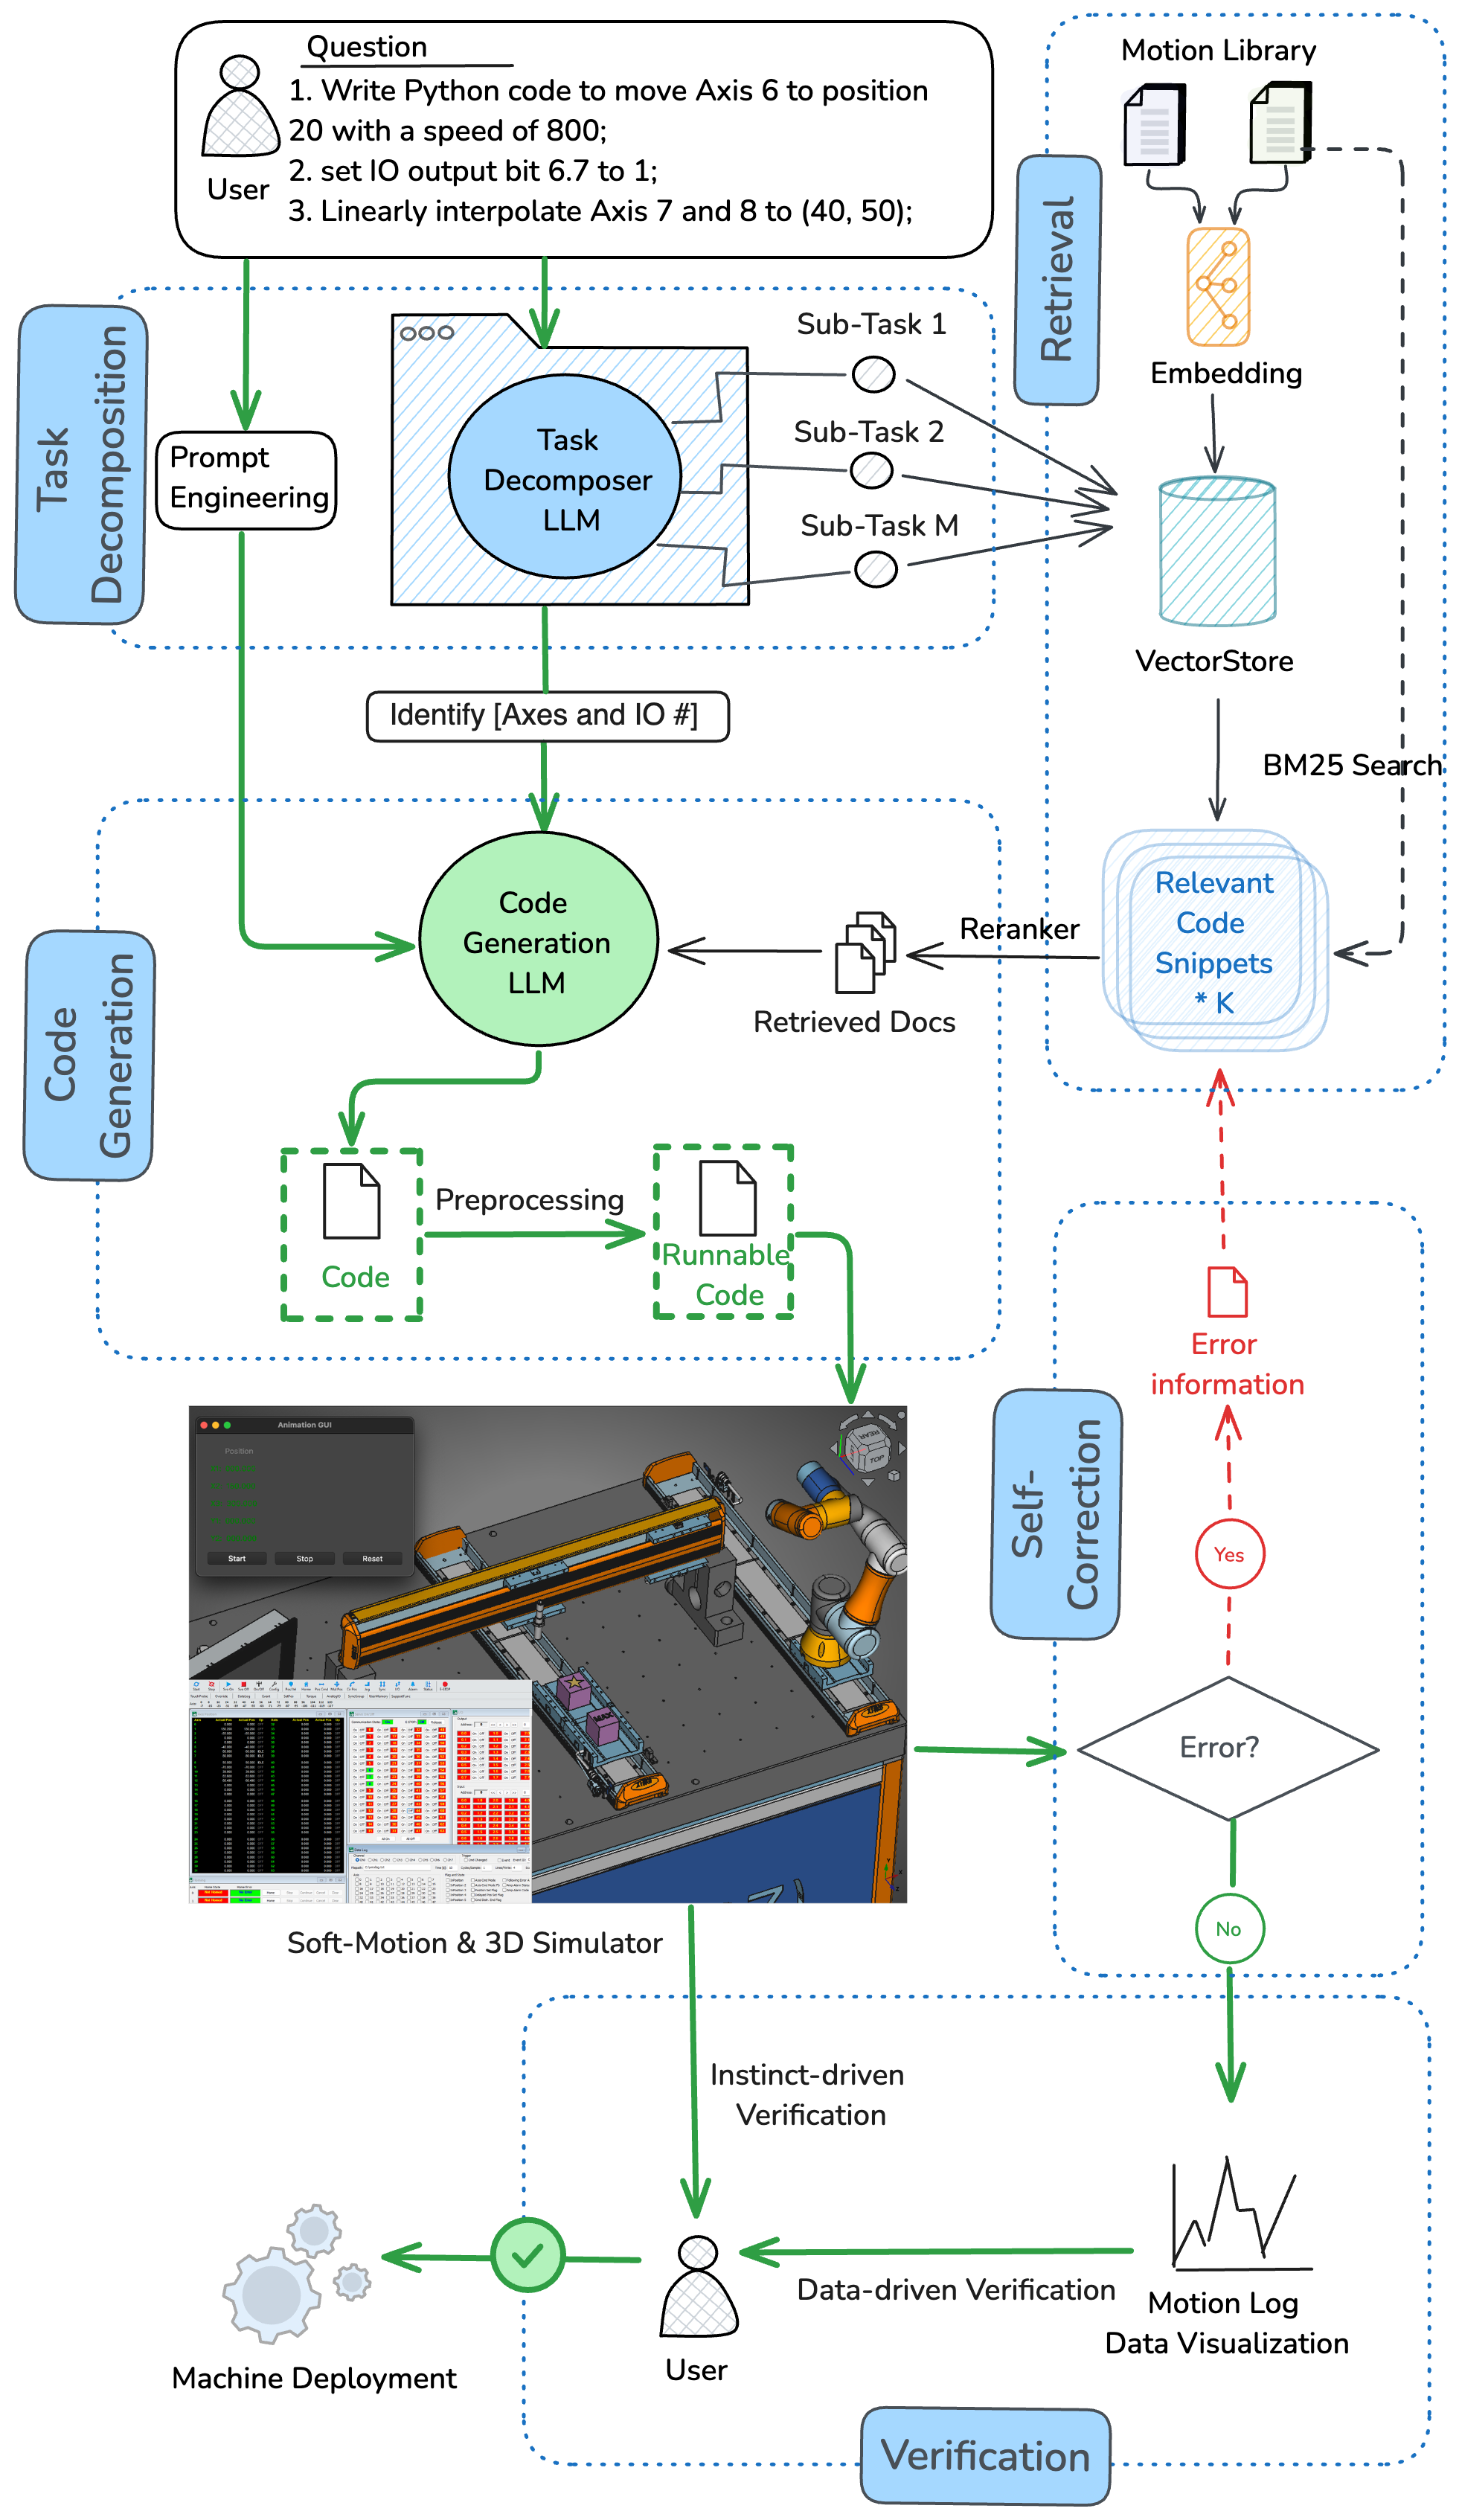
The diagram illustrates the proposed workflow; it does not establish a measured success rate for that particular three-operation request. The numerical evidence comes from the separate evaluation dataset.
The simulator records axis and I/O data at one-millisecond intervals. In the authors’ original example below, the same recorded movement appears as values over time and as two- and three-dimensional paths. The time plot helps reveal when movements occur; the spatial plots show the route between positions.

This gives an automation team a concrete way to challenge a result. Did the expected output change at the correct stage? Did the axes move together as intended? Does the path match the reference movement? An attractive animation can help someone spot a problem, but recorded values allow a requirement to become a repeatable check.
The plots show command-position traces. They should not be read as evidence that a real machine followed those commands perfectly under load, or that every possible collision and equipment fault has been ruled out.
The authors built MCEVAL, a collection of 186 motion-programming tasks, to test this workflow. Its three levels move from straightforward function calls to tricky argument choices and then to operations connected by events and dependencies. The hardest level includes requests in which one axis’s progress determines when another movement should begin. That is a more demanding problem than producing several unrelated calls in sequence.
There are 84 tasks at the first level, 56 at the second and 46 at the third. The comparison uses an Advanced RAG baseline that already retrieves documentation and examples, including reranking. MCCoder adds a more extensive workflow around generation and execution.
The evaluation compares generated programs with reference programs in two ways: whether their endpoints match, and how closely their recorded trajectories match using a time-series comparison called dynamic time warping. Both matter, but they answer different questions.
For GPT-4o in the reported experiment:
That last result matters. The workflow’s strongest endpoint improvement does not mean it improves every kind of task under every check. The complete results in Table III also show different outcomes across the four evaluated models.
| Model | Method | FTPR(MatchEndPoints) | FTPR(DTW) | |||||||
|---|---|---|---|---|---|---|---|---|---|---|
| OVERRALL | L1 | L2 | L3 | OVERRALL | L1 | L2 | L3 | |||
| gpt-4o | Advanced RAG | 52.69 | 70.24 | 46.43 | 28.26 | 63.98 | 84.52 | 55.36 | 36.96 | |
| MCCoder | 82.80 | 80.95 | 80.36 | 89.13 | 69.35 | 69.05 | 71.43 | 67.39 | ||
| o3-mini | Advanced RAG | 55.38 | 70.24 | 55.36 | 28.26 | 44.09 | 60.71 | 42.86 | 15.22 | |
| MCCoder | 72.58 | 80.95 | 76.79 | 52.17 | 60.75 | 71.43 | 67.86 | 32.61 | ||
| DeepSeek-V3 | Advanced RAG | 65.05 | 88.10 | 57.14 | 32.61 | 53.23 | 73.81 | 46.43 | 23.91 | |
| MCCoder | 81.72 | 89.29 | 75.00 | 76.09 | 65.59 | 72.62 | 64.29 | 54.35 | ||
| DeepSeek-R1 | Advanced RAG | 66.67 | 86.90 | 62.50 | 34.78 | 56.45 | 76.19 | 51.79 | 26.09 | |
| MCCoder | 79.03 | 90.48 | 71.43 | 67.39 | 66.13 | 78.57 | 58.93 | 52.17 | ||
The paper calls these first-time pass rates, while its system includes an internal correction loop. They should not be interpreted as a promise that the first uncorrected model response will work. There is also a reporting wrinkle: the paper describes trajectory checking as more stringent, yet some reported trajectory pass rates exceed endpoint rates. Read them as the two reported evaluation results, rather than as nested safety guarantees.
The practical conclusion survives those limits: a structured generation-and-verification workflow can materially improve performance in this tested environment, especially on some complex tasks. The experiment does not measure production downtime, engineering hours saved, or a reduction in machine incidents. Nor does it establish today’s best model for industrial control.
In the authors’ analysis of errors for GPT-4o, 76.3% of the categorized errors concern arguments. This is the share of the errors they analyzed, not the share of every generated program.
A program can call the right API while supplying an invalid or inappropriate parameter. The paper explains why informative controller messages help: an error that identifies an unavailable profile value and suggests the valid spelling gives the model a specific correction to make. A vague failure message provides much less help. This connects the quality of controller feedback directly to the usefulness of the repair loop, as described in the error analysis.
For a team preparing its documentation, that points toward a useful investment: keep function signatures, parameter constraints, examples and error explanations together. Adding more general documents will not necessarily resolve confusion between nearly identical function variants.
The paper describes a demonstration setup with motor stages, a collaborative robot and a PC running simulation and real-time motion software. Its validation is limited to Python and WMX3. It is evidence for this particular approach, not evidence that named manufacturers have deployed it throughout their factories.
A sensible first application is a recurring, well-understood motion-programming task for which engineers already have a reference implementation and a way to inspect execution. The value would come from reducing the work required to produce and correct an acceptable program. An unfamiliar machine or an operation without clear acceptance criteria is a much harder starting point.
For an event-triggered movement, an evaluation should retain more than the final positions. Keep the triggering condition, event order and relevant path constraints alongside the reference trace. Otherwise, a program could earn credit for arriving at the destination while failing the sequence the engineer requested.
The same principle appears in AI-generated SQL: successful execution is useful evidence, but the output still has to answer the intended task.
Use the paper’s architecture as an integration pattern. Separate the request, retrieved evidence, generated program, execution result and engineer’s decision. This makes a failure diagnosable: did retrieval select the wrong function variant, did generation misuse it, or did the test omit an important requirement? The study’s WMX3 simulator is a dependency of its experiment; another controller needs its own compatible execution and logging integration.
The authors link a MCCoder repository, but it was unavailable when checked for this revision. Teams should not plan an installation around that link without first confirming access to the implementation and its dependencies. The paper supplies an architectural starting point; it is not a verified installation guide.
Use an existing test runner for repeatable checks. For a Python-based evaluation, pytest’s parameterized tests can apply the same assertions to several sets of inputs and expected results. A team could use this to check exported simulation logs for the expected axis, endpoint and event order. Pytest supplies the test organization; the team still needs to define the motion-specific tolerances and obtain the traces from its controller. It is not a motion simulator or safety-certification tool.
A minimal evaluation can follow this path:
Keep the existing engineering release process for physical equipment. The research supports testing a better programming workflow; it does not justify letting a model decide that a machine is ready to run.
MCCoder’s strongest contribution is the connection between code generation and inspectable motion evidence. Its results make a credible case for evaluating that connection in a compatible environment, particularly where complex requests combine several dependent operations.
We would invest first in reference tasks, useful controller feedback and repeatable acceptance checks. Those assets remain valuable if the model changes. We would expand use only if the assisted workflow improves the complete engineering task—including review and correction—and preserves the checks needed for the actual machine. Stronger cross-library evaluation and field evidence would support a broader recommendation.
Yin Li and colleagues, MCCoder: Streamlining Motion Control with LLM-Assisted Code Generation and Rigorous Verification. This article uses arXiv version 3, dated 2 July 2025. Original figures and the results table are attributed to the paper’s authors.
Examine the numerical and behavioral checks behind AI-assisted legacy-code migration.
Check what changes as a trained model is exported and deployed on real hardware.
See why executable SQL still needs checks against the business question and intended metric.