A multi-agent swine-health pilot separates intake, diagnosis support and retrieval. See what its 32-question test shows and how to build safer handoffs.
Select a figure to open it at full size.
A farm-health assistant receives very different kinds of messages: a general question, a request for reference information, an incomplete observation or a description that needs veterinary assessment. Treating all of them as prompts for an immediate diagnosis is a poor software design.
Researchers at AXONS propose a more structured workflow in When Pigs Get Sick. Their system classifies the request, gathers additional information where appropriate, combines disease-specific model responses and retrieves relevant documents. For teams building veterinary software, the useful contribution is that separation of tasks. The evaluation is an early question-based pilot, not evidence that the system can independently diagnose animals or reduce outbreaks.
The system routes messages into four groups: general conversation, knowledge retrieval, symptom-based diagnosis and requests that need clarification. An ambiguous statement can therefore trigger a question before entering the diagnostic path. A factual request can go directly to retrieval without pretending that a diagnosis is necessary.
For symptom-based questions, the proposed intake moves through general information, visible signs and more specific symptom groups. It allows at most three user-system exchanges, with transitions depending on what has already been provided. If the user has no more information, the system proceeds with the collected record.
That limit keeps a conversation bounded, but it does not make the record complete. The software must preserve the difference between a sign that was reported absent and one that was never discussed. Otherwise a convenient summary can create apparent evidence that the user did not supply.
The original conversation diagram shows the route from a vague report, through clarification, to diagnostic discussion and document retrieval. It is valuable because it reveals the intermediate messages rather than presenting only a final accuracy number.

In that example, the user reports deaths and visible color changes. The bot’s summary also introduces respiratory symptoms, which are not present in the displayed earlier messages. The user then accepts the summary. The response later gives an awkwardly conflicting statement about whether one of the named diseases is unlikely or still possible.
The figure is not a documented clinical error rate, but it is a concrete design warning. Asking the user to confirm an AI-written summary is weaker than retaining a traceable record of each observation. A user may confirm the overall message without spotting an added detail. Downstream agents can then agree with one another while reasoning from the same faulty input.
The diagnostic component uses specialized agents for four diseases: African swine fever, porcine reproductive and respiratory syndrome, porcine epidemic diarrhea and foot-and-mouth disease. It combines their confidence scores using weights and applies a threshold to decide which candidates to retain. If no candidate qualifies, the framework has an out-of-distribution route for cases outside its supported set.
This is an aggregation design, not a demonstrated guarantee that confidence is calibrated. Several agents can share the same misconception, particularly if they depend on the same underlying model and summary. A high aggregate score should not be interpreted as the probability that an animal has a disease.
The retrieval component extracts relevant entities, rewrites the question using the conversation and domain information, and searches a vectorized document collection. The selected documents and their metadata accompany the generated response. The useful distinction is between identifying candidate explanations and answering a reference question with supporting material. Retrieved text can improve grounding, but its presence alone does not establish that the answer applied it correctly.
The original dataset table separates three different kinds of evaluation. This is essential to interpreting the headline results.
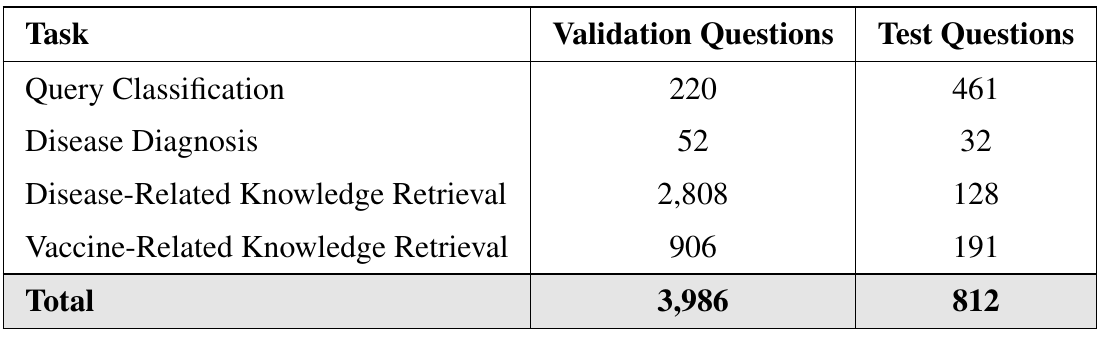
The routing evaluation contains 461 test questions, with 95.23% assigned to the correct request category. That assesses whether the system chooses the appropriate workflow. It is not diagnostic accuracy.
The diagnostic test contains 32 expert-curated questions. The paper counts an answer as correct when the reference diagnosis appears among the model’s top two predictions. GPT-4o’s reported 90.63% therefore corresponds to 29 of 32 questions meeting that top-two criterion. It does not mean 90.63% of animals received a single correct, clinically confirmed diagnosis.
The test includes just one case outside the four supported diseases. That is far too little evidence to establish dependable handling of unfamiliar conditions. The roughly 19-second reported response time also measures computation, not time to a verified veterinary conclusion. These distinctions come directly from the evaluation definitions and result tables.
For knowledge retrieval, the study reports better average answer-quality scores than its comparison system. The dimensions include relevance, coherence and correctness, using a zero-to-five scale. Those results concern responses to reference questions, not animal outcomes. The paper does not describe the evaluation personnel or judging procedure in enough detail to treat the scores as a clinical assessment.
The validation questions were AI-generated, while the test questions were curated by veterinary experts. That is a useful separation, but a curated question set still differs from incomplete, contradictory, multilingual conversations collected in practice.
The immediate opportunity is a structured assistant that helps a veterinary professional review the available information and find the relevant reference material. Before expanding diagnostic autonomy, test whether the system preserves what the user actually reported.
A proposed evaluation should include missing information, corrections to earlier statements, conflicting observations and cases outside the supported disease list. Check whether summaries introduce symptoms, whether a request for general information is mistaken for a diagnosis request, and whether source passages support the generated answer. Measure how much correction a professional needs to make, not only whether a reference label appears somewhere in a list.
For related work on maintaining context between specialized agents, see our analysis of multi-agent systems. More agents increase the importance of a reliable shared record.
A conventional state machine is sufficient to represent the paper’s routing and intake stages. Store reported observations, explicitly unknown fields and their originating messages separately from model suggestions. This makes it possible to inspect a handoff without depending on a generated paragraph as the sole record.
If the application needs a resumable model workflow, LangGraph interrupts provide a mechanism for pausing execution and collecting a human decision before continuing. That supplies workflow control; it does not validate medical content. A simpler application-level review queue can serve the same purpose when the process is small.
Begin with a narrow, professionally maintained reference collection. Return the actual supporting passages alongside the draft response and preserve their versions. Compare this assistant with the existing search-and-review process on held-out questions and later conversations. Keep diagnosis and action decisions with veterinary professionals while measuring whether the system improves information quality and review effort.
The paper is most useful as a prototype for organizing a complicated conversation. It shows how routing, structured intake, specialist model outputs and retrieval can be assembled, and it provides enough intermediate detail to see where errors can enter.
The diagnostic sample is too small and too constrained to justify broad claims of clinical reliability or economic benefit. The next credible milestone is stronger evaluation of intake fidelity, unfamiliar cases and professional review—not a larger headline percentage from the same small test.
When Pigs Get Sick: Multi-Agent AI for Swine Disease Detection, Tittaya Mairittha, Tanakon Sawanglok, Panuwit Raden and Sorrawit Treesuk, AXONS. Version 1, March 19, 2025. Figure 1 and Table 1 are reproduced from the original paper for analysis.
Explore how confidence scores can support escalation or abstention instead of automatic acceptance.
Explore coordination, ownership and recovery when several agents contribute to one workflow.





