Compare an LLM-led traffic incident assistant with a hybrid planner: original research diagrams, consistency results and a practical evaluation framework.
Select a figure to open it at full size.
An incident report arrives in a highway control room. The operator needs to understand what has happened, identify the applicable procedure and coordinate a response. A conversational assistant could make that information easier to use. The harder question is who—or what—should choose the actions it recommends.
For transport technology leaders, that is the useful question in research by Matteo Cercola and colleagues at Politecnico di Milano and MOVYON. They compare an LLM that generates recommendations using retrieved information with a hybrid system that assigns the planning to a separate algorithm.
The hybrid produces more stable recommendations when incident descriptions change in ways that should not change the response. The LLM-led approach, however, compares favorably with the procedure manual on another test. Those findings support a more specific conclusion than “AI can automate traffic management”: the component that explains a recommendation does not necessarily need to be the component that selects it.
In the hybrid pipeline, the first LLM translates an operator’s description into structured incident features. A planning system uses those features to select a sequence of actions. A second LLM turns that sequence into readable guidance for the operator.
The language models make the interface conversational, but the planning system determines the proposed response. That division gives the team separate things to inspect: whether the description was understood, whether the selected plan fits the incident, and whether the final explanation preserves that plan.
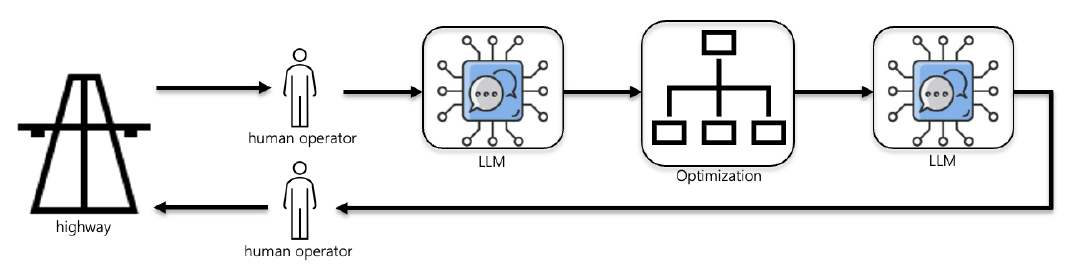
This is an architectural boundary, not a safety guarantee. A planner can produce the best answer for an incorrectly understood incident. An explanation can also alter an otherwise valid recommendation. Both translation steps still need checking.
The planner starts with thousands of historical event-management reports from Autostrade per l’Italia. Each report becomes a path: an incident has a recorded state, an action is taken, and the event moves to another state. States describe features such as event type, vehicles involved, location and time. Actions include steps such as contacting police or closing a lane.
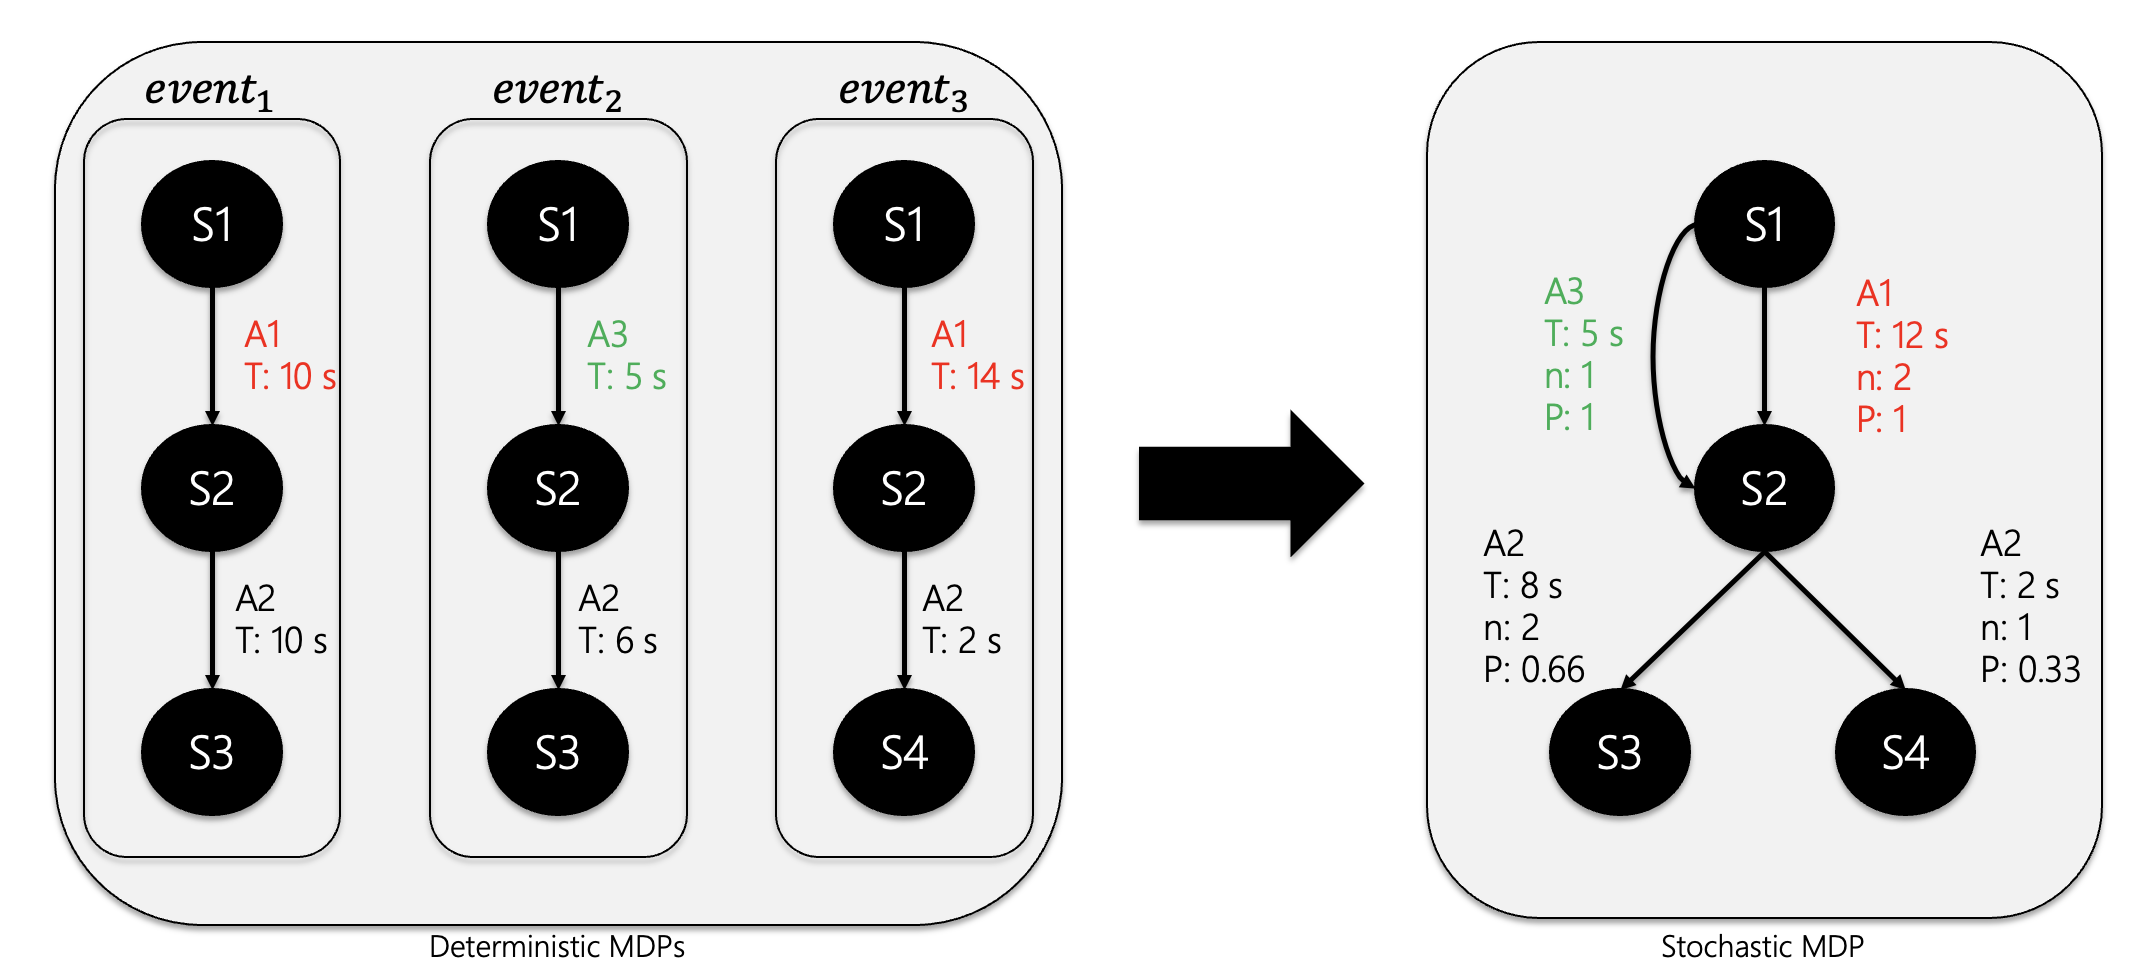
The researchers merge matching states across reports. Instead of retaining only separate stories about individual incidents, they build a shared graph that records which actions followed which circumstances, how long those actions took and which states came next.
The paper’s small worked diagram makes this concrete. Two historical paths use action A1 to move from S1 to S2, taking 10 and 14 seconds. In the merged graph, that transition carries a count of two and an average time of 12 seconds. From S2, action A2 ends at S3 twice and S4 once, producing approximate transition probabilities of two-thirds and one-third. These are illustrative numbers in the researchers’ diagram, not measured averages for a named traffic procedure.
The planner then works backward from resolved incidents to estimate the cost of reaching a resolution. Its method, Improved Prioritized Sweeping, focuses updates on states where a changed estimate could affect earlier choices. The point is to select a useful sequence, rather than simply choose whichever next action looks fastest.
Its cost also reflects familiarity. The cost formula combines action time with a penalty that becomes smaller when an action has occurred more often in that state. This makes rare choices less attractive, all else equal. That may favor established practice, but frequently recorded behavior is not automatically the correct response under today’s procedures.
A new incident is unlikely to match a historical state perfectly. The system therefore looks for the nearest state using weighted differences between features. The paper gives an intuitive example: whether somebody is injured should matter more to an ambulance decision than a small difference in road location. It derives feature weights from patterns in groups of reports sharing the same resolution sequence.
This matching step deserves as much scrutiny as the planner. If it treats two meaningfully different incidents as similar, a well-computed plan can still be inappropriate. The authors themselves identify better similarity methods and reducing graph complexity as areas for further work.
The Full LLM system uses GPT-4o mini to generate the response. It receives the current incident description, similar historical cases and relevant passages from a 600-page procedure manual.
For the historical cases, retrieval matches the new description to stored descriptions. Each retrieved case brings its associated actions and resolution time with it. That distinction matters: the system retrieves cases because their descriptions are similar, rather than directly searching for the most successful response.
For the manual, the researchers first divide the document by its index, then use semantic chunking to split sections into passages that belong together in meaning. Retrieval selects relevant passages for the prompt. The model uses the combined material to recommend actions and generate estimates of resolution time and the likelihood of a subsequent event.
This approach can draw directly on written procedures that the hybrid planner does not itself ingest. But the researchers did not explicitly tell it whether to prioritize the manual or historical precedent when they point in different directions. That is a consequential policy choice to leave implicit.
Both architectures also produce forecasts. The paper’s reported evaluation concentrates on action recommendations; it does not establish that those resolution-time or subsequent-event estimates are accurate enough to guide live operations.
The researchers split the historical dataset into 80% for building the systems and 20% held out. The hybrid uses the first portion to construct its graph; the Full LLM system makes that portion available through retrieval. This is not a claim that they retrained the language model on those reports.
They evaluate vehicle breakdowns, collisions and a third group of other events. For each group, they use 50 events from the construction portion and 50 held-out events: 300 evaluation inputs across the two portions and three categories. The two tests ask different questions.
The first test compares the meaning of recommended actions with actions specified in the procedure manual. It uses text embeddings to measure similarity, adjusted against a random-text baseline. Crucially, it chooses the best matching order of actions when scoring them: this test does not check that actions are proposed in the correct sequence.
The original chart shows the distribution of scores. The Full LLM’s median—the line inside each orange box—is higher than the hybrid’s in all three held-out event groups. It would therefore be misleading to say that the hybrid outperforms the LLM-led system on every measure.
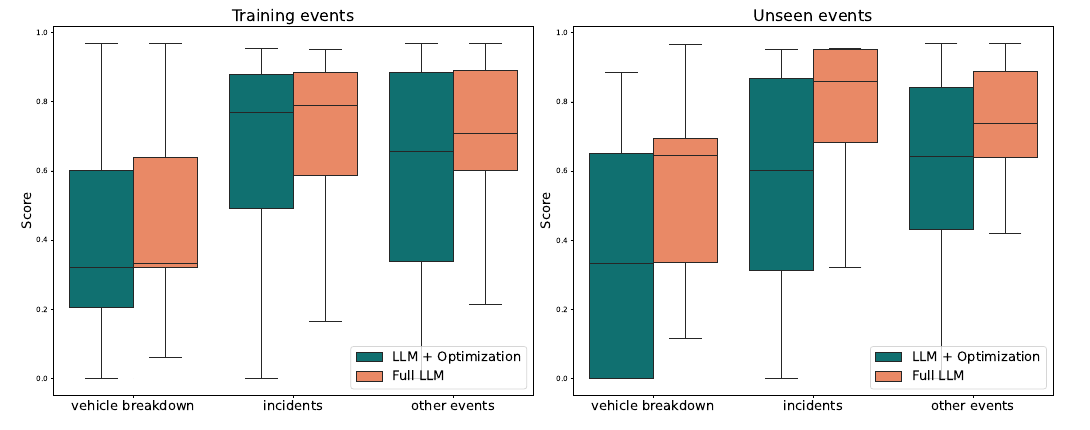
There is an important asymmetry: the Full LLM can retrieve the same manual used as the reference for scoring, whereas the hybrid relies on historical practice. The result compares those complete systems, not two decision engines supplied with identical knowledge.
Vehicle breakdowns also reveal a mismatch between a general procedure and a specific situation. A stopped vehicle may restart without operator intervention. A recommendation to take no action can then receive a low score because it differs from the manual’s general action list. A lower score needs examination; it does not by itself prove that an operator should have intervened.
For an evaluation team, the lesson is to review disagreements with domain experts. Simply maximizing textual agreement with a manual can hide both reasonable exceptions and unsafe omissions.
The second test makes small changes to event features while keeping the expected management response unchanged. The researchers then measure how consistently each system preserves its actions.
Here the hybrid has a large advantage across the familiar and held-out groups. In the held-out collision group, for example, the chart shows roughly 84% consistency for the hybrid versus roughly 10% for the Full LLM. These are approximate readings from the plotted bars. They measure stability under this test’s changes, not accident prevention or operational safety.
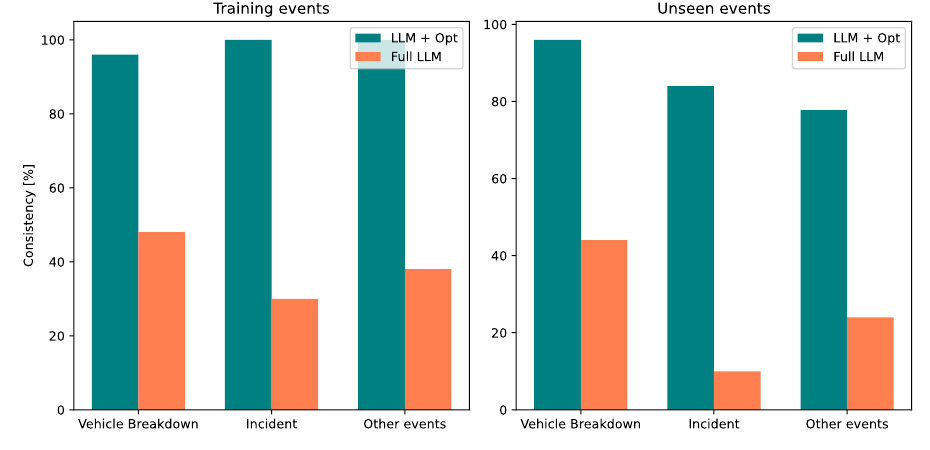
A consistent system can repeatedly choose the wrong action. Conversely, a system should change its response when an important fact changes. The useful target is to preserve decisions when changes are irrelevant and revise them when the situation requires it.
The paper provides evidence for comparing these architectures offline. It does not report a live control-room trial demonstrating fewer secondary accidents, shorter congestion or faster incident resolution. Its consistency findings justify further evaluation of the hybrid; they do not authorize autonomous dispatch.
For a highway operator considering this design, start with one well-defined incident family and a set of reviewed historical cases. The first product should help an operator inspect a recommendation, not silently execute it.
Use the paper’s architecture to separate the evaluation into four questions:
For example, in an evaluation case built around a disabled vehicle, an operator can inspect which historical state the system matched and which facts drove that match. If an amended report introduces a materially different condition, the interface should require a fresh review rather than continue displaying the earlier plan as if nothing changed. The approved local procedure determines the response; this illustration specifies a software test, not roadside instructions.
Compare the assistant with the existing procedure lookup process. Track time to an approved recommendation, corrections needed, unsupported actions and cases where the system should decline to recommend. Faster generation is not useful if it creates more verification work.
Keep evaluation cases separate from the records used to build the graph or retrieve examples. A time-based holdout and a second operating area would help test questions this paper leaves open: performance after procedures change and performance beyond familiar locations. These are proposed follow-up tests, not results from the study.
The research describes a system design, not a ready-to-install traffic-management package. An existing application can implement the initial workflow with a structured incident form, a versioned planning service and an operator approval screen. Add frameworks where they solve a specific implementation problem.
LlamaIndex can help prepare and retrieve the procedural evidence. Its Semantic Chunker groups sentences using semantic similarity. For the paper’s manual-based approach, start with one reviewed procedure section, retain its section identity and version, and check whether retrieval returns the complete relevant passage. Compare semantic splitting with simpler section-based chunks before adopting it. Good segmentation does not settle conflicts between a current procedure and an old incident record.
LangGraph can organize a workflow that pauses for review. Its interrupt mechanism supports pausing execution, persisting state and resuming after external input. It requires persistence and a thread identifier to resume the appropriate workflow. In this application, an interrupt could present extracted facts, retrieved evidence and the proposed plan for an operator’s decision. Approval should attach to a particular incident and plan version; changed facts should trigger another review. LangGraph supplies orchestration, not a certified traffic decision policy.
These components can complement each other: retrieval supplies evidence, while workflow control manages when a recommendation advances. Neither replaces the planner, domain validation or the agency’s existing authority to act. The first evaluation can remain a read-only assistant with no connection to dispatch or road-control commands.
For the broader distinction between recommendations and systems that act, see what changes when an LLM becomes an agent. The SagaLLM research explores a related question: how a plan stays connected to changing state.
The strongest contribution is the comparison between two places to put decision authority. An LLM can make complex operational information easier to access without owning the entire decision process. The hybrid’s consistency advantage makes that separation worth evaluating.
But the manual-alignment results prevent an easy victory claim. Historical actions and written procedures offer different kinds of evidence, and either can be incomplete for the current incident. A useful product makes those differences visible and gives the operator a clear way to resolve them.
We would expand use when the assistant reduces the effort needed to reach an approved response while maintaining action correctness, sequence and appropriate sensitivity to new facts. Better field evidence, independent evaluation and stronger checks on state matching could change that recommendation. Fluent explanations alone would not.
Automating the loop in traffic incident management on highway — Matteo Cercola, Nicola Gatti, Pedro Huertas Leyva, Benedetto Carambia and Simone Formentin. arXiv version 1, March 15, 2025. Read the full PDF. Original figures reproduced under CC BY 4.0; surrounding explanations and recommendations are TechClarity’s analysis.
Follow the steps from aerial detections to usable vehicle trajectories.
Separate language-based mission planning from perception, navigation and flight control.
Extend safety testing to the memory, tools and actions surrounding an AI model.





