Can an HVAC controller reuse experience when its controls change? A look at the simulation results, transfer mechanism and deployment limits.
Figures open at full size. Wide tables scroll sideways.
A building controller that learns a useful policy faces a practical problem when its controls change. Give it access to additional equipment, then return it to the earlier configuration: does it benefit from prior experience, or start learning again?
Continual Reinforcement Learning for HVAC Systems Control investigates that problem in a building simulator. Its central idea is to preserve a learned model of how the environment responds, then use that model to help train a controller under different control configurations.
The distinction matters. This is research into learning efficiency and retained knowledge. It is not evidence that a deployed building will save a stated percentage of energy, or that a controller improves automatically every hour it operates.
The study uses BOPTEST’s hydronic heat-pump environment and a sequence of three tasks. First, the controller chooses the heat-pump modulation signal while two other controls retain the simulator’s defaults. Next, it controls all three: the modulation signal, evaporator fan and emission-circuit pump. Finally, it returns to the first task’s one-control arrangement.
That one → three → one sequence creates the test. Learning the second arrangement should not destroy everything useful about the first. The authors compare a model-free reinforcement-learning approach with a model-based approach that generates additional training experience from a learned environment model.
Importantly, the Soft Actor-Critic controller is trained from scratch at each stage. The component carried forward is the environment-model machinery. Readers should therefore interpret the result as transfer through that model, rather than a single control policy seamlessly adapting across buildings.
A reinforcement-learning controller needs examples connecting a condition and action to what happens next. In this study, those examples include the state of the room, the selected control settings, the next state and a reward related to thermal discomfort.
The model-based system trains a predictor to estimate the next temperature and reward from the current state and actions. It then generates one-step synthetic experiences and mixes them with experiences from the simulator to train the controller. More useful training examples can become available without obtaining every one through a fresh simulator interaction.
The unusual part is how the predictor is created. A hypernetwork generates the parameters of another network, conditioned on the task and layer. One generated target network predicts the next state; another predicts reward. The hypernetwork learns from observed transitions. A regularization term discourages it from changing previously learned task parameters too much while learning a new task.
That is the proposed defense against forgetting: make the new learning respect the earlier task’s model, while allowing the current one to improve.
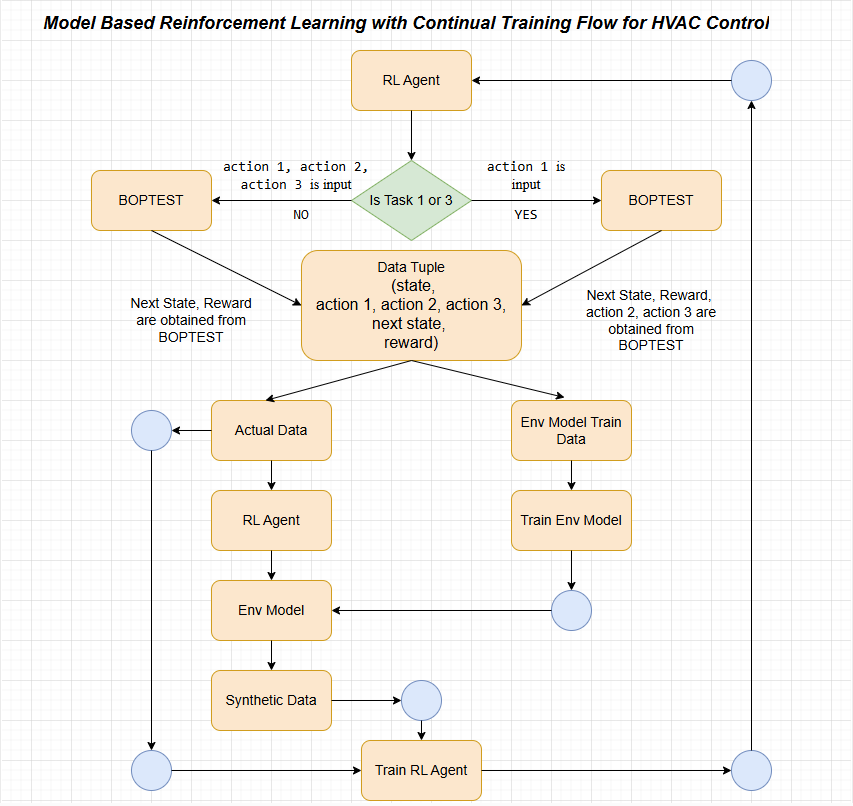
The diagram also reveals the dependency that can make this approach fail. If the environment model predicts the wrong consequences, the controller practices on misleading examples. Generating more synthetic data then reinforces a poor model of the building. The paper explicitly identifies prediction bias and training instability as concerns.
The researchers evaluate the stages using January and April test periods. When the system returns to the one-control task, the model-based approach improves earlier in training than the model-free comparison. The original April chart makes the shape of that advantage visible.
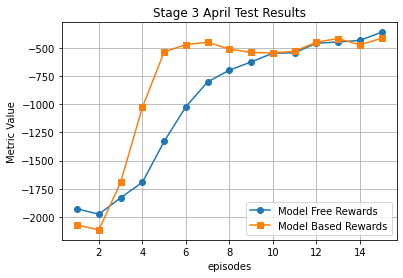
The authors describe rapid convergence after returning to the earlier task. The useful operational reading is narrower: retained environment knowledge can reduce the early learning burden in this simulated sequence. The plotted later performance does not show an equally large, permanent advantage at every episode.
There is also counterevidence to a smooth-learning story. In the second task’s April plot, the model-based reward worsens again near the end after an extended period of improvement.
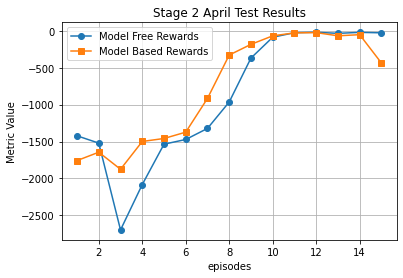
A team considering the method needs to establish both faster learning and acceptable stability. These plots do not quantify electricity savings, uncertainty across many buildings or the risk of comfort violations in an occupied facility. The paper names testing beyond BOPTEST and more complex multi-zone settings as future work.
The promising application is reuse when a control arrangement changes: an equipment upgrade, a newly exposed actuator or a return to a restricted mode. A learned description of thermal response might still contain useful information even though the controller’s available actions differ.
The research supports investigating that proposition. It does not establish that a model trained for one building transfers safely to an unrelated building with different thermal behavior. Even within one building, changed occupancy, sensors or equipment faults may make earlier experience less representative.
A useful pilot would first replay the paper’s control-change sequence in simulation. Compare against a model-free controller and the existing rule-based control strategy. Track thermal comfort and energy use separately, alongside learning speed and variation across repeated runs. A reward curve is only useful to an operator when its improvement corresponds to outcomes the operator actually values.
BOPTEST is the starting environment for a reproducible evaluation. The official project provides building emulation test cases for controller benchmarking. Begin with a case close enough to your control problem that the observations and actions have meaningful counterparts. Confirm units, control intervals, actuator bounds and baseline behavior before comparing learning algorithms.
The authors’ repository is a research reference. Their HVAC continual-learning repository contains the study’s implementation material, but its current notice describes the code as available for inspection and restricts reuse. It should not be presented as a ready-to-deploy open-source controller. Inspect the algorithm and experiment setup when assessing reproducibility; obtain appropriate rights before using that code.
Existing building controls remain the deployment baseline and fallback. Before any live trial, a controls engineer should define permitted actions, comfort limits and fallback behavior independently of the learned reward. Start by observing recommendations without allowing them to control equipment. Investigate disagreements with the existing controller and reject configurations that only improve a combined score by worsening an unacceptable comfort or equipment outcome.
The first deliverable should be a controlled comparison of behavior, not a new controller connected directly to an occupied building. Our analysis of federated predictive maintenance addresses a different industrial-learning challenge: learning across sites whose raw histories cannot be pooled.
The worthwhile idea is preserving useful environment knowledge when the control task changes. The study supplies a concrete mechanism and an encouraging simulated learning pattern, alongside visible instability.
That is enough to justify a reproducibility exercise for a team with building-control expertise. It is not enough to price an energy-saving commitment or replace a dependable control strategy. The next evidence that would change that judgment is stable performance across repeated runs, realistic operating variation and a supervised real-building evaluation with comfort and energy reported separately.
Continual Reinforcement Learning for HVAC Systems Control: Integrating Hypernetworks and Transfer Learning, Gautham Udayakumar Bekal, Ahmed Ghareeb and Ashish Pujari. arXiv version 1, submitted 24 March 2025. Figures are the original training-loop and experimental plots from that version.
Check what changes as a trained model is exported and deployed on real hardware.
Measure the workload and energy used before making an AI sustainability claim.





