How XR-Objects connects AI answers to physical items. Explore its original diagrams, small user study and a practical path to testing object-based interfaces.
Select a figure to open it at full size.
A camera-enabled chatbot can answer a question about a bottle. Comparing several bottles is harder: the user must repeatedly explain which object they mean, preserve context and connect the answer back to the right item.
XR-Objects explores an alternative interface. Each visible object gets its own anchored menu and conversation, while a comparison function can reason across several selected objects. The physical objects remain ordinary objects; they do not need embedded electronics or special markers.
For product teams building camera-based assistance, this research asks a useful question: how much friction comes from identifying and referring to things, rather than from generating an answer?
Dogan and colleagues’ prototype combines object detection, depth information and a multimodal language model. The components perform different jobs.
First, a local detector identifies an object category and its bounding box. In the paper’s example, it detects a bottle. A crop of the image then provides a multimodal model with the detail needed to identify it more specifically as soy sauce and generate associated information and actions.
Separately, ARCore supplies camera pose and depth information. The system projects the detected object into the scene so the menu appears attached to that physical location. The language model supplies meaning; the augmented-reality system supplies spatial placement.
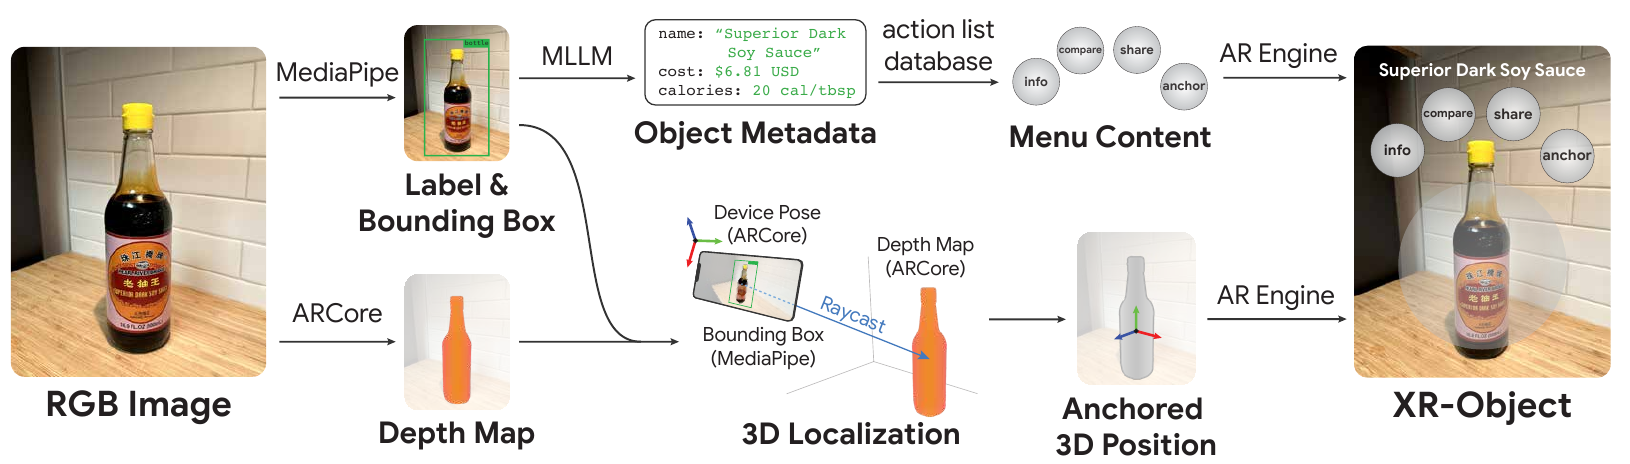
That division matters for debugging. A correct answer attached to the wrong bottle is still a failed interaction. Improving language-model accuracy alone would not fix it.
The historical phone prototype used MediaPipe detection, ARCore and a cloud model. The paper reports roughly 31 frames per second for detection on a Galaxy S21 and about three seconds for cloud queries. Continuous visual tracking and occasional AI answers therefore operate at very different speeds. Those measurements describe the prototype, not a current service guarantee.
The system maintains an object-specific image and conversation history. A follow-up question can refer to the item already under discussion rather than forcing the user to describe it again.
For comparisons, the selected object crops are combined into one image with identifiable positions. The model receives that combined visual context and the user’s question. After producing an answer, a further query identifies which object indices the answer refers to, allowing the interface to highlight the relevant physical objects.
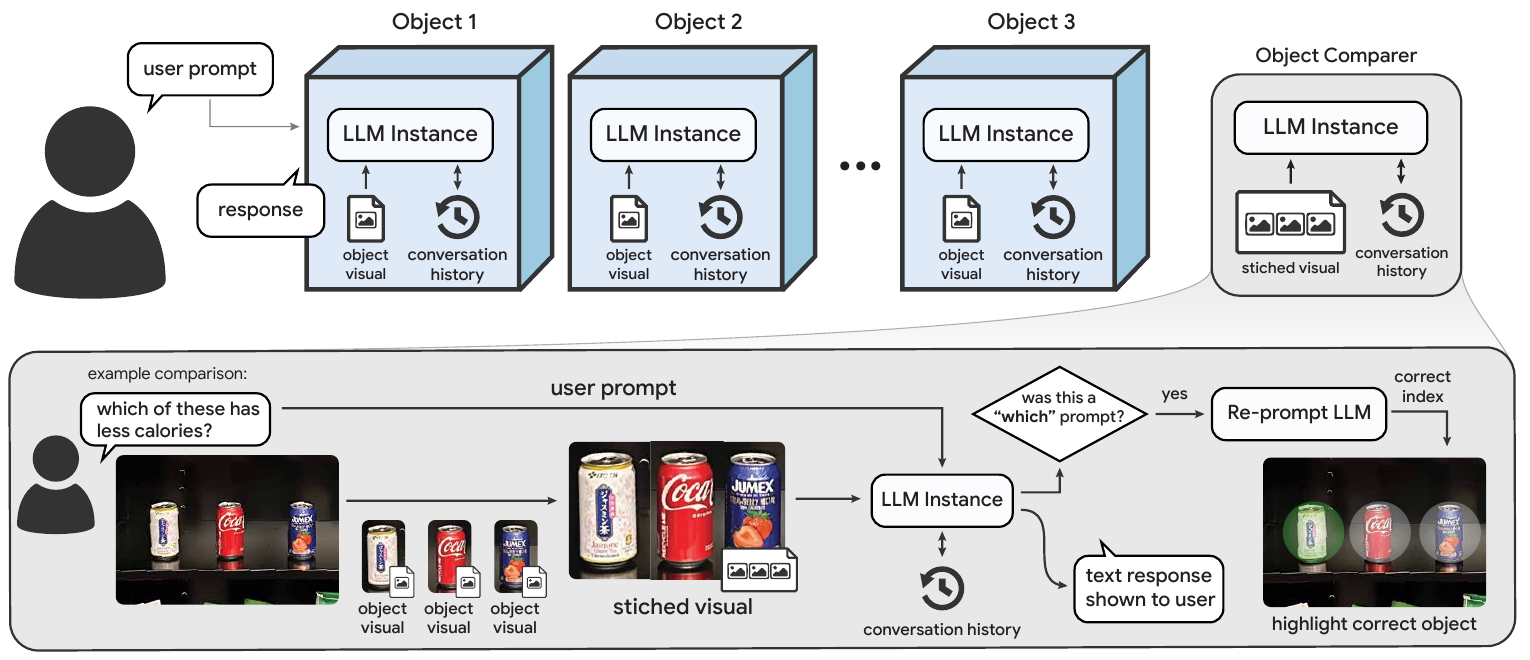
The example asks which drink has fewer calories. The important interaction is not simply producing a product fact. It is preserving the connection between the comparison, the answer and the correct container.
This also identifies two failure points for a product team. The model may misread or infer nutritional information, and the system may highlight the wrong item after answering. A usable comparison needs both content verification and correct object selection. The diagram’s separate “LLM instances” describe object-specific interaction contexts; they do not mean each bottle contains a separately trained model.
The researchers compared their phone interface with a chatbot on tasks including object comparisons and other object-related actions. Eight people were recruited; the paired completion-time analysis contains six participants with complete timing observations.
Across the task set, mean completion time was 217.5 seconds with XR-Objects versus 286.3 seconds with the chatbot—about 24% less time relative to the chatbot mean. The original plot makes the small sample visible rather than hiding it behind an average:
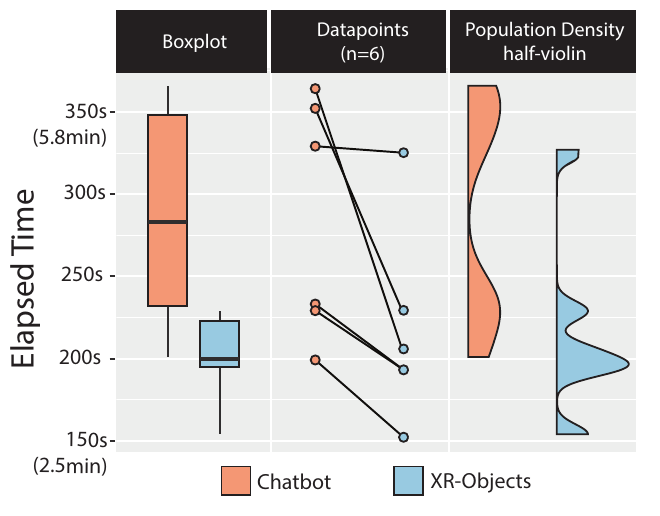
The questionnaire results did not show statistically significant differences on the reported HALIE factors. Faster completion therefore should not be translated into a demonstrated improvement on every dimension of user experience.
The paper also discusses headset use and collects preferences about it. Those responses concern an imagined headset experience, not a trial in which participants performed these tasks wearing a headset. Similarly, the wider household, shopping and assistance scenarios illustrate design possibilities; they are not all validated deployments.
The evidence supports a narrower and useful conclusion: anchoring questions and answers to objects can reduce interaction overhead on this kind of task. It leaves open how well the approach handles crowded scenes, object movement, unreliable labels and repeated everyday use.
A sensible first product experiment would focus on one setting where users currently spend time identifying objects—for example, comparing a small group of clearly labeled products. Keep the interaction read-only while testing whether users can reliably select the intended items and understand which one the answer describes.
Compare against a straightforward camera-chat baseline using the same information and questions. Measure task completion, wrong-object selections, incorrect comparisons and time spent correcting the system. A visually impressive interface that requires repeated re-selection may erase the benefit observed in the paper.
Treat the data source as part of the design. If the answer depends on an exact specification, connect the recognized object to verified product data rather than assuming the image model’s response is authoritative. Provide a way for the user to correct the identity before receiving a consequential comparison.
The official XR-Objects repository provides a Unity/Android starting point built around ARCore and MediaPipe, with Gemini integration in the current repository. That current implementation should be distinguished from the paper’s historical model configuration.
Start by bringing up its object detection and scene anchoring on a supported device, then add a single-object question flow. Only add cross-object comparison after identity, tracking and response association work reliably. Review the handling of camera data and credentials before adapting the prototype into a distributed app.
The design also illustrates a broader agent-architecture principle: perception, stored context and action each need their own checks. A capable model does not automatically make the surrounding interaction reliable.
XR-Objects is most persuasive as research into the interface around AI. It shows how maintaining a physical reference can make assistance easier to use, and gives enough implementation detail to test that proposition.
The next useful experiment is repeated use in one constrained environment, with verified object identity and answer quality. If those conditions hold and correction effort stays low, the interface has earned consideration. The small phone study alone does not justify a general claim that every physical object should become an AI assistant.
Augmented Object Intelligence with XR-Objects, Dogan and colleagues. Version 5, May 16, 2025; UIST 2024 research. Original Figures 4, 5 and 14 are reproduced above for discussion of the mechanism and study.
Test whether a model’s reasoning remains grounded in the image it is explaining.
Consider the accuracy and latency tradeoff in identifying objects from 3D data.





