MotionScript grounds text-to-motion training in measured joint movement. See how its captions work, what the studies show and how animation teams can test it.
Select a figure to open it at full size.
“Wave enthusiastically” sounds like a clear animation instruction until someone has to produce it. Which arm moves? How far? How quickly? Does the body turn first, and do the hands move together? A short action label leaves much of the performance unspecified.
MotionScript investigates a way to connect language to those physical details. It converts recorded 3D joint movements into structured descriptions, then uses those descriptions to enrich the training data for a text-to-motion model. At generation time, a language model can expand an unfamiliar acting prompt into a similar description before the motion model attempts it.
For teams building virtual characters, animation tools and simulated humans, the contribution is a more grounded intermediate representation. It is not a system that eliminates motion-capture data or turns arbitrary instructions into safe robot behavior.
An ordinary caption may describe a clip as a person greeting someone. That expresses intent, but says little about the joint movements. Asking an LLM to embellish the caption can add detail that the recorded motion never performed.
MotionScript works in the other direction first. It measures the skeleton sequence, identifies changes in pose and converts those changes into language. The detail therefore originates in the motion being labeled, rather than in an imagined performance.
The distinction matters during training. A text-to-motion model learns from pairs of descriptions and motions. If the descriptions repeatedly invent gestures absent from their paired recordings, richer text can become noisier supervision. The authors’ proposition is that descriptions grounded in the actual sequence give the model a more useful vocabulary for composing unfamiliar actions.
The method starts with normalized 3D joint coordinates. For each frame, rules convert measurements into pose categories: an elbow might be straight or bent, hands might be close or far apart, and the body might be turned relative to its starting orientation.
The system then follows those categories over time. A run of changes in one direction becomes a motion segment—for example, an elbow progressively bending. Each segment records when it happens, how much the relationship changes and how quickly it changes.
Small or uninformative changes are filtered. Related movements can be combined: matching changes at the left and right elbows can become a description of both elbows. Events happening together can be expressed as simultaneous; consecutive events can be described in order. Templates turn these structured observations into sentences.
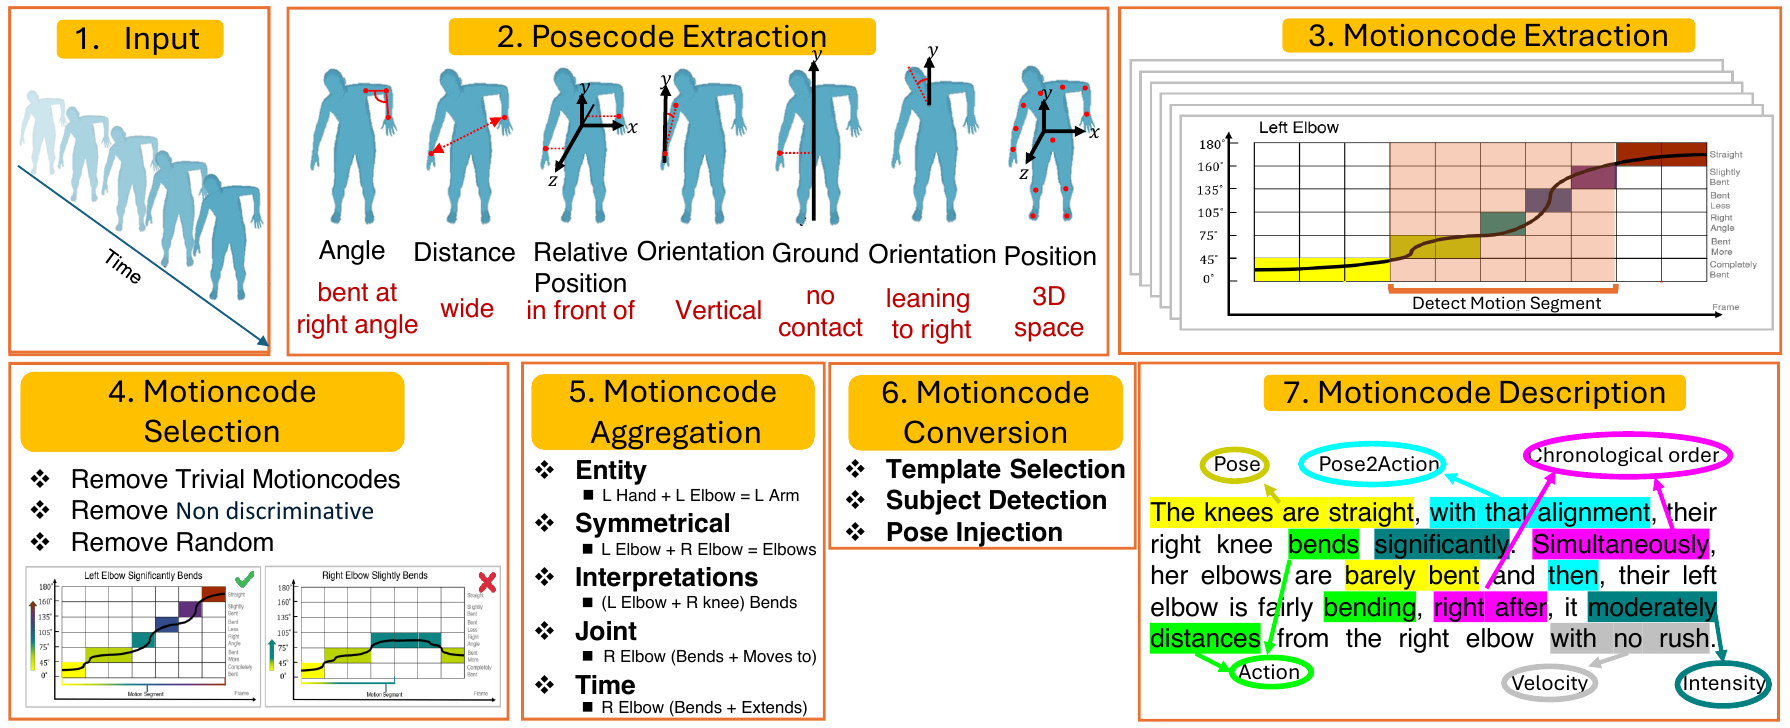
This is a rule-based captioning method. The trained motion generator is a separate component. Keeping those roles distinct explains why MotionScript can generate descriptions without training a captioning model while still depending on training data to synthesize motion.
The original example below follows several overlapping actions. The person turns counterclockwise while the left elbow bends. Later, that elbow extends, the hands move farther apart, and the person travels to the right.
The colored timelines show why the temporal representation matters. “Turns and moves arms” would lose both the elbow’s change of direction and the overlap between actions. MotionScript retains those relationships in a description the motion model can learn from.
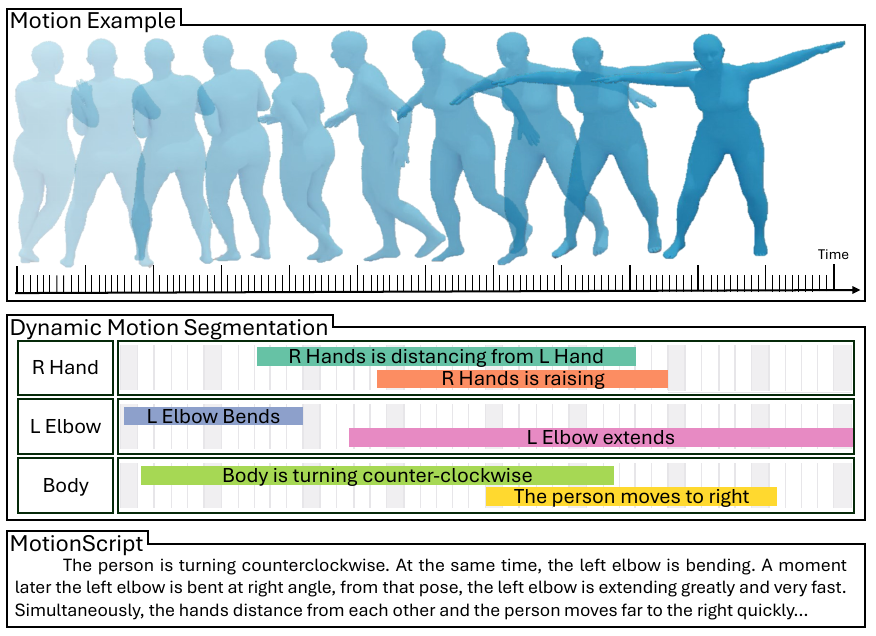
The representation also compresses information. Filtering insignificant changes and combining events makes the caption more manageable, but can discard subtle movement. A character animator may care about a small hesitation that a general-purpose captioning rule treats as unimportant. The selection rules therefore belong in the evaluation, not just in preprocessing that nobody examines.
The researchers augment HumanML3D training data with MotionScript captions and train a T2M-GPT-based motion generator. They then ask a language model to translate more unusual prompts into descriptions resembling that training language.
One example is a person pretending to be an eagle. The high-level concept is outside the usual short action labels. The language model supplies a more detailed movement description; the motion model attempts the corresponding sequence using patterns learned from grounded captions.
This is a two-stage bridge. The LLM contributes an interpretation of the requested performance, while the motion model supplies the learned mapping from movement descriptions to skeleton motion. Success requires both stages to agree. A detailed but inappropriate interpretation can still generate the wrong performance, and a sensible interpretation can still exceed the generator’s learned capabilities.
The same separation appears in language-guided drone planning: expressing a task in language and carrying it out are distinct problems. For MotionScript, the result is a character-motion sequence, not a verified physical controller.
The paper evaluates unfamiliar prompts derived from mime and improvisation exercises. These include situations such as fighting sleep during a lecture or reacting when shower water turns cold. Because there may be no single correct recorded motion for such a prompt, the researchers use human judgments of how well generated clips match the requested action.
The first study has 23 participants evaluating 20 prompts. A second has 30 participants evaluating 34 prompts and compares MotionScript-based augmentation with descriptions expanded by an LLM. The authors report a preference for the MotionScript-based approach, with the per-prompt ratings showing that the advantage is not uniform.
There are reporting inconsistencies in the selected version’s aggregate counts and condition labels, so the paper does not support a clean, precise percentage improvement we would use for a product forecast. The useful conclusion is narrower: the tested representation produced promising preference results on a small, curated set of unfamiliar prompts. It still needs replication and evaluation on the actions your users request.
The study does not establish that generated motion meets an animator’s production constraints, preserves contact with every object, or is physically executable by a robot. Perceived agreement with a prompt and physical validity are different acceptance criteria.
An animation-tool team could start with a library of short motions it already owns and understands. Generate MotionScript descriptions, then ask an animator to compare each description with the actual clip. Check left/right identity, timing, direction, contact and omitted movements before training a generator on the captions.
Next, test a small set of actions absent from the training labels. Compare the same underlying motion model with ordinary captions, LLM-expanded captions and grounded captions. Keep the requested actions and review conditions fixed so extra detail is not confused with a change in the task.
Collect two kinds of feedback. Ask whether the motion communicates the intended action, and separately ask whether it is usable: foot sliding, self-intersection, timing errors and awkward transitions can make a semantically recognizable result expensive to repair. Track correction time as well as preference.
This creates a credible adoption decision. If captions improve recognition but increase animation cleanup, the method may be better as an ideation aid than as a production shortcut. If it reduces cleanup on the particular gestures your product needs, there is a stronger reason to integrate it.
Begin with the MotionScript project resources, which connect the paper, code, dataset and demonstrations. Reproduce the captioning path on a few known sequences before attempting the full text-to-motion pipeline. Confirm the expected skeleton representation and normalization; joint-name or coordinate mismatches can produce plausible-looking descriptions of the wrong movement.
For generation, the paper builds on T2M-GPT and augments its motion/text training pairs. An existing character-production pipeline can remain responsible for playback, retargeting and final animation review. MotionScript’s role is to improve the descriptive bridge; it does not replace those downstream steps.
Keep the LLM expansion visible and editable during a pilot. Store the original prompt, expanded movement description, generated sequence and reviewer changes together. This makes failures diagnosable: the team can see whether the interpretation was wrong or the motion model failed to realize it.
Avoid starting with a live robot or an uncontrolled interactive deployment. The research’s strongest evidence concerns generated human-motion clips. A physical system would need a separate controller and validation process with requirements this paper does not test.
MotionScript’s durable idea is that training descriptions should be grounded in what the data actually contains. More detailed language is useful when its detail corresponds to measurable movement.
For virtual-character teams, that makes it a worthwhile representation to test. We would judge it by controllability and editing effort on real production tasks, and treat the published preference studies as motivation for that evaluation rather than a guarantee of expressive generalization.
MotionScript: Natural Language Descriptions for Expressive 3D Human Motions, Payam Jome Yazdian, Rachel Lagasse, Hamid Mohammadi, Eric Liu, Li Cheng and Angelica Lim. arXiv version 5, October 16, 2025.
Test whether a model’s reasoning remains grounded in the image it is explaining.
Separate generated dialogue and content from the rules that keep a game coherent.





