AlignX tests personalized AI using constructed preference records. See why inferred preferences lag explicit profiles and how to evaluate personalization.
Select a figure to open it at full size.
An assistant may know that a user usually wants concise answers and still get the next interaction wrong. A short answer might suit a routine update; a difficult technical decision may need detail. More memory does not automatically produce better personalization.
The AlignX research explores that gap by constructing more than 1.3 million preference examples and training models to adapt their answers. Its most useful result is not simply that personalization can improve. It is that supplying a clear preference is much easier than correctly inferring that preference from behavior.
For teams building assistants, the decision is whether to rely on accumulated history, ask users directly, or introduce an explicit preference layer between the two.
Conventional preference training often aims for an answer that people generally consider helpful. Personalized alignment asks a different question: which answer suits this user, given what we know about their preferences?
Jia-Nan Li and colleagues construct a space of 90 preference dimensions, drawing on psychological models, recommendation research and online-content indicators. Each dimension has a positive, negative or neutral direction. The resulting representation is deliberately coarse: it records a tendency, not a full account of a person.
The researchers also distinguish three sources of evidence about preferences: previous written responses, choices between pairs of answers, and a descriptive persona. That distinction becomes central to the results. A direct description can effectively tell a model what to do; historical behavior requires the model to infer it first.
Most of the dataset begins with Reddit posts that have multiple responses. A language model scores the responses along the preference dimensions. The pipeline groups responses with similar patterns, then samples contrasting responses from different groups.
One response becomes the preferred answer for that constructed example, and the other the less-preferred answer. Their differences define the preference direction. The pipeline then finds responses to other posts with compatible characteristics, or generates a descriptive persona that fits the chosen direction.
This is a critical detail: the records are assembled to express coherent preferences. They are not necessarily the verified history and choices of one real individual. The paper’s million-user framing should not be read as a million-person product trial.
The construction method yields 1,311,622 examples, including 1,225,988 derived from Reddit. Smaller contributions from existing alignment datasets add dimensions such as helpfulness and safety. The authors explicitly describe the dataset as a testbed and acknowledge the shortage of real user–LLM interaction data.
The approach makes a large experiment possible. It also creates a transfer question: can a model trained on constructed, consistent personas handle a real user whose preferences are incomplete, changing or contradictory?
The paper trains two variants using direct preference optimization, a method that learns from preferred and less-preferred answers.
In-context alignment, or ICA, receives the persona information together with the question. The model must interpret that context and generate a suitable response. Despite the name, this is a trained variant, not merely an instruction added to an otherwise unchanged chatbot.
Preference-bridged alignment, or PBA, introduces an intermediate representation. A separate inference step estimates preference directions from the available persona. Those directions become a short natural-language description that guides the answer model.
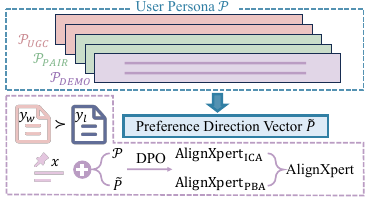
The appendix makes the transformation concrete. Directions from multiple examples are converted to numerical values and averaged. Thresholds determine whether the combined signal is positive, neutral or negative. Non-neutral directions are then translated into text, such as a preference for detailed communication. Neutral dimensions are left out.
This is not simply summarizing a conversation. It compresses evidence into a predefined preference vocabulary. That can make behavior easier to control, but information outside the vocabulary—or a preference that depends on the current task—may be lost. The method assumes its preference representation can stand apart from the particular question, an assumption a product team should test rather than inherit.
The researchers evaluate four benchmarks, including real interaction preferences in PRISM and their constructed AlignX test set. One measure asks whether training shifts the model’s preference between two candidate answers in the intended direction relative to a reference model. A separate evaluation asks GPT-4 to choose between generated answers. Neither measure is a customer-retention result or the percentage of users who are satisfied.
The clearest comparison concerns the information supplied to the model. On the AlignX test set, full-data ICA scores 91.44% with descriptive personas, but 59.63% with written-history personas and 58.48% with comparative-feedback personas. Reading a clear description is substantially easier than recovering its equivalent from behavior.
A second comparison isolates the preference-inference step. PBA scores 71.10% with combined persona information. Supplying the known target preference directions raises the score to 91.36%. That higher figure is a diagnostic condition with information the deployed system would normally need to infer—not an achieved production result.
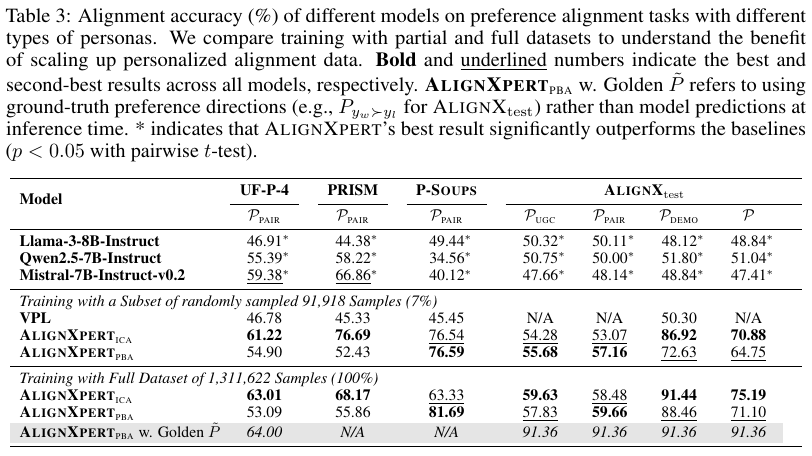
There is important counterevidence to a simple “scale fixes personalization” story. Increasing ICA training from 7% of the data to the full dataset reduces its PRISM score from 76.69 to 68.17 and its P-Soups score from 76.54 to 63.33, even as some in-distribution results improve. PBA improves on P-Soups, but is not the stronger method across every benchmark or persona type.
The preference-reversal experiment asks whether a model changes its ordering when the supplied preferences reverse. The trained variants adapt more often than the general baselines, yet adaptation remains incomplete. Remembering a preference and reliably changing course when it changes are separate product requirements.
The research supports exposing preference uncertainty instead of silently turning every interaction into a permanent user attribute.
Consider an assistant for technical documentation. A user’s repeated requests for shorter release notes do not establish that they want abbreviated incident investigations. A useful preference record would distinguish the observed pattern, its scope and an explicit setting the user has confirmed. The current request should be able to override the stored default.
That is an application of the research’s inference bottleneck. The first experiment should compare a plain assistant, an assistant with user-selected settings, and one with inferred preferences. Test users and tasks held out from training. Ask whether the inferred version improves the answer over the simpler explicit-settings version, not merely whether it differs from a generic baseline.
Include reversals, sparse histories and contradictory signals. Measure task correctness alongside preference fit. A style preference should not reward omission of necessary information, and personalization should not convert a user’s requested tone into agreement with an incorrect claim.
The authors’ AlignX repository is the starting point for inspecting their dataset and methods. It is useful when the goal is reproducing the research comparison; preserve the paper version and data assumptions when interpreting later repository changes.
For a custom training experiment, Hugging Face TRL’s DPO trainer accepts preference records with a prompt, chosen response and rejected response. Put the relevant persona or explicit preference description in the prompt. Keep evaluation users and tasks separate from training, and inspect whether labels actually reflect the intended preference. The trainer cannot establish that a constructed persona represents a real user.
Before training, an ordinary application settings store may be sufficient. Let users choose answer length or technical depth and compare the result with the current product. Add inference only where the evidence shows those settings leave a meaningful unmet need. This provides a practical baseline without recreating the paper’s eight-A100 training setup.
The strongest opportunity is a preference layer that users can understand and correct. The study makes that case by revealing how much performance changes when preferences are known rather than inferred.
Its constructed personas, model-based annotation and automated answer judging limit what it establishes about real customers. The authors’ small annotation checks are useful, but they do not establish the absence of bias across populations or contexts. A product should earn the right to infer more about a user through better outcomes, not through accumulating more personal data.
Personalization also needs boundaries independent of preference. Our guardrails analysis explains why useful assistance and policy compliance should be evaluated together.
From 1,000,000 Users to Every User: Scaling Up Personalized Preference for User-level Alignment, Jia-Nan Li, Jian Guan, Songhao Wu, Wei Wu and Rui Yan. This article uses arXiv version 3, submitted 22 May 2025.
Explore how a shared assistant should handle conflicting preferences and constraints.
See what user reviews suggest about recovery, control and satisfaction with AI products.





