Deepfake-Eval-2024 exposes detector weaknesses on circulated media. Learn what its comparisons mean and how to evaluate coverage, errors and adaptation.
Select a figure to open it at full size.
A detector can perform well on a familiar collection of manipulated faces and struggle with a compressed clip, an unfamiliar language or a new generation technique. For teams deciding whether to trust submitted media, the important question is how the detector behaves on material resembling their incoming cases.
Deepfake-Eval-2024 investigates that gap using images, audio and video that circulated online during 2024. Nuria Alina Chandra and colleagues compare established detectors on this material with their earlier benchmark performance, then test what happens after adapting models to the new data. The results support a concrete change in evaluation practice: test the intake pipeline and its failure cases, not just a model’s published score.
The dataset contains 45.1 hours of video, 56.5 hours of audio and 1,975 images drawn from 88 websites and social platforms. It includes 52 languages, although English accounts for most of the content. The collection originated in material submitted or identified for authenticity assessment, including TrueMedia.org’s workflow.
That makes it closer to an investigation queue than a random sample of the internet. It cannot tell us what percentage of all online media is fake. The visual portion also concentrates on realistic human-face content; a successful detector on this collection is not thereby validated for every kind of manipulated document, landscape or product image.
Labels required investigation, not merely trusting the submitted allegation. The researchers used evidence such as an identifiable original source and generation provenance, with uncertain cases excluded. Some audio decisions also relied partly on agreement between commercial detectors when stronger provenance was unavailable. That makes the labels useful but not infallible, and introduces a possible advantage for detector behavior that helped establish them. The data collection and annotation sections describe these choices.
The authors evaluate three open-source detectors for each medium. The original comparison below puts their scores on the new collection beside scores on the datasets used in earlier publications.
Focus on the AUC columns: they describe how well a detector ranks manipulated material above genuine material across possible cutoffs. Higher is better; these values are not the percentage of files correctly classified at a chosen operating threshold.
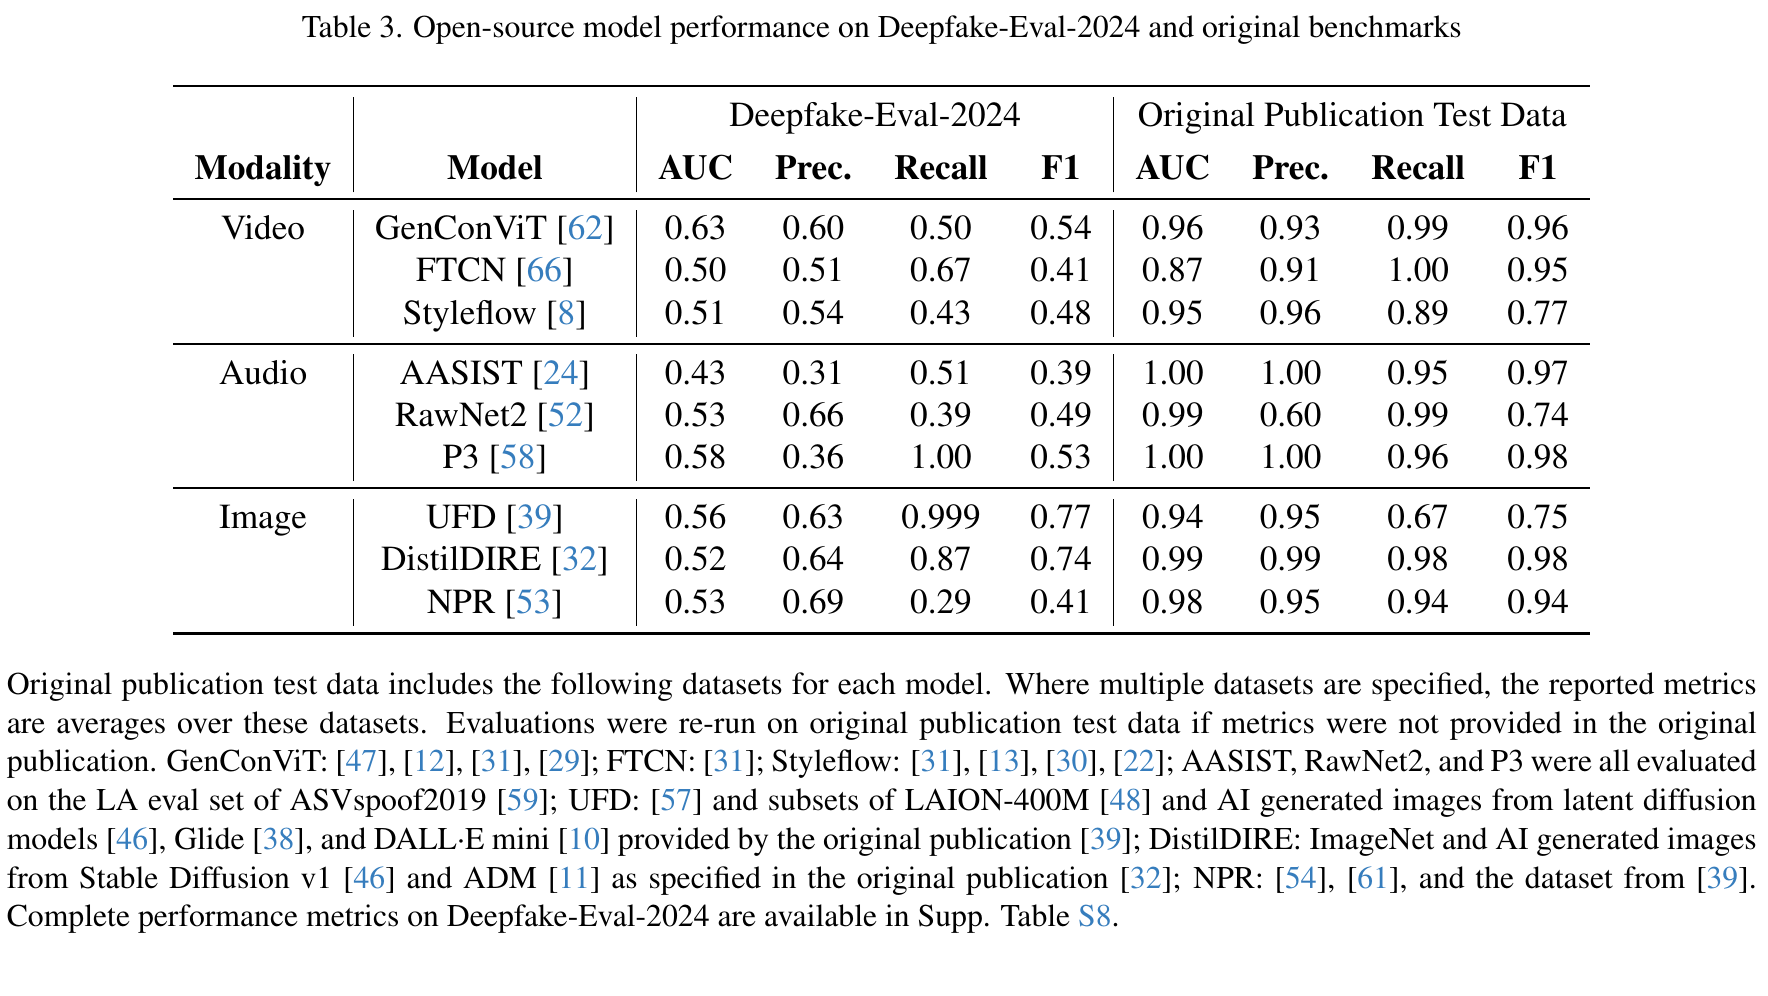
For example, the video detector GenConViT falls from 0.96 on its earlier benchmark comparison to 0.63 on Deepfake-Eval-2024. The image detector NPR falls from 0.98 to 0.53. These are substantial changes, but they are not a measured 33% or 45% fall in real-world detection accuracy. The datasets, decision thresholds and input handling differ.
The reader implication is straightforward: an earlier benchmark result does not establish that a detector can separate authentic and fabricated submissions in your queue. Even a technically correct model integration can fail because the material has changed.
There is a further operational gap. Files on which a detector cannot produce predictions are excluded from that detector’s reported performance metrics. A system that handles only easy inputs may look better in a score table than it does as an intake service. Coverage—the fraction of incoming files that actually receive a usable result—must be reported alongside detection quality.
The researchers split the new collection into training and testing portions and fine-tune the open-source models. This asks whether exposure to more representative material can recover some of the lost performance.
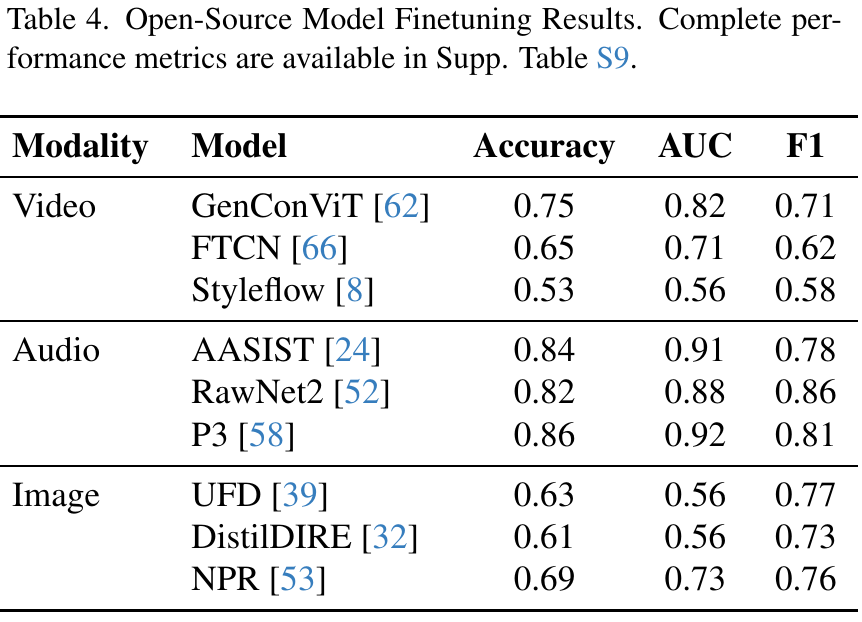
GenConViT’s AUC reaches 0.82 after adaptation, a result consistent between the main and supplementary tables. The image-detector results need more caution: the main table and appendix disagree on NPR’s fine-tuned scores. That row cannot support a reliable estimate of improvement. The consistent video result nevertheless suggests that data selection is part of the solution. They do not show that the detector will retain that performance on the next wave of manipulation methods or on another organization’s submissions.
The table also illustrates why one aggregate metric is insufficient. A model that predicts almost everything as fake can obtain a superficially respectable score on a collection containing many fakes while being unusable for protecting genuine users from false accusations. The paper explicitly excludes models with single-class predictions from parts of its error analysis.
The authors also evaluate commercial systems using a December 2024 snapshot. Those results are anonymized and historical. They cannot support a current vendor ranking or a claim that one named provider solves the problem.
The study’s examples and subgroup analysis identify problems hidden by the average: unfamiliar visual generation methods, scenes with several people, audio with background music or silence, and differences across language. An audio pipeline that scores short segments also needs a policy for turning conflicting segment scores into one case-level decision.
Suppose a submitted video contains genuine footage with a brief manipulated passage. A file-level average could dilute the suspicious segment; treating every flagged frame as decisive could produce too many false alarms. This is an implementation scenario motivated by the paper, not a result the authors claim to have solved. The right aggregation rule depends on what evidence an analyst can review and what action follows a flag.
Equally, “no face found,” “unsupported codec” and “model timed out” are not authenticity judgments. A production workflow should preserve those outcomes rather than silently turning them into a clean bill of health.
Use the authors’ Deepfake-Eval-2024 repository as the starting point for dataset access and evaluation details. Review its access conditions before incorporating any media. A research benchmark and a company’s own authorized case collection play different roles: the former checks comparability, while the latter tests relevance to the actual service.
The first useful framework can be an evaluation harness around existing detectors. Preserve the original media and log preprocessing, model version, score, chosen threshold, prediction failures and the evidence behind the reference label. Separate training cases from final testing, including related versions of the same underlying clip, so adaptation does not become recognition of material already seen.
Choose thresholds using the consequences of mistakes. For an analyst-assistance tool, measure how many confirmed manipulations reach the review queue and how much genuine material fills that queue. Keep file coverage and processing failures visible. Evaluate languages and input conditions separately, then test on later material before widening use.
A detector score should direct investigation, with access to source provenance and human review for consequential judgments. It is not a general truthfulness score: genuine footage can be miscaptioned, and synthetic content can be openly disclosed. For a related distinction between a benchmark score and a useful operational decision, see our AI guardrails analysis.
The strongest lesson is not that detection is futile. It is that collecting representative evidence and maintaining a credible test set are central parts of the product.
Prioritize a workflow that can explain which material it handles, where it fails and what a flag means. Adaptation is worth testing, but confidence should come from later, independent cases and usable review outcomes—not a recycled headline accuracy figure.
Deepfake-Eval-2024: A Multi-Modal In-the-Wild Benchmark of Deepfakes Circulated in 2024, Nuria Alina Chandra and colleagues. Version 5, May 27, 2026. This article uses version 5 and identifies the material table inconsistency in its discussion of fine-tuning. Tables 3 and 4 are reproduced from the original.
Look beyond a high intrusion-detection score to attack classification and operational alert volume.
Explore why indirect descriptions can bypass name-based image safeguards.





