Why flexible models can generalize: original polynomial experiments explain capacity, regularization and what teams should test before trusting a model.
Select a figure to open it at full size.
A neural network can have enough flexibility to memorize its training data and still make useful predictions on new examples. That seems contradictory only if flexibility is treated as the whole explanation of learning.
In Deep Learning is Not So Mysterious or Different, Andrew Gordon Wilson argues that many supposedly unique mysteries of neural networks become more understandable when viewed through established ideas about generalization, regularization and representation. The paper is a position article supported by examples and existing research. Its claim is not that every trained network is understood or trustworthy.
For technical leaders, the practical question is sharper than “is AI a black box?” It is whether the model’s preferences, training process and evaluation explain why it should work on the data the business will actually encounter.
Model capacity describes the range of functions it can represent. Inductive bias describes which solutions it tends to prefer. Two learning procedures can have access to the same broad function class and still select very different answers.
Wilson illustrates this with high-degree polynomials. A sufficiently flexible polynomial can follow a complicated curve or memorize irregular observations. But a regularizer can penalize higher-order terms more strongly, encouraging a simple relationship when the data supports one. The capacity remains available without every fit using all of it equally.
That is a soft preference, not a hard prohibition. A strictly linear model cannot express a curved relationship. A flexible model with a preference for simplicity can fit a near-linear relationship when appropriate and use additional complexity when the evidence warrants it.
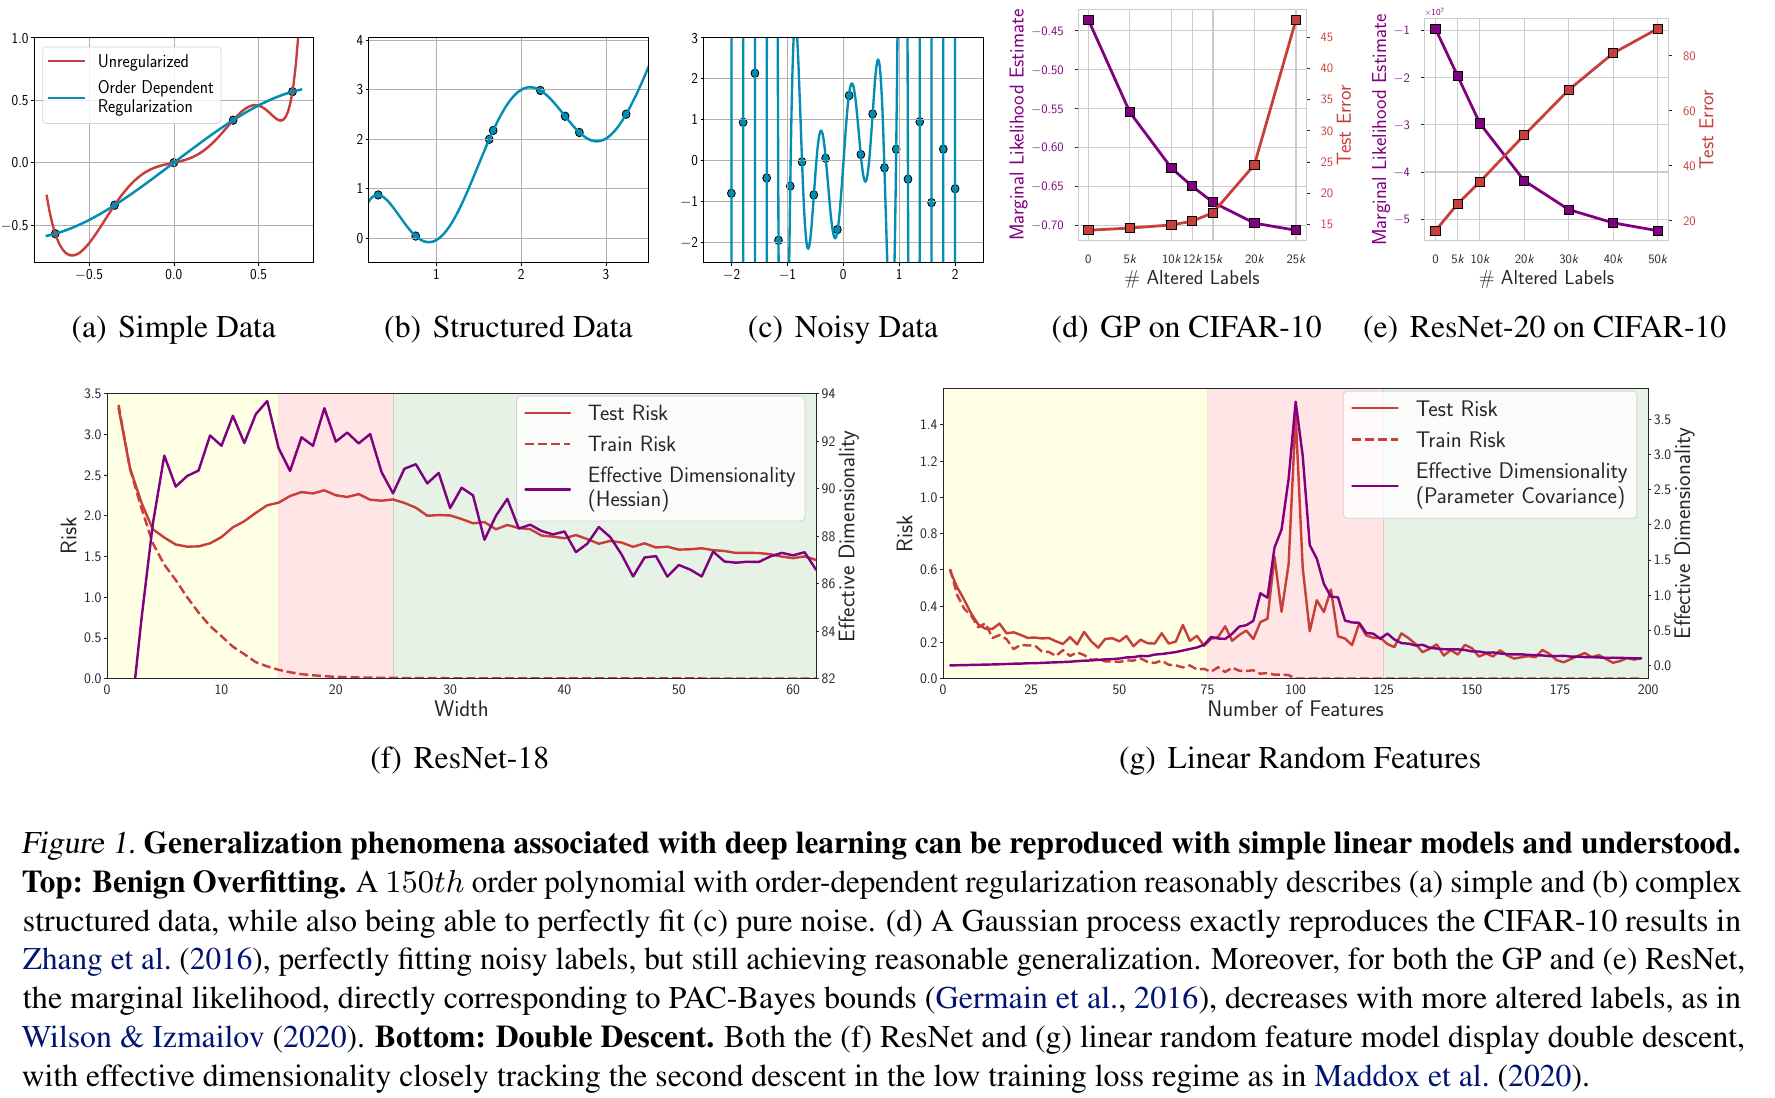
The important conclusion is limited but useful: demonstrating that a model can memorize random labels does not, by itself, explain how it will behave on a structured task. A convincing evaluation has to examine the solutions produced by the actual training process.
The paper’s polynomial experiment compares a degree-two model, an unregularized degree-fifteen model and a regularized degree-fifteen model. It tests them on three underlying functions: a simple polynomial, a more complex polynomial and a cosine relationship.
Training-set size ranges from two to 100 observations. The experiment repeats fits and evaluates predictions on separate test points, showing average errors and their variation. This is a controlled illustration of the argument, not a benchmark of large language models.
The restrictive model has an advantage when its shape matches the task, but cannot represent every relationship well. The unregularized flexible model can behave poorly with limited data. The regularized flexible model combines access to a richer function class with a preference that helps it use that flexibility more selectively.
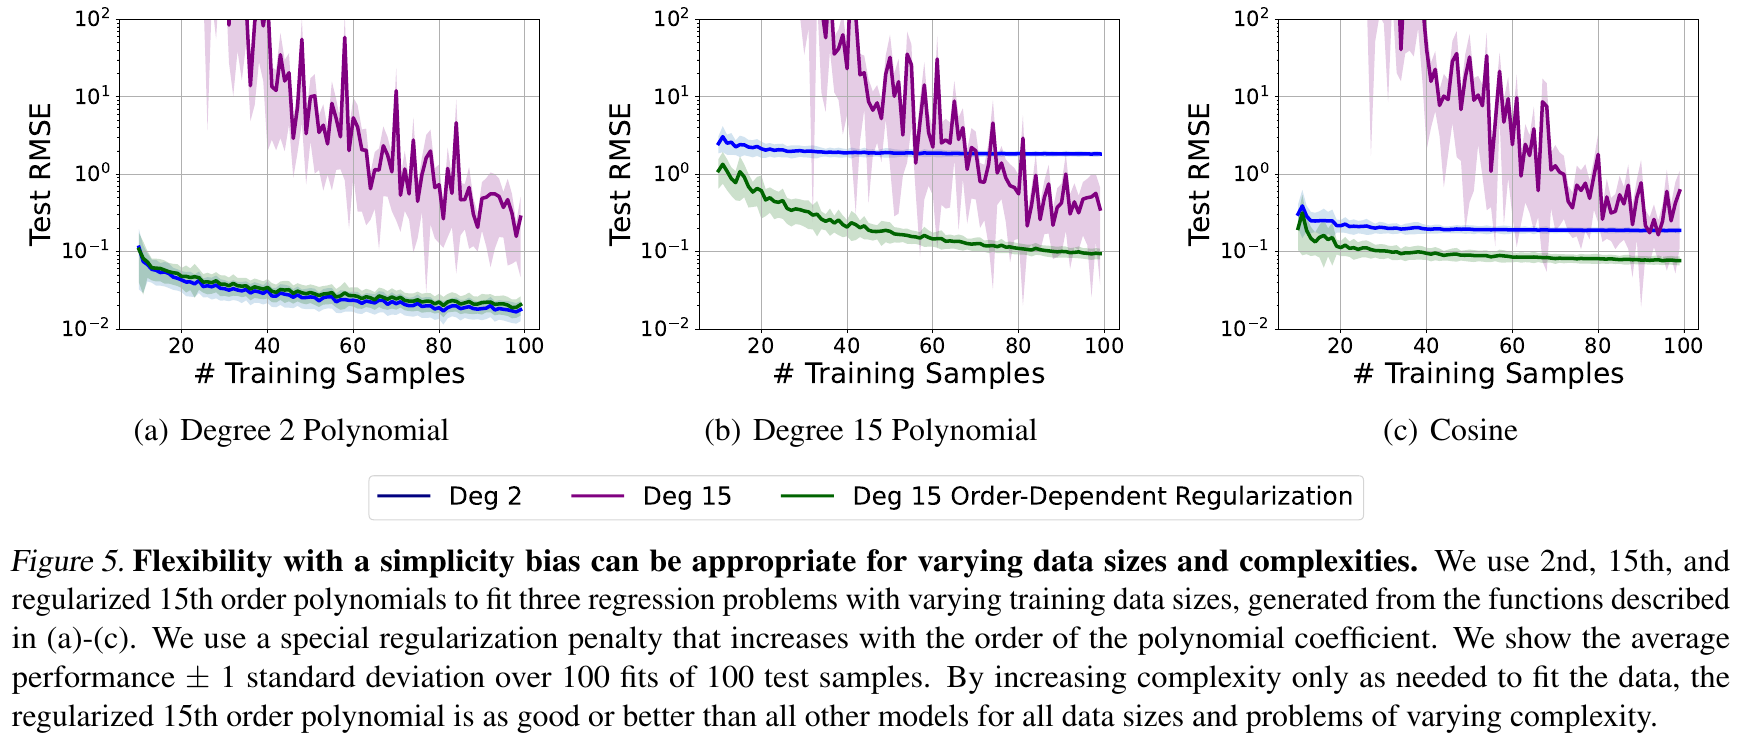
For a reader deciding between models, the lesson is to compare learning procedures rather than parameter counts alone. The architecture, regularization, initialization and optimization process all influence which solution emerges. “Smaller” and “simpler in its predictions” are not interchangeable descriptions.
A familiar picture of overfitting shows test error falling and then rising as a model becomes more flexible. Some modern experiments show another decline after that rise: the pattern called double descent.
One explanation centers on the point where the model can just interpolate the training data. Around that threshold, fitting every observation can require unstable solutions. With more available parameters, a fitting procedure may find an interpolating solution with a more favorable preference, such as a smaller norm.
Wilson emphasizes that related behavior can arise in simpler settings, including linear models with constructed features. It is therefore not sufficient evidence that neural networks obey an entirely separate theory of learning.
Nor is it a purchasing rule. A team cannot infer that buying a larger model will always move it into a better regime. The pattern depends on the data, representation and fitting procedure. The useful response is to measure the relevant learning curve and compare the actual alternatives.
The argument does not reduce deep learning to an ordinary fixed-feature model. Learned representations change the coordinates in which a task becomes easier to solve. Images that differ substantially at the pixel level may share a useful representation of an object or its orientation.
That can make the same underlying relationship easier to learn from available examples. Wilson connects this capability to broader ideas about adaptive representations rather than treating it as a property without precedent. The practical question becomes what information the representation preserves and whether that information remains useful when conditions change.
A representation that works on familiar images may rely on a background cue that disappears in deployment. Generalization on a held-out sample from the same distribution does not establish robustness to that change. Understanding the broad learning principle does not explain every individual prediction or eliminate the need for domain-specific testing.
For a prediction project, start with a simple baseline and a more flexible alternative. Keep the data split and target fixed. Compare performance as training data increases and as regularization changes. That shows whether added flexibility is helping, whether the model is data-limited, and whether a preference in training improves the result.
Inspect the cases that matter operationally, not just average error. Hold out a later time period or a changed operating condition where appropriate. If the flexible model wins on familiar data but loses on the conditions expected in deployment, the parameter count is not the decisive fact.
The same reasoning should temper claims about language models. A theory of generalization does not establish that an answer is factually correct or that a system follows a policy. Those are separate tasks requiring their own evidence, as discussed in AI guardrail evaluation.
Scikit-learn’s Ridge regression is a useful baseline for exploring how an L2 penalty changes a fitted model. Its standard penalty is not automatically the order-dependent polynomial regularizer in Wilson’s example; reproducing that experiment requires matching the feature construction and penalty rather than substituting a library default.
A minimal comparison can use the same train-validation-test split for a low-degree model and a richer feature model across several regularization strengths. Select settings on validation data and report the final test result once. Save the full learning curves, including settings that performed poorly, so the conclusion does not depend on one selected point.
Advance to a more complex architecture when it improves the relevant held-out conditions enough to justify its operational cost. No experiment was executed for this article; the proposed comparison applies the paper’s argument to a team’s own data.
The paper replaces an unhelpful choice between “deep learning is magic” and “deep learning is fully explained” with a more productive question: which properties of the data and learning procedure account for the observed behavior?
That question improves model selection. Capacity matters, but so do the preferences that guide fitting and the representation that makes a task learnable. A model earns trust through evidence on the required task and conditions, not through either its size or the claim that its generalization is no longer mysterious.
Andrew Gordon Wilson, Deep Learning is Not So Mysterious or Different, arXiv version 2, July 10, 2025; ICML 2025 position paper. This corrects the malformed research link in the earlier article.
See why a model that ranks answers well may still provide a poor training signal.
Explore how confidence scores can support escalation or abstention instead of automatic acceptance.