How model, hardware, datacenter and electricity choices affect AI training emissions. Learn to compare equivalent workloads and measure the right boundary.
Select a figure to open it at full size.
An AI project does not become a sustainability project because it optimizes something. Its own electricity use, the emissions associated with that electricity and the operational benefit it produces are separate quantities. For technical leaders, the first useful question is concrete: can the same job be completed at the required quality with less energy and lower emissions?
David Patterson and colleagues at Google and UC Berkeley investigated that question for neural-network training. Their research breaks a large, vague carbon claim into choices a team can inspect: the model, the processor, the datacenter and the electricity supply.
This revision replaces the earlier article’s economy-wide claims with research on AI’s operational footprint. It does not claim that adopting AI by itself moves a company or country toward net zero.
Training energy depends on how long the job runs, how much equipment it uses, actual power consumption and the datacenter overhead needed to operate that equipment. Emissions then depend on the carbon intensity of the electricity associated with the job.
That separation matters. A faster accelerator can lower energy consumption if it completes the same task efficiently. Moving the unchanged job to a cleaner electricity supply can lower attributed emissions without reducing the job’s energy use. Improving both compounds the benefit, but the accounting should show which change produced which result.
The paper’s worked comparison holds the accuracy goal broadly constant while comparing Transformer and Evolved Transformer training across different hardware and datacenter assumptions. It gives the reader more than an assertion that efficient AI is possible: it exposes the inputs behind the estimate.
The starting configuration in Table 1 uses Transformer (Big), P100 GPUs and an average US datacenter. The final configuration uses Evolved Transformer (Medium), TPU v2 hardware and Google’s Iowa datacenter. The authors report approximately the same task accuracy, while training electricity falls from 316 kWh to 30 kWh.
Gross training emissions fall from 0.1357 to 0.0143 metric tons of CO₂ equivalent—about 136 kg to 14 kg. When the paper also applies its local, hourly carbon-free electricity accounting, the final estimate falls to 0.0024 tons, or 2.4 kg. The widely cited roughly 57-fold improvement uses that final net figure.
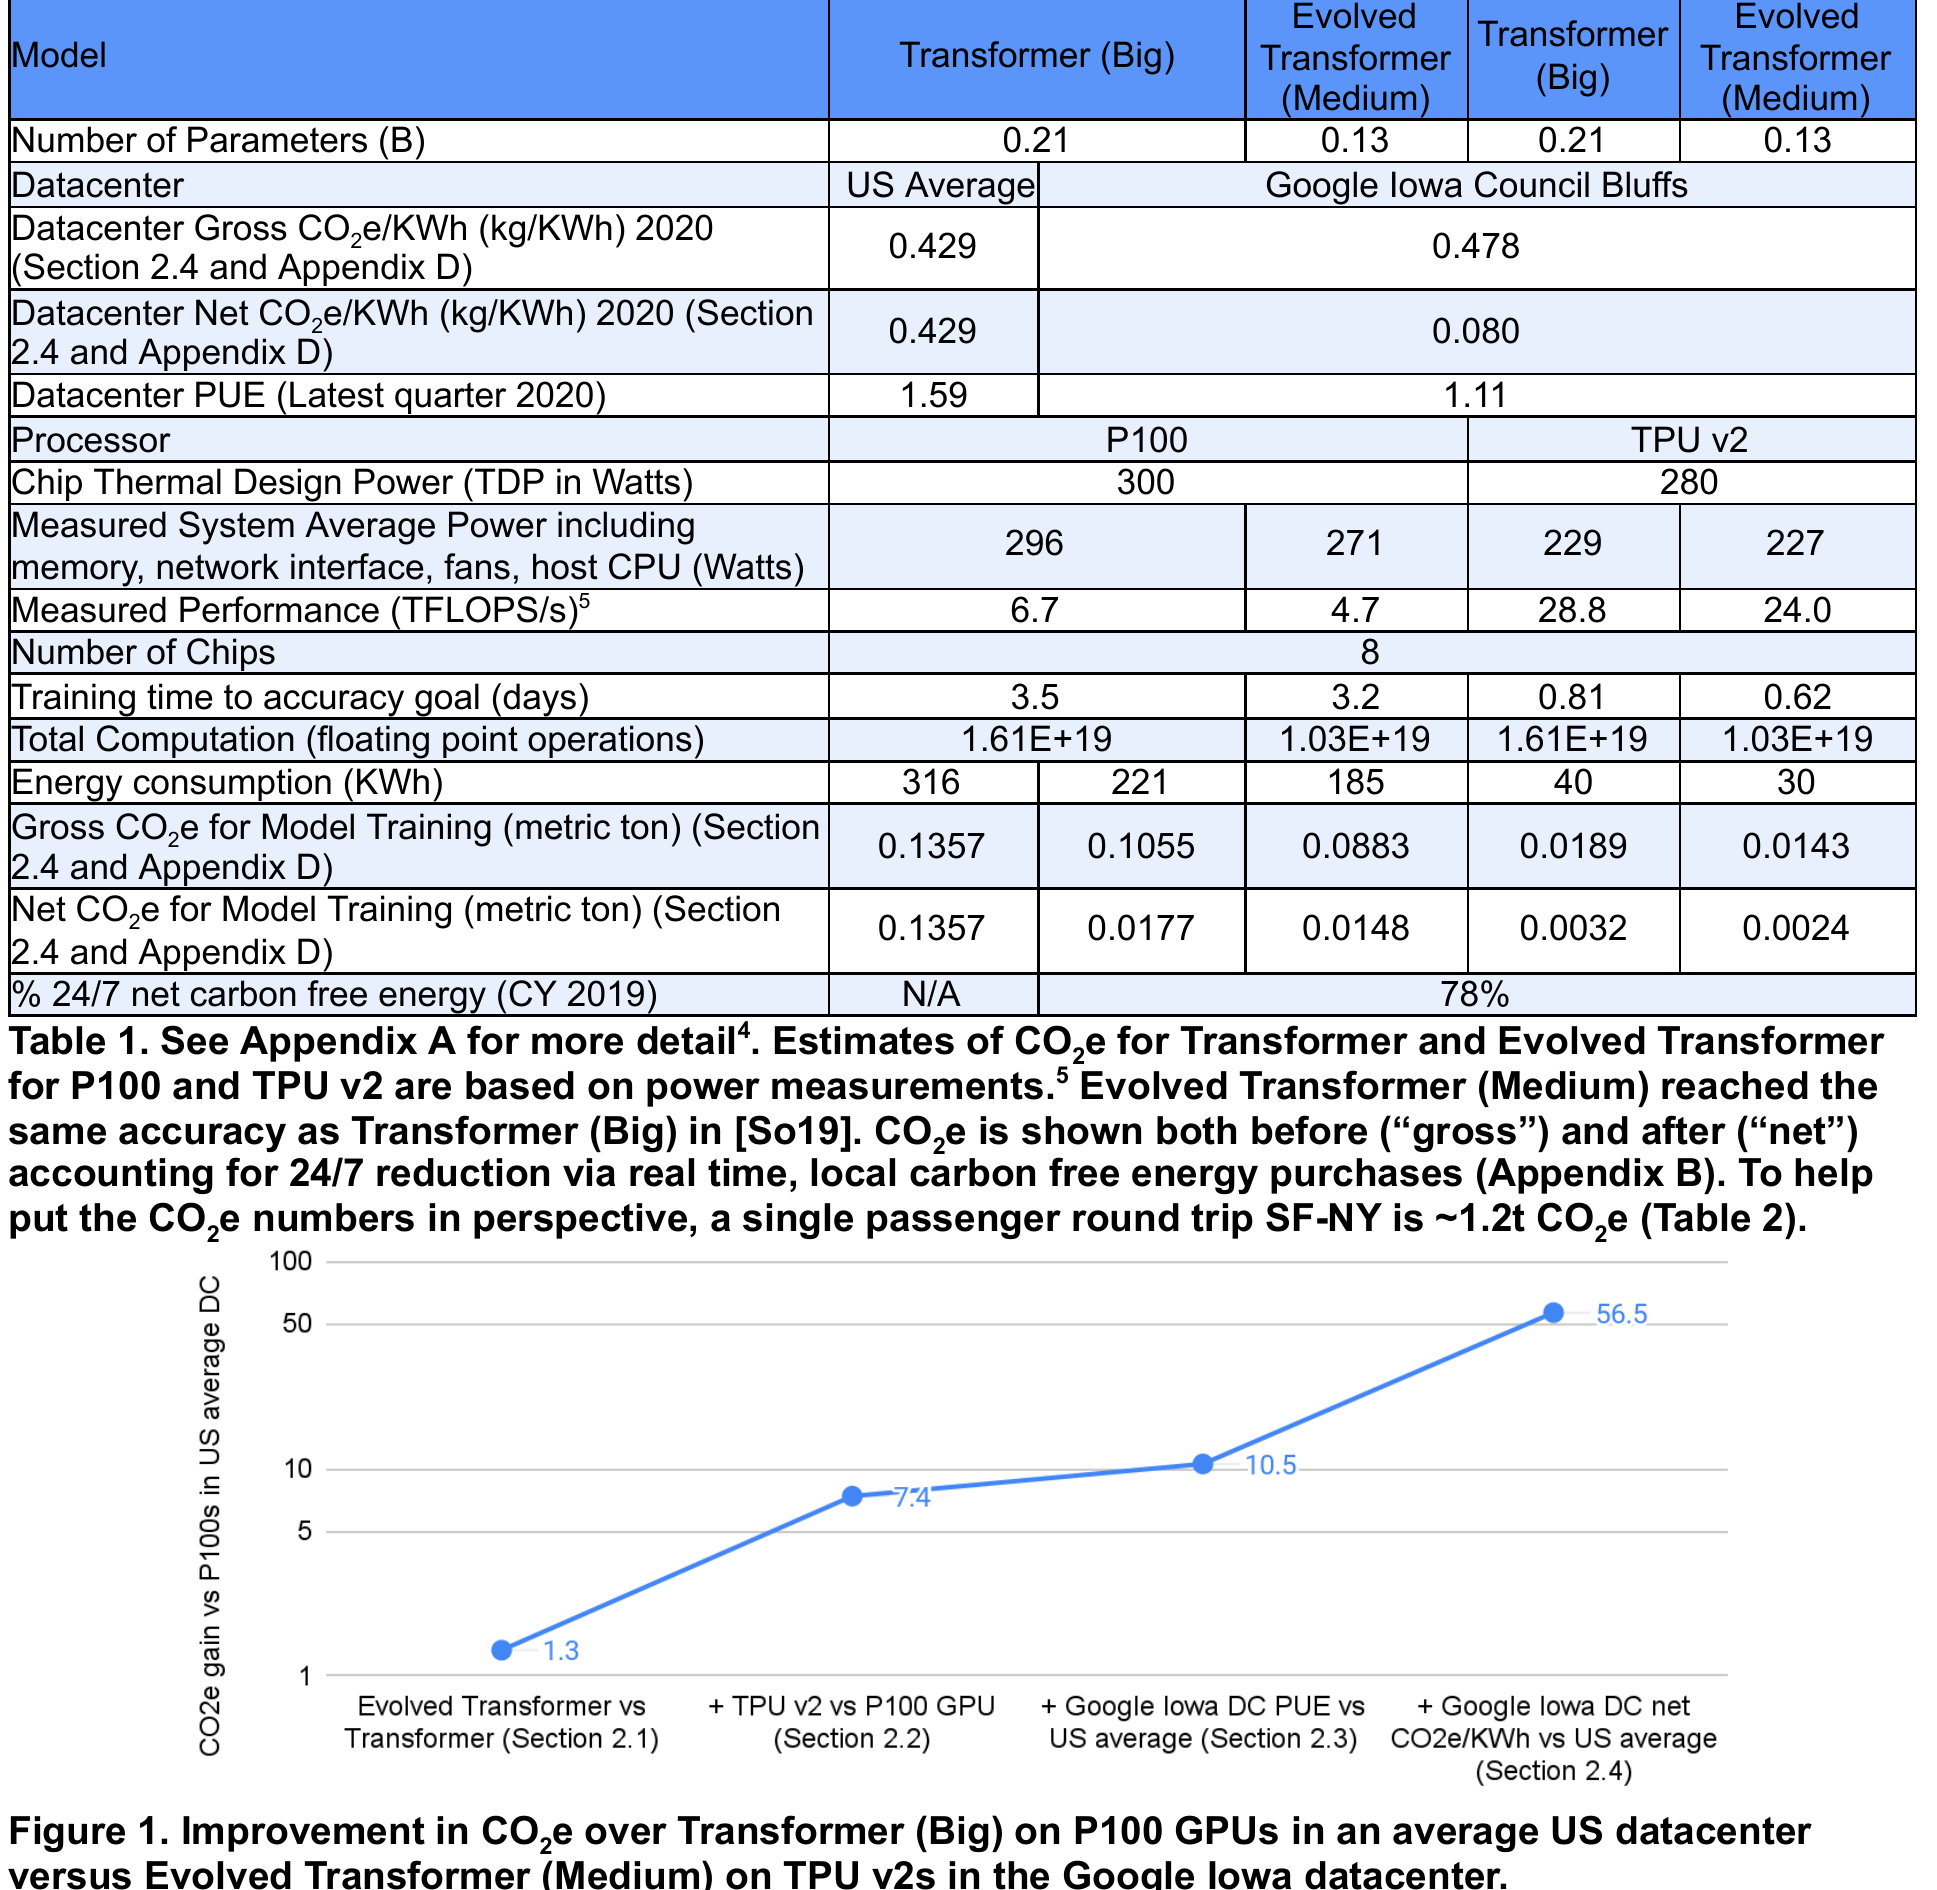
Read across the table rather than treating the final point as a universal saving. The model performs less computation; the accelerator completes it more efficiently; datacenter overhead is lower; and the net-emissions calculation uses a different electricity accounting basis. A team changing only one of those factors should not expect the combined result.
The distinction between gross and net is especially important. The paper’s net calculation credits carbon-free energy matched within the same local grid and hour. It is not a claim that the equipment consumes no electricity, or that a purchase elsewhere at another time makes its physical operation emission-free. The accounting appendix explains this boundary.
These are historical measurements and estimates, largely involving Google systems. They are useful evidence about the mechanism, not a current cloud-provider ranking. A present-day decision needs the workload’s actual hardware, utilization, location and electricity data.
The paper also compares several large language models and shows why model size alone cannot determine energy use. Sparse models can contain many parameters while activating only a small portion for each token. Conversely, a smaller dense model may use all its parameters on every step.
Those models do not perform identical tasks or train to an identical quality target, so their totals should not become a leaderboard of “greenest AI.” The practical lesson is to measure the computation the application actually performs. Parameter count, advertised chip power and training duration in isolation leave out too much.
The same reasoning changes how to evaluate a model upgrade. A larger model might need more energy per request but answer successfully with fewer retries. A smaller one might be cheaper per call but trigger extra calls and manual correction. Measure energy per successfully completed task as well as the total workload.
The paper focuses on operating computers and datacenters. It does not include manufacturing and recycling the hardware. Its training comparisons also do not by themselves capture a service’s lifetime inference, repeated experiments or retraining.
For a frequently used product, serving the model can become a major part of its footprint. An efficient training run is therefore insufficient evidence for calling the product low-carbon. Likewise, lower energy per request can be offset by a large increase in request volume. Both unit efficiency and absolute consumption belong in the operating review.
This distinction is useful alongside AI logistics research: optimizing a proxy such as distance or computation is only the first step toward establishing an emissions benefit.
Start with a workload the team can repeat: a scheduled training job, a batch classification run or a defined inference test set. Fix the quality threshold and record model version, equipment, duration, energy estimate and location. Then change one factor at a time.
For model selection, compare successful outputs at the same quality threshold. For hardware, include the complete run rather than a short peak-throughput test. For scheduling, determine whether a flexible batch job can move in time or location without violating data-location requirements, deadlines or service commitments.
A credible adoption decision needs both a comparable result and an accounting boundary. Lower estimated emissions are useful; they are not proof of a company-wide net-zero outcome. If the cleaner option substantially increases retries or requires extra always-on capacity, include those effects before declaring a saving.
CodeCarbon provides tooling to track compute energy and estimate associated emissions. Use it to create a consistent experiment record, while checking what is measured directly, what is estimated and which location assumptions apply. Its output is not a substitute for complete organizational carbon accounting.
An existing job runner and metrics store can hold the rest: start and finish times, accelerator count, quality results, requests completed and retries. Where power telemetry is available, reconcile it with the estimate. Where it is unavailable, retain the assumptions so later comparisons use the same basis.
The minimum useful trial compares the current configuration with one proposed change over repeated equivalent runs. Accept the change when quality and service targets hold, energy or emissions improve under a stated method, and the result survives the full workload. Report both the percentage difference and the absolute quantities; a large percentage on a tiny experimental job may have little operational significance.
AI sustainability becomes manageable when it is attached to a workload and a measurable outcome. This research shows how architecture and infrastructure decisions can materially change the footprint of training. Apply that discipline before making wider claims: measure the whole service, keep energy separate from carbon accounting, and compare alternatives that deliver the same useful result.
David Patterson and colleagues, Carbon Emissions and Large Neural Network Training, arXiv version 3, April 23, 2021, including its measurement and accounting appendices. The historical figures above are not estimates for today’s models or datacenters.
Compare inference-routing decisions when the preferred accelerator is unavailable.
Connect shorter planned routes to the operational measurements needed for sustainability.
Explore whether a building controller can reuse earlier learning when its available controls change.





