Where LLMs fit in drone perception and mission planning: original research diagrams, integration examples, simulation tools and deployment constraints.
Select a figure to open it at full size.
A drone operator can describe a mission in ordinary language: inspect a structure, find a landmark or report a change. Turning that request into a successful flight still requires perception, spatial reasoning, planning and reliable control. Understanding the sentence is only one part of the job.
UAVs Meet LLMs surveys research connecting foundation models with unmanned aerial vehicles and proposes an architecture for coordinating those capabilities. Its value for engineering leaders is a map of the integration problem: which parts can benefit from language or vision models, which need specialized tools, and where the interfaces create risk.
This is a survey and architectural proposal. It does not demonstrate one complete system that safely performs every application it describes.
Language models can help translate a loosely expressed goal into a sequence of tasks. Vision models can connect words with objects in camera images. Neither capability, by itself, supplies a reliable estimate of where the aircraft is or a controller that keeps it within physical limits.
The survey’s functional breakdown distinguishes perception, navigation, planning, control, communication, interaction and payload. Those distinctions matter when evaluating a demonstration. A system that recognizes a requested object has solved a different problem from one that reaches it, avoids obstacles and completes the mission within its energy budget.
For a team considering AI-assisted inspections, the first question is therefore specific: is the current bottleneck translating the operator’s request, interpreting imagery, choosing the next observation point, or executing the flight? A language interface can improve the first while leaving the others unchanged.
The paper provides a useful visual example using a synthetic aerial scene from SynDrone. The same image is processed for object detection, segmentation and depth estimation.
Grounding DINO receives the target word “car” and places boxes around candidate cars. SAM partitions the scene into image regions. ZoeDepth produces an estimated depth image. These outputs answer different questions: where are likely objects, which pixels belong together, and how is the scene arranged in depth?

A detection box does not establish the object’s exact three-dimensional location. A segmentation mask does not tell the aircraft whether a region is safe to enter. An estimated depth map still needs evaluation in the intended operating conditions. The value comes from connecting these representations to the navigation system without treating any one of them as complete knowledge of the environment.
This example also explains why “use a multimodal model” is not a full architecture. The team must decide which outputs are needed, how their uncertainty is represented, and what happens when they disagree.
The authors organize their proposal into five modules: data, foundation models, knowledge, tools and agents. Their original integration diagram makes the division of responsibilities visible.
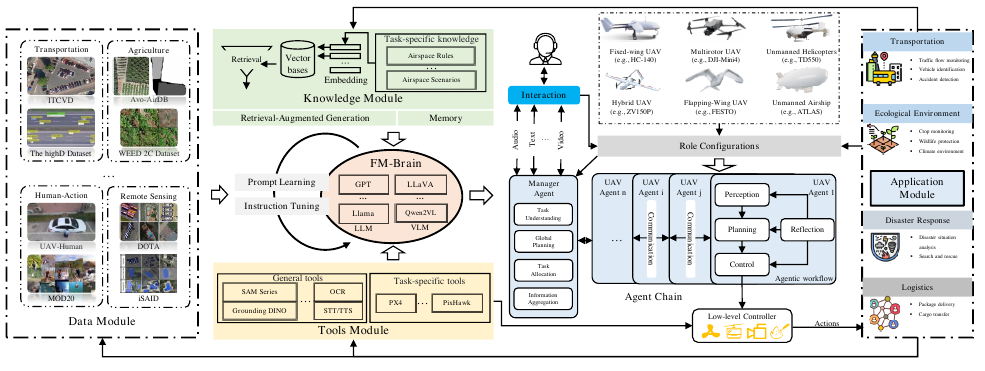
The data module prepares task-specific examples. A perception dataset may pair images with captions or object descriptions; a planning dataset needs sequences that connect a goal with actions and observations. These are not interchangeable training assets.
The model module selects and adapts models for the relevant input and task. A language model may interpret a request, while a vision-language model processes a request alongside imagery. The proposal discusses prompting and fine-tuning, but does not establish that every deployment needs either a large model or custom training.
The knowledge module supplies external context, such as scenario information and environmental records. Retrieving that context can improve a plan, but the application still needs to establish its freshness and authority. A fluent summary of stale information is not an updated view of the world.
The tools module supplies specific capabilities: visual processing, speech interfaces and flight-system interfaces. The agent does not need to invent every operation; it selects from capabilities the system exposes.
Finally, a manager agent interprets the overall mission and allocates work, while vehicle-level workflows connect perception, planning and control. Observations feed back into the plan. In a multi-vehicle setting, coordination also requires status updates and communication between participants.
The practical implication is an interface problem. The output of one stage needs a defined meaning that the next stage can check. A proposed observation location should carry constraints and supporting evidence, not just persuasive text.
The survey describes TypeFly, which translates natural-language requests into a compact mission-planning language called MiniSpec and includes a mechanism for replanning when circumstances change. Its useful architectural idea is to mediate between open-ended language and a restricted executable representation. The article does not need to reproduce its mission commands to explain why that boundary matters.
It also describes Swarm-GPT, where generated waypoints pass through a model-based planning component that accounts for physical constraints and collision avoidance. The language model proposes; another component checks and shapes the motion plan. The survey discusses simulation demonstrations, which should not be treated as a general real-world safety guarantee. The planning and control sections describe these systems.
These examples are reports of prior work assembled by the survey, not new head-to-head experiments by its authors. The paper’s broad catalog of models and datasets is useful for locating research, but it cannot determine which complete stack will work best on a particular aircraft or site.
The authors identify computation, response delay, hallucinations and infrastructure as obstacles. They connect directly to deployment choices.
Sending imagery to a remote model changes the latency and communication assumptions. Running a model onboard changes compute, power and thermal requirements. Adding another reasoning step may improve a plan while making it arrive too late to use.
Uncertainty also accumulates across stages. A mistaken landmark identification can produce a coherent plan toward the wrong location. A language model may not know that the underlying observation is weak unless the system explicitly carries that information forward.
A useful evaluation therefore separates semantic success from operational success. Did the system understand the request? Did it identify the right target? Was its proposed plan valid? Did execution finish within the intended constraints? A single overall success score can conceal which part needs work.
For teams already using PX4, its simulation support provides a place to exercise flight-system behavior before hardware testing. It is a simulation foundation, not a language-model planner or proof of real-world safety.
Start by keeping the existing mission system as the baseline. Add a language layer that produces a structured proposal for review, then validate that proposal against the same constraints as an ordinary mission. The useful first comparison is whether interpretation improves without increasing invalid plans, operator corrections or unacceptable delay.
Use the survey’s research index to find task-matched methods and datasets. Choose a navigation benchmark if the intended change concerns navigation; an object-detection dataset cannot establish mission completion. Preserve the surveyed model versions when comparing historical results with a newer implementation.
An existing controller and deterministic validation code may be the right execution foundation. Add agent coordination only when the task actually requires dynamic allocation or replanning. A fixed inspection route with a clearer user interface may not need a multi-agent architecture at all.
The near-term opportunity is a better bridge between human intent and established flight capabilities. The evidence is more useful when read as a set of interfaces to engineer than as a promise that language models can replace the flight stack.
A convincing prototype should make its boundaries visible: what the model interprets, what the planner checks, what the controller executes and when the operator must intervene. If those responsibilities blur together, a polished demonstration can hide the hardest engineering work. The same issue appears in AI agent orchestration, where useful components still need reliable coordination.
UAVs Meet LLMs: Overviews and Perspectives Toward Agentic Low-Altitude Mobility, Yonglin Tian and colleagues. This article uses arXiv version 2, submitted 25 March 2025.
Optimize drone routes with battery reserves, charging and the full mission in view.
Check what changes as a trained model is exported and deployed on real hardware.





